Week 5 - Curve fitting
AIM :
To write a code to perform curve fit for the given cp and temperature data
What is curve fitting?
curve fit is the process of constructing a curve or a mathematical function that has the best fit to that data points. The goal is to model the underlying relationship between the independent and dependent variables as accurately as possible. Curve fitting is commonly used in science, engineering, statistics, and data analysis. There are several types of curve fitting, each suited to different scenarios and data types,
-
Linear Regression:
- Type: Linear curve fitting.
- Equation: Y = mx + b (where Y is the dependent variable, x is the independent variable, m is the slope, and b is the y-intercept).
- Use: Linear regression is used when the relationship between variables is expected to be linear. It's commonly used in statistics, economics, and social sciences.
-
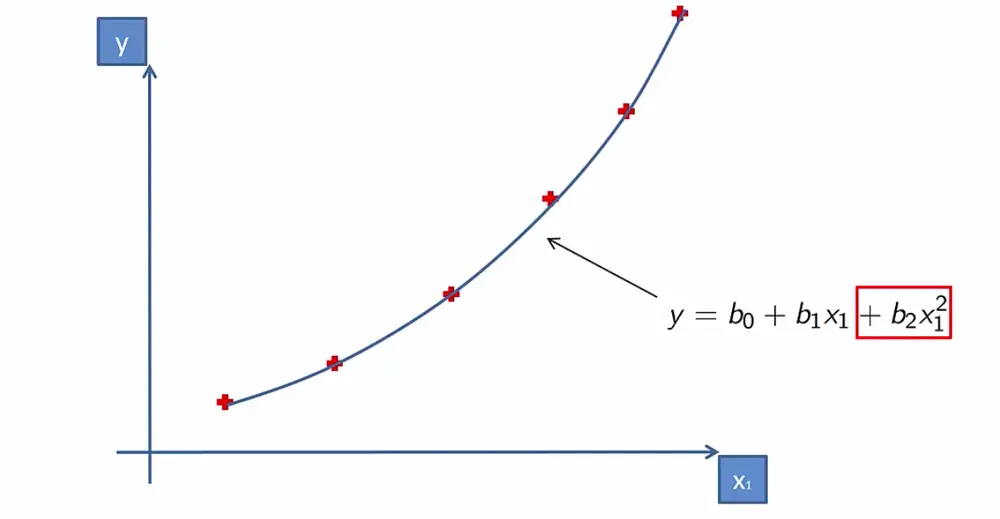
Polynomial Regression:
- Type: Polynomial curve fitting.
- Equation: Y = a0 + a1x + a2x^2 + ... + an*x^n (where Y is the dependent variable, x is the independent variable, and a0 to an are coefficients).
- Use: Polynomial regression is used when the relationship between variables is nonlinear. It's useful for approximating complex relationships.
-
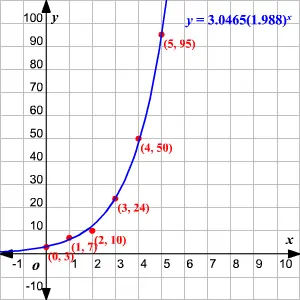
Exponential Regression:
- Type: Exponential curve fitting.
- Equation: Y = a * e^(bx) (where Y is the dependent variable, x is the independent variable, a and b are coefficients, and e is Euler's number).
- Use: Exponential regression is used when data follows exponential growth or decay patterns, such as in population growth, radioactive decay, or financial modeling.
-
Logistic Regression:
- Type: S-shaped curve fitting.
- Equation: Y = 1 / (1 + e^(-bx)) (where Y is the dependent variable, x is the independent variable, b is a coefficient, and e is Euler's number).
- Use: Logistic regression is used for binary classification problems, where the dependent variable is categorical and has two possible outcomes. It's commonly used in machine learning and epidemiology.
-
Nonlinear Regression:
- Type: Fitting data to a user-defined nonlinear function.
- Equation: Depends on the chosen nonlinear function.
- Use: Nonlinear regression is used when the relationship between variables is not adequately described by linear or polynomial functions. It allows fitting data to custom models.
-
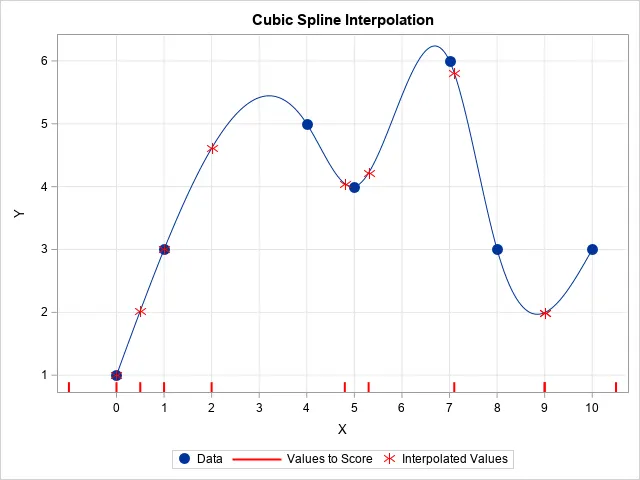
Splines and Interpolation:
- Type: Piecewise curve fitting using polynomials or other functions.
- Equation: Varies based on the type of spline or interpolation method.
- Use: Splines and interpolation are used to approximate a smooth curve that passes through a set of data points. They are often used in computer graphics, computer-aided design, and geophysics.
-
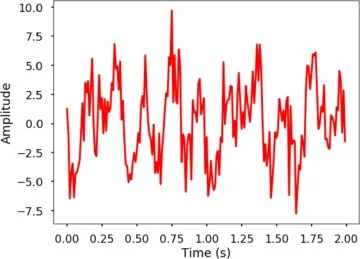
Fourier Analysis:
- Type: Decomposing a complex waveform into sinusoidal components.
- Equation: Sum of sinusoidal terms.
- Use: Fourier analysis is used in signal processing and physics to analyze and model periodic phenomena, such as sound waves and electromagnetic signals.
-
Piecewise Regression:
- Type: Combining multiple linear or nonlinear regression models for different segments of data.
- Equation: Multiple regression equations for different data segments.
- Use: Piecewise regression is used when the relationship between variables changes at different data ranges.
GOODNESS OF FIT STATISTICS :
When you fit a curve or a regression model to a set of data points, you often want to determine how well the model fits the observed data. There are several methods to assess the goodness of fit, they are
- the sum of squares due to error
- R square
- Adjusted R square
- root mean squared error
- the sum of squares due to error :
This statistic measures the total deviation of the response values from the fit to the response values. It is also called the summed square of residuals and is usually labeled as SSE. A value closer to 0 indicates that the model has a smaller random error component, and that the fit will be more useful for prediction.
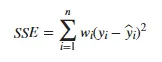
- R square :
This statistic measures how successful the fit is in explaining the variation of the data. Put another way, R-square is the square of the correlation between the response values and the predicted response values. It is also called the square of the multiple correlation coefficient and the coefficient of multiple determination.
R-square is defined as the ratio of the sum of squares of the regression (SSR) and the total sum of squares (SST). SSR is defined as
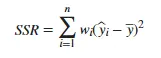
SST is also called the sum of squares about the mean, and is defined as
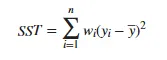
where SST = SSR + SSE. Given these definitions, R-square is expressed as
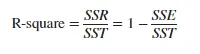
R-square can take on any value between 0 and 1, with a value closer to 1 indicating that a greater proportion of variance is accounted for by the model. For example, an R-square value of 0.8234 means that the fit explains 82.34% of the total variation in the data about the average.
If you increase the number of fitted coefficients in your model, R-square will increase although the fit may not improve in a practical sense. To avoid this situation, you should use the degrees of freedom adjusted R-square statistic described below.
Note that it is possible to get a negative R-square for equations that do not contain a constant term. Because R-square is defined as the proportion of variance explained by the fit, if the fit is actually worse than just fitting a horizontal line then R-square is negative. In this case, R-square cannot be interpreted as the square of a correlation. Such situations indicate that a constant term should be added to the model.
- Adjusted R square
The adjusted R-squared (R^2) is a statistical measure used to evaluate the goodness of fit of a regression model, especially when you have multiple independent variables (predictors) in the model. It's an extension of the regular R-squared but accounts for the number of predictors in the model, which helps you avoid overfitting. The adjusted R-squared is typically used in multiple linear regression analysis.
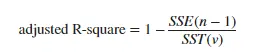
- root mean squared error
This statistic is also known as the fit standard error and the standard error of the regression. It is an estimate of the standard deviation of the random component in the data, and is defined as
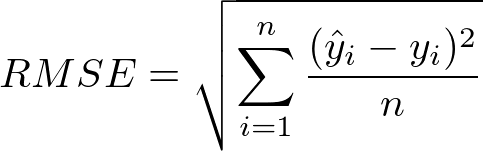
PYTHON PROGRAMMING :
CODE EXPLANATION :
-
import mathimport numpy as npimport matplotlib.pyplot as pltfrom scipy.optimize import curve_fit
these line is used to import necessary library file which are used for the mathematical operations, data manipulation, plottings and curve fittings
-
#linear polynominaldef linear_func(t,a,b):return a*t + b#quadratic polynomialdef quad_func(t,a,b,c):return a * pow(t,2) + b * t + c#cubic polynomialdef cubic_func(t,a,b,c,d):return a * pow(t,3) + b * pow(t,2) + c * t + d#quartic polynomialdef quart_func(t,a,b,c,d,e):return a * pow(t,4) + b * pow(t,3) + c * pow(t,2) + d * t + e
The code defines four polynomial functions representing linear, quadratic, cubic, and quartic polynomial models, respectively. These functions take independent variable t and polynomial coefficients a, b, c, d d and e as input and return the predicted values.
this function will acts as a predefined formula when calling the function, it helps to calculate the values inside it and gives us a desired output.
linear function, y = ax + b
quadratic function, y = ax^2 + bx + c
cubic function, y = ax^3 + bx^2 + cx + d
quartic function, y = ax^4 + bx^3 + cx^2 +dx + c
-
def read_files():temperature = []cp = []for line in open('data','r'):values = line.split(',')temperature.append(float(values[0]))cp.append(float(values[1]))return(temperature,cp)
The read file function is defined to read data from a file named 'data'. It reads temperature and specific heat capacity values from the file and returns them as lists.
in this the temperature and cp is created as an empty array, when the for loop is executed to iterate each line throught out the 'data' file.
for line in open('data','r'): opens the 'data' file in read ('r') mode and iterates through its lines, one line at a time.
Inside the loop, each line from the file is split into values using the split(',') method. The split(',') method splits the line into a list of values wherever a comma (',') is encountered
The first value (at index 0) is assumed to be the temperature, and the second value (at index 1) is assumed to be the specific heat capacity.
The float function is used to convert the string representations of the temperature and specific heat capacity values into floating-point numbers. This ensures that the data is stored as numeric values in the lists.
The temperature and cp values extracted from each line are appended to their respective lists using the append() method. This adds each temperature and specific heat capacity value to the end of their respective lists.
After all the lines in the 'data' file have been processed, the function returns a tuple containing the temperature and cp lists as its elements. This allows the calling code to access and use the parsed data.
-
def errors (cp,cp_fit):SSR = sum((np.array(cp_fit) - np.mean(cp))**2)SSE = sum((np.array(cp) - np.array(cp_fit))**2)SST = SSR + SSER2 = SSR / SSTRMSE = math.sqrt(SSE/len(cp))return(R2,RMSE)
The error() function calculates two important metrics: the coefficient of determination (R⊃2;) and the root mean square error (RMSE). It takes two lists, cp (actual data) and cp_fit (fitted data), as input.
It calculates the sum of squared residuals (SSR), sum of squared errors (SSE), and the total sum of squares (SST).
R⊃2; is calculated as SSR divided by SST.
RMSE is calculated as the square root of SSE divided by the number of data points.
The function returns R⊃2; and RMSE as a tuple.
-
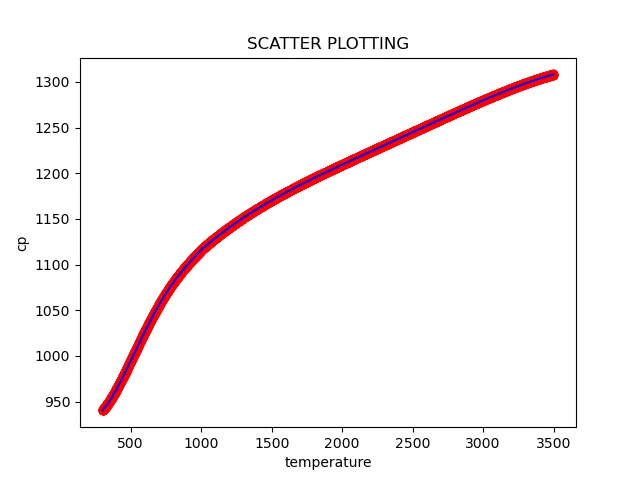
temperature,cp = read_files()plt.plot(temperature,cp,color="blue")plt.scatter(temperature,cp,color="red")plt.xlabel('temperature')plt.ylabel('cp')plt.title('SCATTER PLOTTING')plt.savefig('SCATTER PLOTTING')plt.show()
A scatter plot is used in the provided code to visually examine and understand the relationship between temperature and specific heat capacity. It helps assess data distribution, identify patterns, and decide on an appropriate model before fitting polynomial models or other types of regression models. Additionally, it aids in outlier detection and model validation by comparing the fitted curve to the actual data.
-
popt,pcov = curve_fit(linear_func, temperature,cp)
curve fit is a function from the scipy.optimize library used for curve fitting, specifically for fitting data to user-defined functions.
The curve fit function takes three main arguments:
- The first argument, linear function, is the user-defined function that represents the model to which you want to fit your data. In this case, linear function is the function that defines a linear polynomial model with two parameters, a and b, representing the slope and intercept of the line.
- The second argument, temperature, is the independent variable (x-values) from your dataset.
- The third argument, cp, is the dependent variable (y-values) from your dataset.
When you run curve fit, it attempts to fit the data in cp to the linear function model by adjusting the parameters a and b to minimize the difference between the model's predictions and the actual cp values.
The function returns two values:
popt: This is a NumPy array containing the optimized values of the model parameters (a and b in this case) that best fit the data.
pcov: This is a 2D array representing the estimated covariance of the optimized parameters. It provides information about the uncertainty in the parameter estimates.
- fit_linear_cp =linear_func(np.array(temperature),*popt)
Here, the optimized parameter values popt (obtained from the previous curve fit call) are used to generate fitted or predicted cp values using the linear function model.
np. array converts the list of temperature values into a NumPy array, which is suitable for mathematical operations.
*popt uses the optimized parameter values as separate arguments. In this case, it unpacks the values of a and b from the popt array and passes them as arguments to linear function
The result is fit_linear_cp, which is a list or array of predicted cp values obtained from the fitted linear model using the optimized parameters.
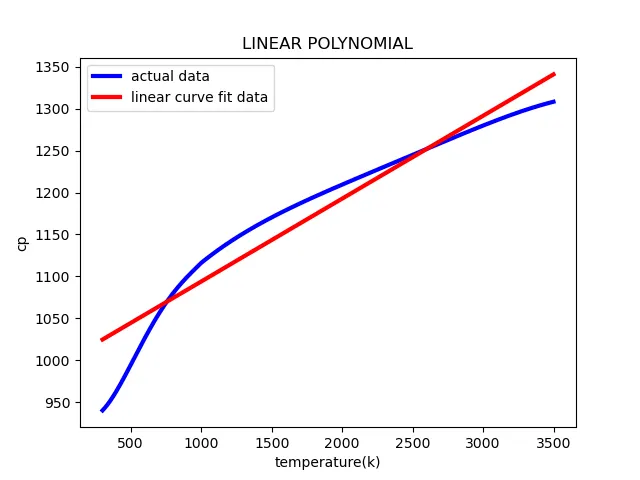
A plot is created to visualize the linear polynomial fit along with the actual data points.
similar Steps for Quadratic, Cubic, and Quartic Polynomial Fits
-
linear_R2,linear_RMSE = errors(cp,fit_linear_cp)print('goodness of linear fit =',linear_R2)print('RMSE of linear fit =', linear_RMSE)
For each polynomial fit (linear, quadratic, cubic, and quartic), the code calculates and prints the goodness of fit (R⊃2;) and RMSE to assess how well the model fits the data.
GRAPHICAL OUTPUT :
- scatter plottings
- linear curve fit
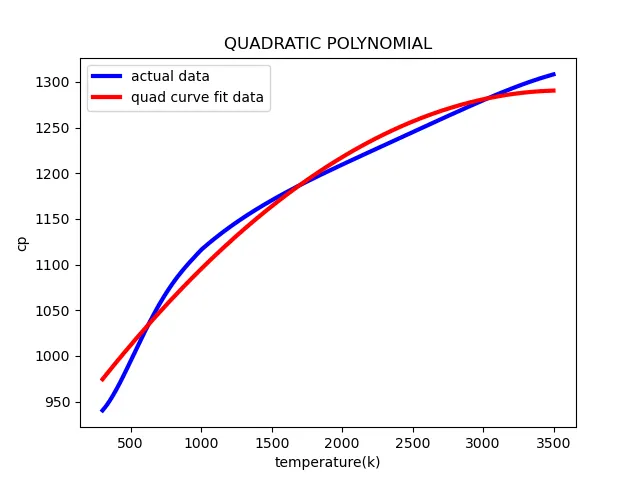
- quadratic polynomial curve fit
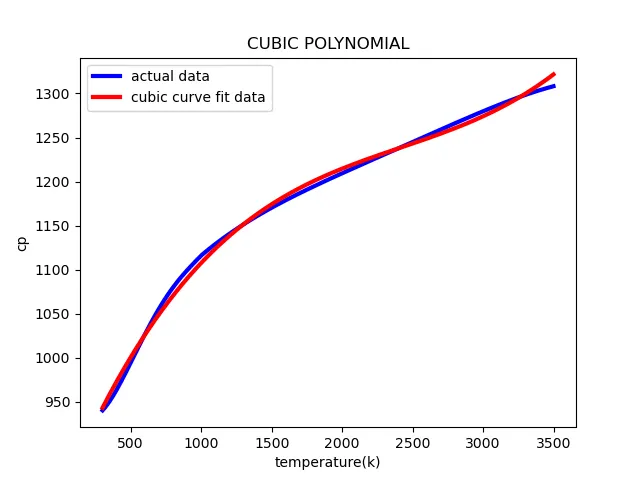
- cubic polynomial curve fit
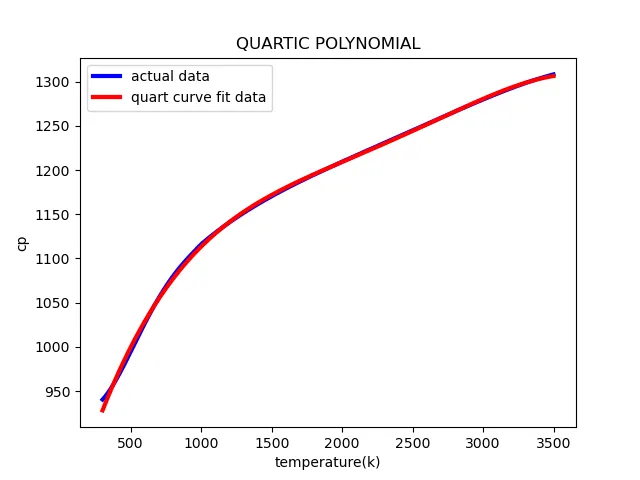
- quartic polynomial curve fit
GOODNESS AND RMSE OF CURVE FITTINGS :
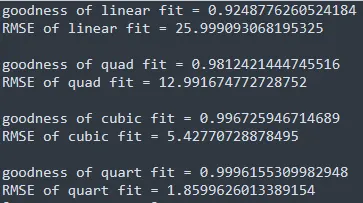
as the above study, the higher order polynomial curve fitting gives the more accurate results which helps to predicit the data . in this four order polynomial is giving more accurate value of 99.96% of goodness curve fit and least of RMSE value as 1.85
CONCLUSION :
Thus a code to perform curve fit for the given cp and temperature data is performed and the result has been concluded to go for higher order polynomial for this set of engineering data points.