Data Analysis using Python to Evaluate Engine's Performance
AIM: USING DATA ANALYSIS TECHNIQUES, PERFORM VALIDITY AND COMPATIBILITY CHECK FOR AN ENGINE DATA FILE, VISUALIZE THE DATA USING PLOTTING COMMANDS AND EVALUATE SOME BASIC PERFORMANCE DETAILS USING PYTHON.
OBJECTIVE:
1. DATA VISUALIZER
Script should take column numbers as the input and plot the respective columns as separate images.
I) Each file should be saved by the name of the column.
II) The plot labels should be extracted from the file. If, I request for a plot between column 1 (crank angle) and column 8(volume), then the label information should automatically be extracted and must appear as labels in the plots.
2. COMPATABILITY CHECK
I) You code should exit gracefully, if a non-compatible file is provided as an input. It should say something like "File not recognized. Please provide a valid CONVERGE output file"
3. BASIC PERFORMANCE CALCULATION
I) Calculate the area under the P-V diagram. P is in column 2 and V is in column 8.
II) Calculate the power output of this engine. Assume that RPM is 1500.
III) This engine consumed 20 micro grams of fuel (per 1 stroke cycle). Calculate its specific fuel consumption.
THEORY:
Data analysis is the practice of working with data to glean useful information, which can then be used to make informed decisions. The information derived can be useful in several different ways, such as for building a business strategy or ensuring the safety and efficiency of an engineering project. It is the process of systematically applying statistical and/or logical techniques to describe and illustrate, condense and recap, and evaluate data.
Data Analysis is widely used in automobiles nowadays to find suitable points where optimization is possible to enhance the overall performance and safety aspects of the engine. It can be used to regulate the consumption of fuel in the most effective manner.
We have to read the data from a given file named 'engine_data.out' using Python which will enable us to plot a curve between multiple engine parameters & also allow us to perform basic performance calculations such as calculating the Area under the Curve for a PV diagram, Power-Output of the engine while assuming the RPM(Revolutions Per Minute) is 1500. Also, an evaluation of the Specific Fuel Consumption(SFC) is needed when the engine consumes 20 micrograms of fuel per cycle.
PYTHON PROGRAM TO ACHIEVE THE ABOVE-MENTIONED OBJECTIVES:
# Performing Data Analysis to evaluate data being extracted from a 4-Stroke Engine using Python
# By Sagar Biswas

# Importing all the necessary modules
import numpy as np
import matplotlib.pyplot as plt
from scipy.integrate import simps

fname = input("Please provide the exact name of the file received from CONVERGE having extension(.out):")


# Validity_Check:
# It is done to ensure that the data is extracted from a valid CONVERGE file with an extension of '(.out)'
# Using 'Try & Except Method' we can set a conditional criterion to open or not open the file based on its validity

try:
    x = open(fname)  # 'open' command is used to open the file if it is present in the folder
    print('Validity-Check-> PASS!')
except FileNotFoundError:  # 'FileNotFoundError' is shown when a file or directory is requested but doesn't exist.'
    print('Validity-Check-> FAIL!, Invalid filename, Please try again')  # This statement is shown when the file is not found.
    exit()  # 'exit' command is used to jump out of further execution

# Compatibility Check:
# It is done to check whether the file is obtained from the CONVERGE package as an output file or not
lst = list()  # Creating an empty list to store the values of respective arrays for each line starting with an '#'.
for word in open(fname):
    if '#' in word:  # Checking to see if the line begins with '#'
        lst.append(word.split())  # If the line begins with '#', elements of that line is separated from each other
        # and are stored wihtin the list named as 'lst'

com_test = list()  # Creating an Empty-list to Store the Elements of the First-Array in the list named as 'lst'

for cov in lst[0]: # Using for loop to go through every element inside the first array in the list 'lst'
    com_test.append(cov)  # Storing all the elements of the first array inside a new list named as 'com_test'
if com_test[1] == 'CONVERGE':
    # Checking to see if the 2nd word in the list is 'CONVERGE'
    # It'll ensure that the respective file is an output file generated from a CONVERGE Package.

    print('Compatibility-Test-> PASS!')  # If the condition satisfied
else:
    print('Compatibility-Test-> FAIL!')  # if the condition does not satisfied


# Extracting & Converting the Elements of the Arrays to create more pragmatic variables storing only the required values
i = 0
for line in open(fname):
    if i == 2:
        p = line.split()  # Saving all the respective 'Units' inside a list named as 'p'
        i = 0

    if i == 1:
        q = line.split()  # Saving all the respective 'Parameters' inside a list named as 'p'
        i = i + 1

    if 'column' in line.split():
        r = line.split()  # The Column-Order for all the respective Parameters and their Units are added to the list 'r'
        i = 1 # For this line, the value of 'i' is stated as 1 and therefore once the value of 'i' in increased, the program jumps to the next line.

r.remove("column")  # Removing the word 'column' from the list 'r' to create a list consisting only the respective column number
p.remove("#")  # Removing the symbol '#' from list 'p' as it is of no use right now
q.remove("#")  # Removing the symbol '#' from list 'q' as it is of no use right now
r.remove("#")  # Removing the symbol '#' from list 'r' as it is of no use right now based on the above condition for list 'r'
r = np.array(r, dtype=np.int)  # Converting all the Column-Numbers into Integers
total_columns = len(r)  # Total No. of Columns

# Devising Strategy to Organize the Numerical Data
count_data = 0  # Introducing a Counter-Variable to Count the Total No. of Data-Points
data = np.arange(0, total_columns)  # Creating a range for the data where the values are generated within the half-open interval

for line in open(fname):
    if '#' not in line:  # Split the lines that does not begin with '#'
        dc = line.split()  # Storing the Results after Split-Operation into a Variable named as 'dc'
        dc = np.array(dc, dtype=np.float64)  # Using NumPy, Adding all the stored values in 'dc' to an Float32Array
        data = np.vstack([data, dc])  # Float32Array named as 'dc' is being stacked inside a Data-Matrix
        count_data = count_data + 1

data = np.delete(data, 0, 0)  # To Initialize the Array, First-Row is being deleted

# Python Script for Data-Visualization
print('List of all parameters to choose from to plot for Multiple Parameters:->')

# We have to provide the list of all the parameter with their respective column number
for i in r:  # 'r' consists of all the column numbers and 'i' is the iteration variable that will go through each of them
    print('{} for {}'.format(i, q[i - 1]))  # 'q' consists of all the names of the parameters present in the dataset

print(' ')

# Plotting for Two-Parameters at Once
x = input("Do you want to plot the relation between any Two-Parameters? (y/n): ")

while (x.lower() == 'y'):
    column_one = input("Insert the Column-Number of the Parameter tp plot along X-Axis---> (Please refer to the list of paraneters above):")
    column_two = input("Insert the Column-Number of the Parameter to plot along Y-Axis---> (Please refer to the list of paraneters above):")
    column_one = int(column_one)  # Values are then converted into integer format for both columns
    column_two = int(column_two)
    plt.figure()
    plt.plot(data[:, column_one - 1], data[:, column_two - 2])
    plt.xlabel('{} {}'.format(q[column_one - 1], r[column_one - 1]))
    plt.ylabel('{} {}'.format(q[column_two - 1], r[column_two - 1]))
    plt.title('{} {} vs {} {}'.format(q[column_two - 1], r[column_two - 1], q[column_one - 1], q[column_one - 1]))
    z = "n"
    z = input("Save this Plot? (y/n):")
    if (z.lower() == 'y'):
        plt.savefig("{}-{}.png".format(q[column_two - 1], q[column_one - 1]))
    plt.show()
    print(' ')
    x = input("Do you want to plot the relation between any other Two-Parameters? (y/n):")

print(' ')

# Plotting for Single-Parameter
x = input("Do you want a Single-Plot for any one particular parameter? (y/n): ")
while x.lower() == 'y':
    col_num = input("Enter the column number of the variable (Refer input map above): ")
    col_num = int(col_num)
    plt.figure()
    plt.plot(np.arange(0, count_data), data[:, col_num - 1])
    plt.xlabel('Data point number')
    plt.ylabel('{} {} '.format(q[col_num - 1], r[col_num - 1]))
    z = "n"
    z = input("Save the Plot? (y/n): ")
    if z.lower() == 'y':
        plt.savefig("{}.png".format(q[col_num - 1]))

    plt.show()
    print(' ')
    x = input("Do you want to plot for any other Single-Parameter?")

print(' ')

# Calculating the Overall Engine Performance

print('Engine Performance')

# Total Work done by the Engine:-
p1 = [i.lower() for i in q]
pressure_column = p1.index('pressure')
volume_column = p1.index('volume')
pressure = data[:, pressure_column]
volume = data[:, volume_column]
A = 0  # Area under the PV Curve
A = simps(pressure, volume, even='first') * np.power(10, 6)  # Work Done Per Cycle(Joules)

# Total Power Output of the Engine:
RPM = int(input("Enter the Engine's RPM: "))  # RPM stands for Revolution Per Minute
F = int(input('Amount of Fuel Consumed Per Cycle (Unit-> Microgram): '))  # Amount of Fuel Consumed Per Cycle in Micrograms
N = RPM / (2 * 60)  # No. of Cycles Per-Second for 4-stroke engine
P = A * N  # Power output(W) at speed N (rad/s)

# SPECIFIC FUEL CONSUMPTION
F = (F * N * 3600) / np.power(10, 9)  # Fuel consumption (Kg/hr)
SFC = (F * 1000) / P  # Specific Fuel Consumption(Kg/hr.KW)

# Final Results for Area Under the Curve, Power Output & Specific Fuel Consumption
print('Area Under the Curve for PV (i.e. the Work Done Per-Cycle) = {} J'.format(A))
print('Power Output at {} RPM = {} W'.format(RPM, P))
print('Specific Fuel Consumption = {} Kg/KW.hr'.format(SFC))
The python program is thoroughly explained inside the code itself using comments.
EXPLANATION FOR THE PYTHON CODE:
1. Firstly, all the necessary modules that are required to run the program are imported.
2. We performed a "Validity Check" to ensure that the file with the correct filename should be opened by python. If the filename is incorrect than python will show a 'FileNotFoundError' Error.
3. Next, we performed a "Compatibility Check" to ensure that the file belongs to 'CONVERGE' which is a CFD Package that is providing us the thermodynamic datasheet to perform data analysis on. If the file does not contain any mention of 'CONVERGE' than Compatibility Check fails and program is exited.
4. Each column is identified using its column name and number. Lines that starts with '#' are seperated from the rest of the dataset and all the elements in each line is split individually to store them systematically inside variables.
5. All the values in lines that doesn't starts with '#' is split individually and the values are stored inside a variable.
6. A list of options is created for the user to choose which parameters they want to plot the relationship between and if someone wants to print the plot for a single variable, they can do that by moving forward from the multivariable plotting to single variable plotting.
7. Plotting commands are carefully designed to provide accurate labels and graphical results.
8. To Evaluate the Engine's Performance, the formula of Work-done, Power Output of the Engine, Area under the PV Curve and finally Specific Fuel Consumption rate is used and necessary codes are formulated.
RESULTS & OBSERVATIONS:
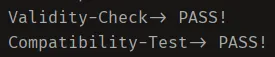
Firstly, the Validity & Compatibility must allow the data file to pass through to perform the analysis.
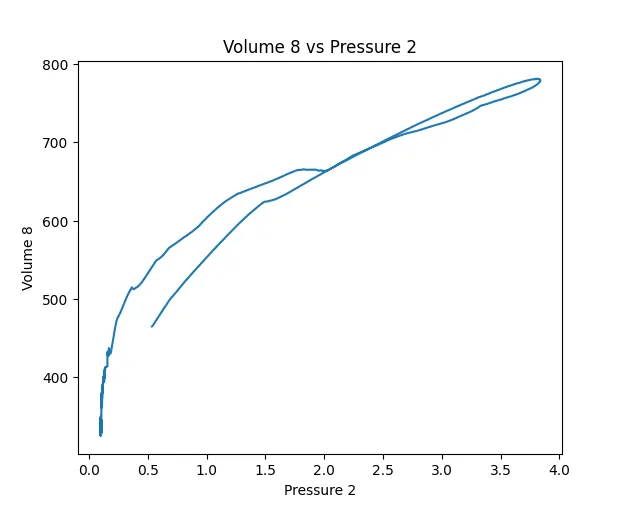
Results after plotting the results between 2nd Column (Pressure) and 8th Column (Volume):
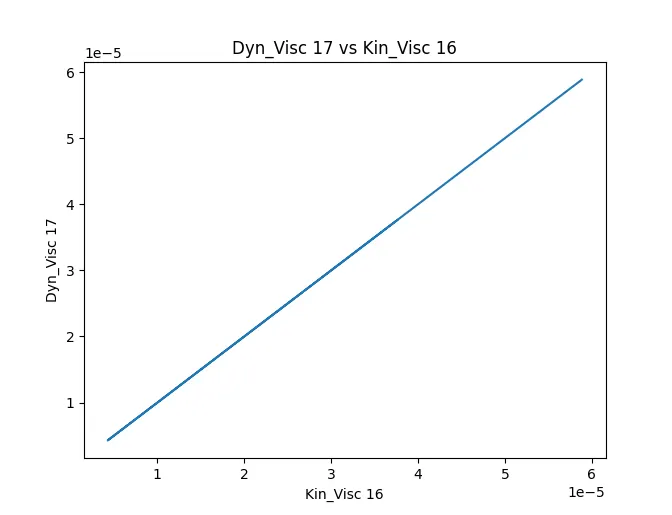
Results after plotting the results between 16th Column (Kinematic Viscosity) and 17th Column (Dynamic Viscosity):
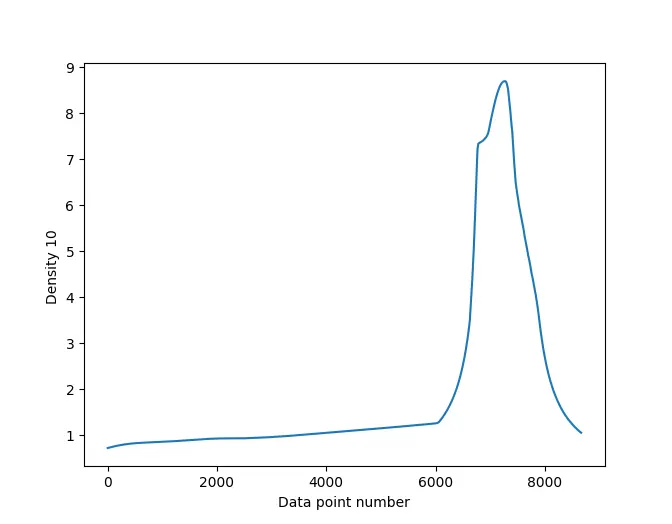
Results after plotting the results for Single-Parameter in Column 10 (Density):-
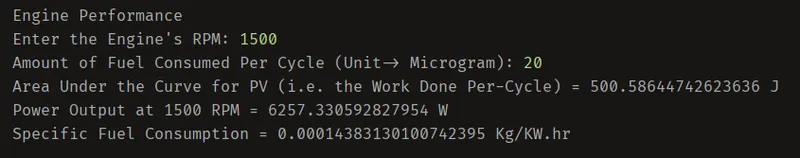
ENGINE PERFORMANCE RESULTS:
R.P.M =1500
Fuel Consumed Per Cycle in Micrograms = 20