K-Means Clustering implementation
Objective: In this project we are going to implement an unsupervised machine learning algorithm called 'K-Means Clustering' to a 'Car Dataset'.
Overview:
- Explanation of 'Similarity calculation on Categorical data'.
- Explanation about K-Means Clustering technique.
- Explaining Pros and Cons of K-Means Clustering algorithm.
- Implementing the K-Means Clustering algorithm on 'Car Dataset'.
- Summarizing and Concluding remarks.
Similarity calculation on Categorical Data:
Measuring similarity or distance between two data points is a core requirement for several data mining and knowledge discovery tasks that involve distance computation. Examples include clustering (k- means), distance-based outlier detection, classification (knn, SVM), and several other data mining tasks.
These algorithms typically treat the similarity computation as an orthogonal step and can make use of any measure. For continuous data sets, the Minkowski Distance is a general method used to compute the distance between two multivariate points.
In particular, the Minkowski Distance of order 1 (Manhattan) and order 2 (Euclidean) are the two most widely used distance measures for continuous data. The key observation about the above measures is that they are independent of the underlying data set to which the two points belong. Several data-driven measures, such as Mahalanobis Distance, have also been explored for continuous data.
The notion of similarity or distance for categorical data is not as straightforward as for continuous data. The key characteristic of categorical data is that the different values that a categorical attribute takes are not inherently ordered. Thus, it is not possible to directly compare two different categorical values. The simplest way to and similarity between two categorical attributes is to assign a similarity of 1 if the values are identical and a similarity of 0 if the values are not identical. For two multivariate categorical data points, the similarity between them will be directly proportional to the number of attributes in which they match.
Distance metrics are a key part of several machine learning algorithms. These distance metrics are used in both supervised and unsupervised learning, generally to calculate the similarity between data points.
An effective distance metric improves the performance of our machine learning model, whether that’s for classification tasks or clustering.
Let’s say we want to create clusters using the K-Means Clustering or k-Nearest Neighbour algorithm to solve a classification or regression problem. How will you define the similarity between different observations here? How can we say that the two points are similar to each other?
This will happen if their features are similar.
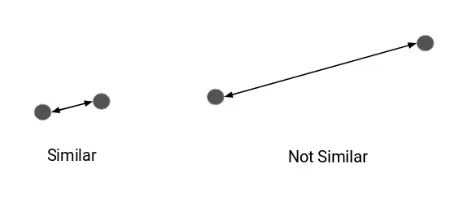
Hence, we can calculate the distance between points and then define the similarity between them.
There are 4 types of methods which is used to calculate the distance or similarities between two points.
- Euclidean Distance
- Manhattan Distance
- Minkowski Distance
- Hamming Distance
1. Euclidean Distance:
Euclidean Distance represents the shortest distance between two points.
Most machine learning algorithms including K-Means use this distance metric to measure the similarity between observations. Let’s say we have two points as shown below:
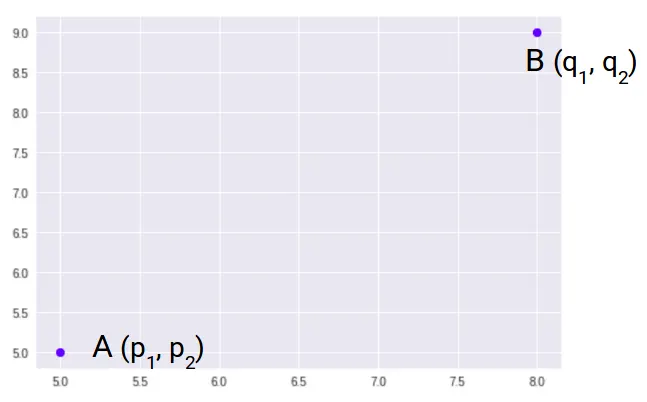
So, the Euclidean Distance between these two points A and B will be:
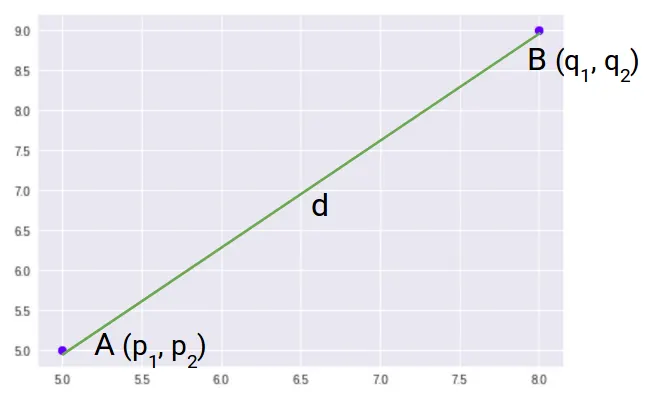
Here’s the formula for Euclidean Distance:
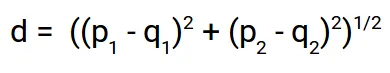
We use this formula when we are dealing with 2 dimensions. We can generalize this for an n-dimensional space as:
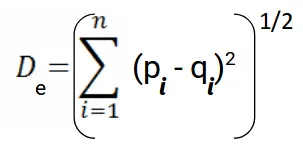
Where,
- n = number of dimensions
- pi, qi = data points
2. Manhattan Disance:
Manhattan Distance is the sum of absolute differences between points across all the dimensions.
We can represent Manhattan Distance as:
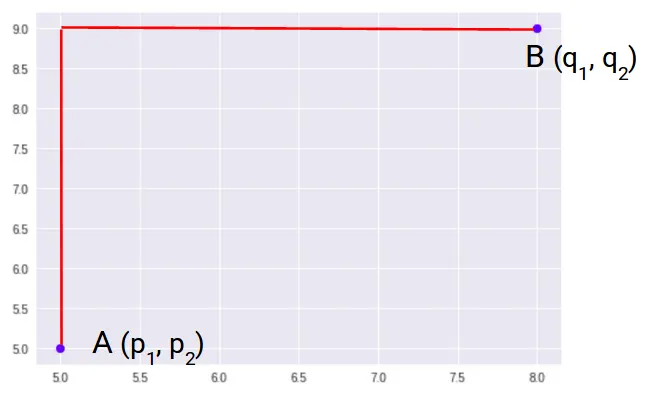
Since the above representation is 2 dimensional, to calculate Manhattan Distance, we will take the sum of absolute distances in both the x and y directions. So, the Manhattan distance in a 2-dimensional space is given as:
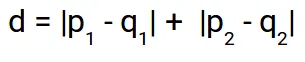
And the generalized formula for an n-dimensional space is given as:
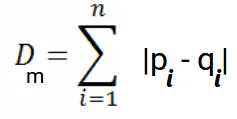
Where,
- n = number of dimensions
- pi, qi = data points
3. Minkowski Distance:
Minkowski Distance is the generalized form of Euclidean and Manhattan Distance.
The formula for Minkowski Distance is given as:
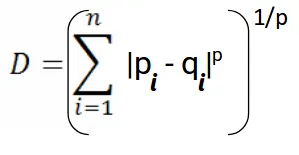
Here, p represents the order of the norm.
When the order is 1, both Minkowski and Manhattan Distance are the same.
When the order is 2, Minkowski and Euclidean distances are the same.
4. Hamming Distance:
Hamming Distance measures the similarity between two strings of the same length. The Hamming Distance between two strings of the same length is the number of positions at which the corresponding characters are different.
Let’s understand the concept using an example. Let’s say we have two strings:
“euclidean” and “manhattan”
Since the length of these strings is equal, we can calculate the Hamming Distance. We will go character by character and match the strings. The first character of both the strings (e and m respectively) is different. Similarly, the second character of both the strings (u and a) is different. and so on.
Look carefully – seven characters are different whereas two characters (the last two characters) are similar:
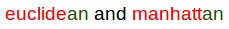
Hence, the Hamming Distance here will be 7. Note that larger the Hamming Distance between two strings, more dissimilar will be those strings (and vice versa).
K-Means Clustering:
K-Means Clustering is an Unsupervised Learning algorithm, which groups the unlabeled dataset into different clusters. Here K defines the number of pre-defined clusters that need to be created in the process, as if K=2, there will be two clusters, and for K=3, there will be three clusters, and so on.
It is an iterative algorithm that divides the unlabeled dataset into k different clusters in such a way that each dataset belongs only one group that has similar properties.
It allows us to cluster the data into different groups and a convenient way to discover the categories of groups in the unlabeled dataset on its own without the need for any training.
It is a centroid-based algorithm, where each cluster is associated with a centroid. The main aim of this algorithm is to minimize the sum of distances between the data point and their corresponding clusters.
The algorithm takes the unlabeled dataset as input, divides the dataset into k-number of clusters, and repeats the process until it does not find the best clusters. The value of k should be predetermined in this algorithm.
The k-means clustering algorithm mainly performs two tasks:
- Determines the best value for K center points or centroids by an iterative process.
- Assigns each data point to its closest k-center. Those data points which are near to the particular k-center, create a cluster.
Hence each cluster has datapoints with some commonalities, and it is away from other clusters.
The below diagram explains the working of the K-means Clustering Algorithm:
The working of the K-Means algorithm is explained in the below steps:
Step-1: Select the number K to decide the number of clusters.
Step-2: Select random K points or centroids. (It can be other from the input dataset).
Step-3: Assign each data point to their closest centroid, which will form the predefined K clusters.
Step-4: Calculate the variance and place a new centroid of each cluster.
Step-5: Repeat the third steps, which means reassign each datapoint to the new closest centroid of each cluster.
Step-6: If any reassignment occurs, then go to step-4 else go to FINISH.
Step-7: The model is ready.
Let's understand the above steps by considering the visual plots:
Suppose we have two variables M1 and M2. The x-y axis scatter plot of these two variables is given below:
- Let's take number k of clusters, i.e., K=2, to identify the dataset and to put them into different clusters. It means here we will try to group these datasets into two different clusters.
- We need to choose some random k points or centroid to form the cluster. These points can be either the points from the dataset or any other point. So, here we are selecting the below two points as k points, which are not the part of our dataset. Consider the below image:
- Now we will assign each data point of the scatter plot to its closest K-point or centroid. We will compute it by applying some mathematics that we have studied to calculate the distance between two points. So, we will draw a median between both the centroids. Consider the below image:
From the above image, it is clear that points left side of the line is near to the K1 or blue centroid, and points to the right of the line are close to the yellow centroid. Let's color them as blue and yellow for clear visualization.
- As we need to find the closest cluster, so we will repeat the process by choosing a new centroid. To choose the new centroids, we will compute the center of gravity of these centroids, and will find new centroids as below:
- Next, we will reassign each datapoint to the new centroid. For this, we will repeat the same process of finding a median line. The median will be like below image:
From the above image, we can see, one yellow point is on the left side of the line, and two blue points are right to the line. So, these three points will be assigned to new centroids.
As reassignment has taken place, so we will again go to the step-4, which is finding new centroids or K-points.
- We will repeat the process by finding the center of gravity of centroids, so the new centroids will be as shown in the below image:
- As we got the new centroids so again will draw the median line and reassign the data points. So, the image will be:
- We can see in the above image; there are no dissimilar data points on either side of the line, which means our model is formed. Consider the below image:
As our model is ready, so we can now remove the assumed centroids, and the two final clusters will be as shown in the below image:
How to choose the value of 'K number of Clusters' in K-Means clustering algorithm?
The performance of the K-means clustering algorithm depends upon highly efficient clusters that it forms. But choosing the optimal number of clusters is a big task. There are some different ways to find the optimal number of clusters, but here we are discussing the most appropriate method to find the number of clusters or value of K. The method is given below:
Elbow Method:
The Elbow method is one of the most popular ways to find the optimal number of clusters. This method uses the concept of WCSS value. WCSS stands for Within Cluster Sum of Squares, which defines the total variations within a cluster. The formula to calculate the value of WCSS (for 3 clusters) is given below:
`WCSS = sum_(P_(itext( in cluster 1))) text(distance) (P_iC_1)^2 + sum_(P_(itext( in cluster 2))) text(distance) (P_iC_2)^2+sum_(P_(itext( in cluster 3))) text(distance) (P_iC_3)^2`
In the above formula of WCSS,
∑Pi in Cluster1 distance(Pi C1)2: It is the sum of the square of the distances between each data point and its centroid within a cluster1 and the same for the other two terms.
To measure the distance between data points and centroid, we can use any method such as Euclidean distance or Manhattan distance.
To find the optimal value of clusters, the elbow method follows the below steps:
- It executes the K-means clustering on a given dataset for different K values (ranges from 1-10).
- For each value of K, calculates the WCSS value.
- Plots a curve between calculated WCSS values and the number of clusters K.
- The sharp point of bend or a point of the plot looks like an arm, then that point is considered as the best value of K.
Since the graph shows the sharp bend, which looks like an elbow, hence it is known as the elbow method. The graph for the elbow method looks like the below image:
Pros and Cons of K-Means Clustering:
Pros:
1. Simple: It is easy to implement k-means and identify unknown groups of data from complex data sets. The results are presented in an easy and simple manner.
2. Flexible: K-means algorithm can easily adjust to the changes. If there are any problems, adjusting the cluster segment will allow changes to easily occur on the algorithm.
3. Suitable in a large dataset: K-means is suitable for a large number of datasets and it’s computed much faster than the smaller dataset. It can also produce higher clusters.
4. Efficient: The algorithm used is good at segmenting the large data set. Its efficiency depends on the shape of the clusters. K-means work well in hyper-spherical clusters.
5. Time complexity: K-means segmentation is linear in the number of data objects thus increasing execution time. It doesn’t take more time in classifying similar characteristics in data like hierarchical algorithms.
6. Tight clusters: Compared to hierarchical algorithms, k-means produce tighter clusters especially with globular clusters.
7. Easy to interpret: The results are easy to interpret. It generates cluster descriptions in a form minimized to ease understanding of the data.
8. Computation cost: Compared to using other clustering methods, a k-means clustering technique is fast and efficient in terms of its computational cost O(K*n*d).
9. Accuracy: K-means analysis improves clustering accuracy and ensures information about a particular problem domain is available. Modification of the k-means algorithm based on this information improves the accuracy of the clusters.
10. Spherical clusters: This mode of clustering works great when dealing with spherical clusters. It operates with an assumption of joint distributions of features since each cluster is spherical. All the clusters features or characters have equal variance and each is independent of each other.
Cons:
1. No-optimal set of clusters: K-means doesn’t allow development of an optimal set of clusters and for effective results, you should decide on the clusters before.
2. Lacks consistency: K-means clustering gives varying results on different runs of an algorithm. A random choice of cluster patterns yields different clustering results resulting in inconsistency.
3. Uniform effect: It produces cluster with uniform size even when the input data has different sizes.
4. Order of values: The way in which data is ordered in building the algorithm affects the final results of the data set.
5. Sensitivity to scale: Changing or rescaling the dataset either through normalization or standardization will completely change the final results.
6. Crash computer: When dealing with a large dataset, conducting a dendrogram technique will crash the computer due to a lot of computational load and Ram limits.
7. Handle numerical data: K-means algorithm can be performed in numerical data only.
8. Operates in assumption: K-means clustering technique assumes that we deal with spherical clusters and each cluster has equal numbers for observations. The spherical assumptions have to be satisfied. The algorithm can’t work with clusters of unusual size.
9. Specify K-values: For K-means clustering to be effective, you have to specify the number of clusters (K) at the beginning of the algorithm.
10. Prediction issues: It is difficult to predict the k-values or the number of clusters. It is also difficult to compare the quality of the produced clusters.
Implementing the K-Means Clustering Algorithm for 'Car Dataset':
About the Dataset:
Dataset is about cars from back in 85.
This data set consists of three types of entities:
(a) the specification of an auto in terms of various characteristics,
(b) its assigned insurance risk rating,
(c) its normalized losses in use as compared to other cars. The second rating corresponds to the degree to which the auto is more risky than its price indicates. Cars are initially assigned a risk factor symbol associated with its price. Then, if it is more risky (or less), this symbol is adjusted by moving it up (or down) the scale. Actuarians call this process "symboling". A value of +3 indicates that the auto is risky, -3 that it is probably pretty safe. The third factor is the relative average loss payment per insured vehicle year. This value is normalized for all autos within a particular size classification (two-door small, station wagons, sports/specialty, etc…), and represents the average loss per car per year.
Note: Several of the attributes in the database could be used as a "class" attribute.
Number of Instances: 205
Number of Attributes: 29 total
-- 18 continuous
-- 1 integer
-- 10 nominal.
The steps we are going to follow in this case are:'
- Data pre-processing.
- Finding the optimum value of K usng Elbow method.
- Training the K-means algorithm on the training dataset and Visualising the clusters.
1. Data pre-processing:
The first step will be data pre-processing. In this step we will prepare out dataset for the algorithm to implement. To do that we will follow the following steps.
- Importing the necessary libraries.
import pandas as pd
import numpy as np
import matplotlib.pyplot as plt
import seaborn as sns
from sklearn.cluster import KMeans
In the above code, the numpy we have imported for the performing mathematics calculation, matplotlib & seaborn is for plotting the graph, and pandas are for managing the dataset. KMeans is imported from sklearn library to perform the algorithm.
- Importing the 'Car' dataset.
df = pd.read_csv('auto_clean.csv')
df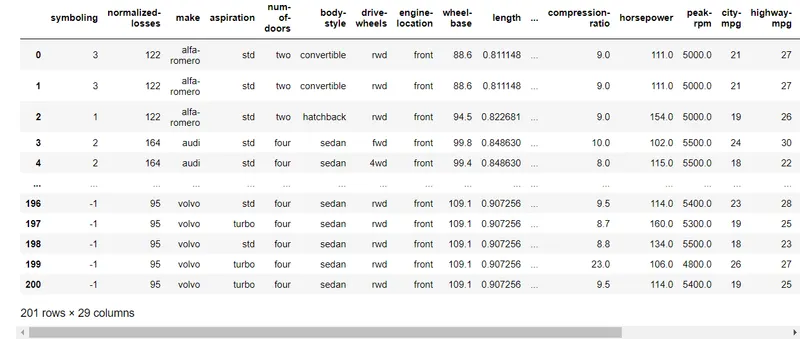
So this dataset contains 201 datapoints and 29 features.
- Getting some information about the data.
df.describe()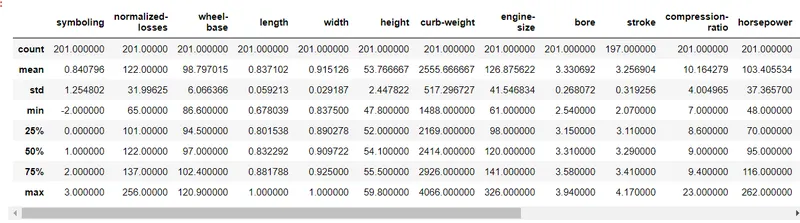
df.info()<class 'pandas.core.frame.DataFrame'>
RangeIndex: 201 entries, 0 to 200
Data columns (total 29 columns):
# Column Non-Null Count Dtype
--- ------ -------------- -----
0 symboling 201 non-null int64
1 normalized-losses 201 non-null int64
2 make 201 non-null object
3 aspiration 201 non-null object
4 num-of-doors 201 non-null object
5 body-style 201 non-null object
6 drive-wheels 201 non-null object
7 engine-location 201 non-null object
8 wheel-base 201 non-null float64
9 length 201 non-null float64
10 width 201 non-null float64
11 height 201 non-null float64
12 curb-weight 201 non-null int64
13 engine-type 201 non-null object
14 num-of-cylinders 201 non-null object
15 engine-size 201 non-null int64
16 fuel-system 201 non-null object
17 bore 201 non-null float64
18 stroke 197 non-null float64
19 compression-ratio 201 non-null float64
20 horsepower 201 non-null float64
21 peak-rpm 201 non-null float64
22 city-mpg 201 non-null int64
23 highway-mpg 201 non-null int64
24 price 201 non-null float64
25 city-L/100km 201 non-null float64
26 horsepower-binned 200 non-null object
27 diesel 201 non-null int64
28 gas 201 non-null int64
dtypes: float64(11), int64(8), object(10)
memory usage: 45.7+ KBWe can observe from the above results that there are 29 features in the dataset out of which 8 of them are of int64 type, 10 of them are object type and 11 of them are of float64 type.
- Checking the null values in the features.
df.isna().sum()symboling 0
normalized-losses 0
make 0
aspiration 0
num-of-doors 0
body-style 0
drive-wheels 0
engine-location 0
wheel-base 0
length 0
width 0
height 0
curb-weight 0
engine-type 0
num-of-cylinders 0
engine-size 0
fuel-system 0
bore 0
stroke 4
compression-ratio 0
horsepower 0
peak-rpm 0
city-mpg 0
highway-mpg 0
price 0
city-L/100km 0
horsepower-binned 1
diesel 0
gas 0
dtype: int64So we can observe that there are 4 values missing in the stroke column and 1 value missing in the horsepower-binned column.
- Extracting Independent Features from the dataset.
As this dataset has so many features we cannot perform the K-Means Clustering to every features. So what we will do in this case is first, we will remove all the features that contains non-numerical values and secondly, we will plot a heat map of correlation between the features.
Here will plot the correlation heatmap and will choose the least correlated feautres with the 'price' feature.
The correlation coefficient has values between -1 to 1
— A value closer to 0 implies weaker correlation (exact 0 implying no correlation)
— A value closer to 1 implies stronger positive correlation
— A value closer to -1 implies stronger negative correlation.
df = df.drop(columns = df[['make', 'aspiration', 'num-of-doors','body-style', 'drive-wheels',
            'engine-location','engine-type', 'num-of-cylinders','fuel-system','stroke','horsepower-binned', 'diesel', 'gas']])
df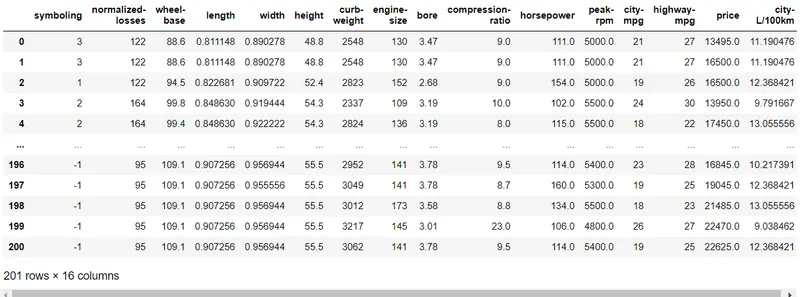
We have also removed the feautres like 'stroke' and 'horsepower-pinned' for simplicity as it containes sum null values.
Now we will plot the heatmap of correlations.
plt.subplots(figsize = ([15,15]))
sns.heatmap(df.corr(),cmap = 'YlGnBu',annot = True)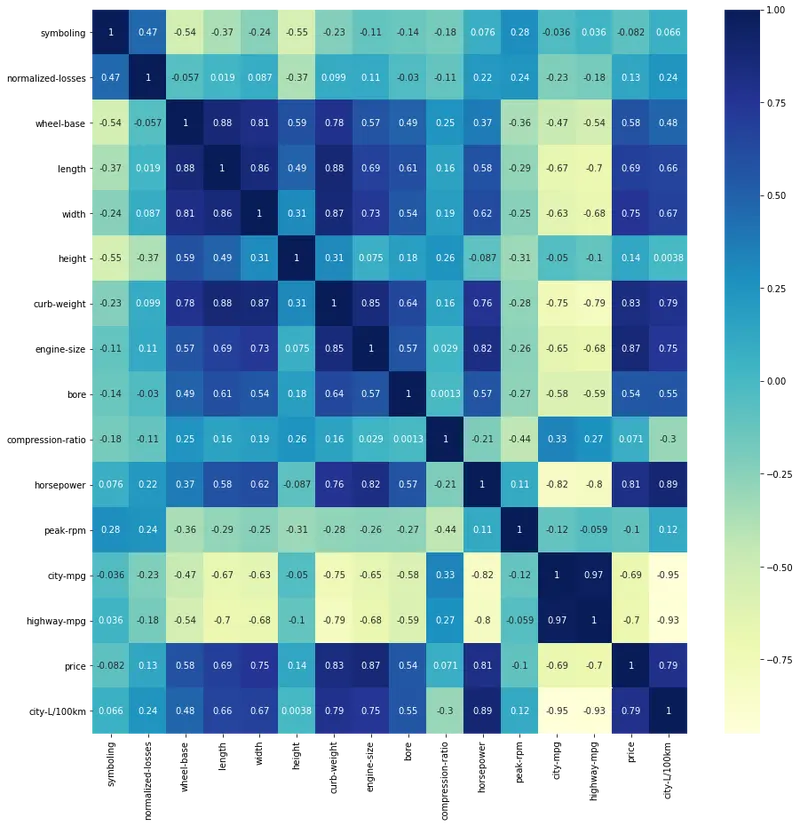
As observing the above heat map, we can see that the closest independency of the features with 'price' are 'compression-ratio' and 'peak-rpm'.
We are not choosing 'symboling' feature as it is already a categorical attribute.
2. Finding the optimum value of K using Elbow Method:
In this process we will be plotting the Elbow plot of 'compression-ratio vs price' and 'peak-rpm vs price'.
- Creating a new dataframe.
We need to create a new dataframe where only these 3 features are going to exist.
final_df = df[['peak-rpm','compression-ratio','price']]
final_df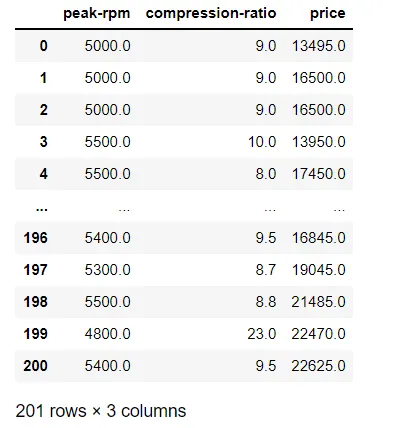
- Scaling down the dataframe.
We need to scale down the new dataframe so that it will become computationaly cheap and also it will create symmetric axes while plotting.
from sklearn.preprocessing import MinMaxScaler
scaler = MinMaxScaler()
scaler.fit(final_df)
scaled_df = pd.DataFrame(scaler.transform(final_df),columns = final_df.columns)
scaled_df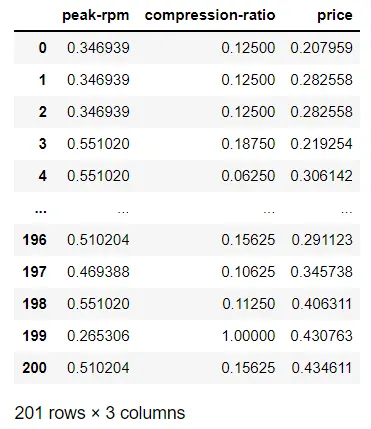
- Elbow plot for 'compression-ratio vs price'.
k_rng = range(1,10)
sse1 = []
for k1 in k_rng:
    km1 = KMeans(n_clusters = k1)
    km1.fit(scaled_df[['price','compression-ratio']])
    sse1.append(km1.inertia_)

plt.xlabel('Price of the Vehicle')
plt.ylabel('Compression ratio of the engine')
plt.plot(k_rng,sse1,marker = 'o')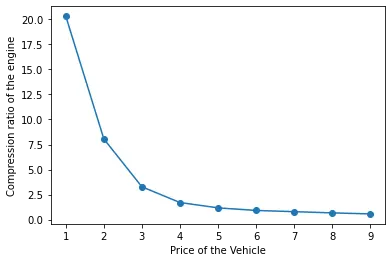
The optimum value of K = 3.
- Elbow plot for 'peak-rpm vs price'.
k_rng = range(1,10)
sse2 = []
for k2 in k_rng:
    km2 = KMeans(n_clusters = k2)
    km2.fit(scaled_df[['price','peak-rpm']])
    sse2.append(km2.inertia_)

plt.xlabel('Price of the Vehicle')
plt.ylabel('Peak RPM of the Vehicle')
plt.plot(k_rng,sse1,marker = 'o')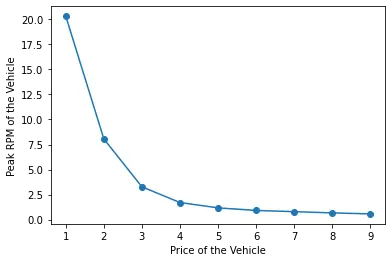
The optimum value of K = 3 in this case also.
3. Implementing K-Means Clustering Algorithm:
In this process we are going to implement the K-Means Clustering algorithm to our scaled dataframe.
- K-Means Clustering between 'price' and 'compression-ratio'.
Now we are going to form 3 clusters between 'price' and 'compression-ratio'(as K = 3).
km1 = KMeans(n_clusters = 3)
y_predict = km1.fit_predict(scaled_df[['price','compression-ratio']])
PC_df = scaled_df[['price','compression-ratio']]
PC_df['Cluster(P vs C)'] = y_predict
PC_df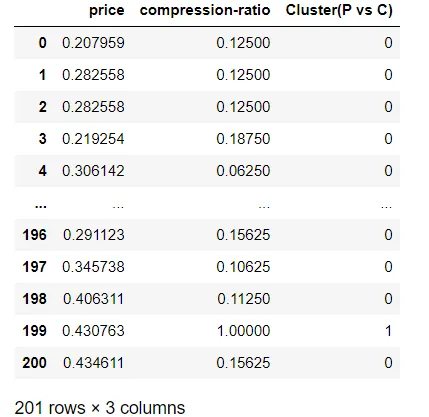
Finding the centroids of the clusters.
km1.cluster_centers_array([[0.14474805, 0.1170256 ],
[0.26612755, 0.9378125 ],
[0.73417242, 0.10458333]])- Visulasing the Clusters between 'price' and 'compression-ratio'.
Drawing the scatter plot for 3 different clusters with their centroids.
PC_df1 = PC_df[PC_df['Cluster(P vs C)'] == 0]
PC_df2 = PC_df[PC_df['Cluster(P vs C)'] == 1]
PC_df3 = PC_df[PC_df['Cluster(P vs C)'] == 2]
plt.subplots(figsize = ([15,10]))
plt.scatter(PC_df1['price'],PC_df1['compression-ratio'],color = 'red')
plt.scatter(PC_df2['price'],PC_df2['compression-ratio'],color = 'green')
plt.scatter(PC_df3['price'],PC_df3['compression-ratio'],color = 'blue')
plt.scatter(km1.cluster_centers_[:,0],km1.cluster_centers_[:,1],marker = '*',s = 200,color = 'purple')
plt.xlabel('Price of the Vehicle')
plt.ylabel('Compression ratio of the Engine')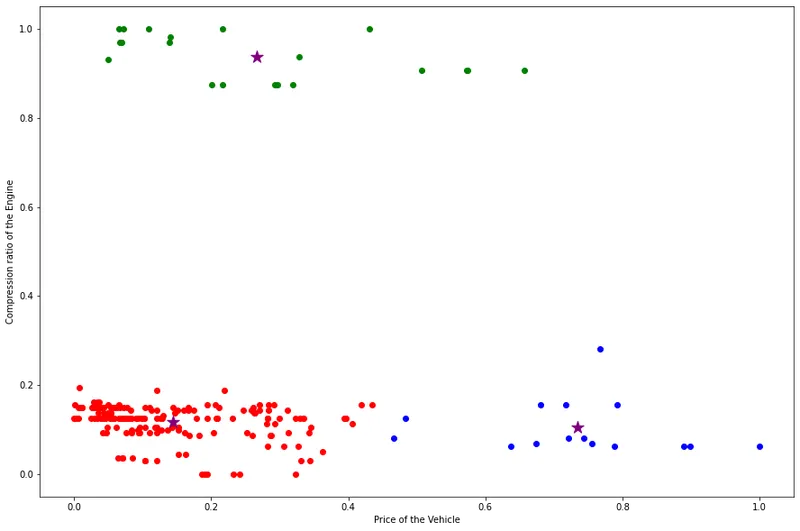
- K-Means Clustering between 'price' and 'peak-rpm'.
Now we are going to form 3 clusters between 'price' and 'peak-rpm'(as K = 3).
km2 = KMeans(n_clusters = 3)
y_predict = km2.fit_predict(scaled_df[['price','peak-rpm']])
PP_df = scaled_df[['price','peak-rpm']]
PP_df['Cluster(P vs P)'] = y_predict
PP_df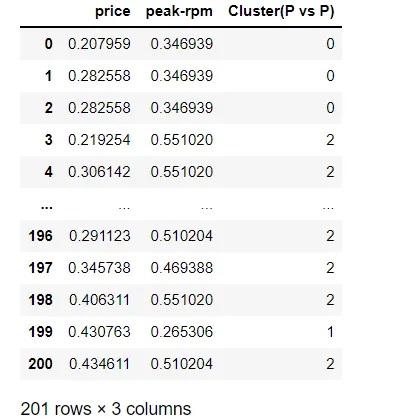
Finding the centroids of the clusters.
km2.cluster_centers_array([[0.13510909, 0.24295432],
[0.69942171, 0.31149302],
[0.16046059, 0.54144414]])- Visualising the Clusters between 'price' and 'compression-ratio'.
Drawing the scatter plot for 3 different clusters with their centroids.
PP_df1 = PP_df[PP_df['Cluster(P vs P)'] == 0]
PP_df2 = PP_df[PP_df['Cluster(P vs P)'] == 1]
PP_df3 = PP_df[PP_df['Cluster(P vs P)'] == 2]
plt.subplots(figsize = ([15,10]))
plt.scatter(PP_df1['price'],PP_df1['peak-rpm'],color = 'red')
plt.scatter(PP_df2['price'],PP_df2['peak-rpm'],color = 'green')
plt.scatter(PP_df3['price'],PP_df3['peak-rpm'],color = 'blue')
plt.scatter(km2.cluster_centers_[:,0],km2.cluster_centers_[:,1],marker = '*',s = 200,color = 'purple')
plt.xlabel('Price of the Vehicle')
plt.ylabel('Peak rated RPM of the Engine')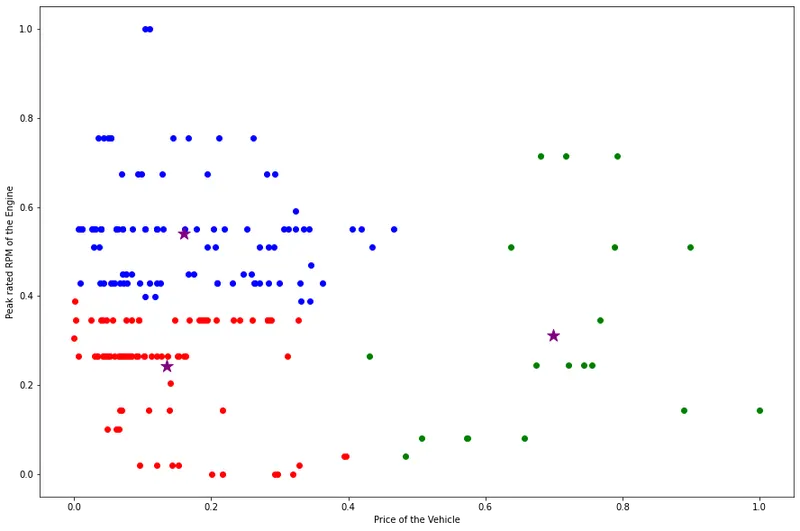
Summary and Conclusion:
- K-Means Clustering algorithm was explained.
- The dataset was trained through K-Means Clustering algorithm.
- The dataset was reduced to only 3 major independent attributes.
- The optimum value of K came out to be 3 in both the cases.
- The centroids of the clusters was calculated.
- The Scatter plot was plotted with 3 different clusters along with their centroids.