Supervised Learning - Prediction Week 3 Challenge
- Perform Gradient Descent in Python with any loss function
Let us consider the below dataset for performing gradient descent:
x = [1,2,3,4,5]
y = [2,4,6,8,10]
The loss function to be used is the mean square error which is defined as:
`MSE = sum_(i=1)^n ( y_a - y_p)^2/n`
n = total number of data points
`y_p` = predicted outcome
`y_a` = actual outcome
- Gradient descent method
Gradient descent is an optimization algorithm. It's based on a convex function and tweaks its parameters iteratively to minimize the loss function to its local minimum
Let us define the y_predicted as:
y_predicted = mx + b
where m,b are constants.
Therefore, we can rewrite MSE as:
`MSE = sum_(i=1)^n ( y_a - (mx+b))^2/n`
To find the local minima, the gradient of MAE wrt to b and m is calculated:
`(delMSE)/(delb) = 2/n.sum_(i=1)^n(-1) ( y_a - (mx+b))^2/n`
`(delMSE)/(delm) = 2/n.sum_(i=1)^n(-x) ( y_a - (mx+b))^2/n`
Using these differentials, we iterate the values of b and m as follows:
`b = b - "learning_rate" * (delMSE)/(delb)`
`m = m - "learning_rate" * (delMSE)/(delm)`
- Program algorithm:
- Intialize arrays x and y
- Assume and initialize b and m
- Define tolerance. Since the given data set is linear, we can consider a tolerance of 1e-6
- initialize learning rate as 0.001
- Using while loop, perform gradient descent steps till MSE is less than tolerance value
- Print m and b
#Program to perform gradient descent using MSE loss function

x = [1,2,3,4,5]

y = [2,4,6,8,10]

n=len(x)

#y_predicted = mx + b

#Assume m and b
m= 0
b = 0

#tolerance
tol=1e-6

#loss function
mse= 1e9

learning_rate = 0.001
iteration = 1

while mse>tol :
	square_error = 0
	d_dm = 0
	d_db = 0
	for i in range(0,n):
		square_error =  square_error + pow((y[i] - (m*x[i]+b)),2)
		d_dm = d_dm + 2/n*(-x[i]*(y[i] - (m*x[i]+b)))
		d_db = d_db + 2/n*(-1*(y[i] - (m*x[i]+b)))
	mse = square_error/n
	print("\nIteration ="+ str(iteration) + " \nMean Square Error="+str(mse))
	print("m = "+ str(m) + "  b = " + str(b) )
	b= b - learning_rate*d_db
	m = m - learning_rate*d_dm
	iteration = iteration + 1

print("\n\nThe parameters for the best fit line are:\n" + "b = " + str(b) + " m = "+ str(m))
Output:
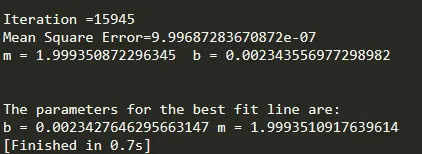
After 15,945 iterations, the values of b and m are found to be 0.00234 and 1.99935 respectively. Hence, the predicted values are determined using equation:
`y_(predicted) = 1.99935 x + 0.00234`
2. Difference between L1 & L2 Gradient descent method
The two major loss functions are:
- Mean Absolute Error
`MAE = (sum_(i=1)^n | y_p - y_a|)/n`
n = total number of data points
`y_p` = predicted outcome
`y_a` = actual outcome
- Mean Square Error
`MSE = (sum_(i=1)^n ( y_p - y_a)^2)/n`
n = total number of data points
`y_p` = predicted outcome
`y_a` = actual outcome
The gradient descent performed using MAE is known as L1 norm whereas the gradient descent using MSE is known as L2 norm.
- L1 vs L2 differences
- As L1 involves absolute error, the error obtained for outlier data points is smaller as compared to the mean square error. As the aim of the gradient descent method is to reduce error/loss function, MAE or L1 norm is preferred for data set with outliers
- The loss function when calculated using L2 or MSE is convex function and this ensures global minima is determined for most cases. On the other hand, using L1 norms, the model may converge at local minima thus resulting in poor prediction of outputs
3. What are the different loss functions for regression?
The different loss functions are:
- Mean Absolute Error
`MAE = (sum_(i=1)^n | y_p - y_a|)/n`
- Mean Square Error
`MSE = (sum_(i=1)^n ( y_p - y_a)^2)/n`
- Root mean square error
`RMS = sqrt((sum_(i=1)^n ( y_p - y_a)^2)/n)`
4. What is the importance of learning rate?
In gradient descent method, the error function is minimised by calculating the tangent at the weights and moving along the convex function in incremental steps. The size of these steps is determined by the learning rate.
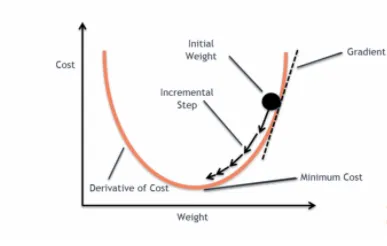
A larger value of learning rate could results in overshooting of the weights and could result in inaccurate value of minima. On the other hand, a smaller value of learning rate improves the accuracy of the algorithm but results in increased computational expenditure.
5. How to evaluate linear regression?
Evaluation of linear regression helps you to understand the performance of your model. There are three major metrics used to evaluate regression model
- `R^2 and adjusted R^2`
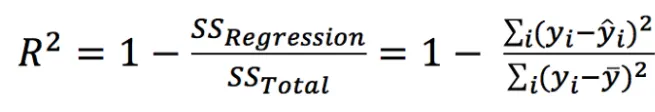
- MSE and RMSE
- MAE
`R^2 and adjusted R^2 are better used to explain the model to other people because you can explain the number as a percentage of the output variability. On the other hand, the other two metrics are used to choose the best amongst the various regression models.
MSE gives a larger error value and may be difficult for comparison of different algorithms. In such cases, it is beneficial to opt for RMSE as the error values are smaller and the dimensionality of the predicted value is same as the actual values.
Furthermore, MSE penalises significantly the outlier data points as compared to MAE. Hence, based on the scenario where outliers points need not be penalized significantly, we choose MAE over MSE.
6. What is the difference between multiple and adjusted coefficient of determination?
When the linear regression involves one dependent variable and one independent variable, the regression model is evaluated by `R^2`or coefficient of determination. In case of a data set with one dependent variable and several independent variable, the model is evaluated using multiple coefficient of determination.
When the regression model is not influenced by some of the independent variables, we opt for adjusted coefficient of determination. Any addition of data point where the independent variable can be ignored does not afffect the value of `R^2`
`R_(adjusted)^2 = 1- ((1-R^2)(n-1))/(n-k-1)`
n= number of data points
k= number of independent variables