Week 5 - Curve fitting
Aim: Fitting a curve to given data and estimating goodness of fit.
Objective:
- To write a program in python which uses a given data file and fit a curve.
- Trying different polynomials, split-wise method to calculate the parameters for perfect fit.
- Check goodness of fit using R2 method.
Introduction:
Curve fitting is the process of constructing a curve, or mathematical function, that has the best fit to a series of data points, possibly subject to constraints. Curve fitting can involve either interpolation, where an exact fit to the data is required, or smoothing.
In curve fitting we have a term named as 'goodness of fit' which can be defined by two technique:
- Graphical method
- statistical method
As is common in statistical literature, the term goodness of fit is used here in several senses: A “good fit” might be a model
- That your data could reasonably have come from, given the assumptions of least-squares fitting
- In which the model coefficients can be estimated with little uncertainty
- That explains a high proportion of the variability in your data, and is able to predict new observations with high certainty
To examine the goodness-of-fit statistics we have several errors to calculate:
- The sum of squares due to error (SSE)
- R-square
- Adjusted R-square
- Root mean squared error (RMSE)
Sum of Squares Due to Error:
This statistic measures the total deviation of the response values from the fit to the response values. It is also called the summed square of residuals and is usually labeled as SSE.
SSE=sum(y(i)-f(x(i)))^2
where y(i)=actual data points
f(x(i))=function used for curve fit
A value closer to 0 indicates that the model has a smaller random error component, and that the fit will be more useful for prediction.
R-Square:
This statistic measures how successful the fit is in explaining the variation of the data. Put another way, R-square is the square of the correlation between the response values and the predicted response values. It is also called the square of the multiple correlation coefficient and the coefficient of multiple determination.
R-square is defined as the ratio of the sum of squares of the regression (SSR) and the total sum of squares (SST). SSR is defined as
SSR= sum(f(x(i))-mean))^2
R-square = SSR/SST =1−(SSE/SST)
R-square can take on any value between 0 and 1, with a value closer to 1 indicating that a greater proportion of variance is accounted for by the model. For example, an R-square value of 0.8234 means that the fit explains 82.34% of the total variation in the data about the average.
If you increase the number of fitted coefficients in your model, R-square will increase although the fit may not improve in a practical sense. To avoid this situation, you should use the degrees of freedom adjusted R-square statistic described below.
Note that it is possible to get a negative R-square for equations that do not contain a constant term. Because R-square is defined as the proportion of variance explained by the fit, if the fit is actually worse than just fitting a horizontal line then R-square is negative. In this case, R-square cannot be interpreted as the square of a correlation. Such situations indicate that a constant term should be added to the model.
Degrees of Freedom Adjusted R-Square:
This statistic uses the R-square statistic defined above, and adjusts it based on the residual degrees of freedom. The residual degrees of freedom is defined as the number of response values n minus the number of fitted coefficients m estimated from the response values.
v = n – m
v indicates the number of independent pieces of information involving the n data points that are required to calculate the sum of squares. Note that if parameters are bounded and one or more of the estimates are at their bounds, then those estimates are regarded as fixed. The degrees of freedom is increased by the number of such parameters.
The adjusted R-square statistic is generally the best indicator of the fit quality when you compare two models that are nested — that is, a series of models each of which adds additional coefficients to the previous model.
adjusted R-square= (1−SSE(n−1))/SST(v)
The adjusted R-square statistic can take on any value less than or equal to 1, with a value closer to 1 indicating a better fit. Negative values can occur when the model contains terms that do not help to predict the response.
Root Mean Squared Error:
This statistic is also known as the fit standard error and the standard error of the regression. It is an estimate of the standard deviation of the random component in the data, and is defined as
RMSE= √GMSE
where MSE is the mean square error or the residual mean square
MSE= (SSE/v)
Just as with SSE, an MSE value closer to 0 indicates a fit that is more useful for prediction.
Steps to write a program/logic:
- Load a data for this we can create a function which will read a file line by line.
- Assign each column of the data to variables and append them in for loop to get set of values in our case its temperature and specific heat.
- from scipy.optimize import curve_fit
- The syntax of curve fit is given as:
popt, pcov = curve_fit(func,var)
popt, pcov = curve_fit(func,temperature,cp)
- Now call the function with name and pass temperature and *popt values to get fit_specific heat value.
- Plot the actual data points with fit_cp and to compare the goodness of
- Use polyfit operator specify the values and degree of polynomial such as linear, quardatic, cubic or nth order with number and assign it to any variable.
- Use polyval command to get the value of variable.
- Plot the polyfit data and actual data points.
- calculate the value of error using r2 method described above and define goodness of fit.
- In case of split-wise curve fitting technique we can divide a data points into several parts and then we can assign polynomial equation for each part.
Python code using scipy module for curve fitting:
import math
import matplotlib.pyplot as plt
import numpy as np
from scipy.optimize import curve_fit

def read_file():
	temperature = []
	cp = []
	for i in open('data','r'):
		values = i.split(',')
		temperature.append(float(values[0]))
		cp.append(float(values[1]))
	return [temperature,cp]

def polynomial_1(t,a,b):
	return(a*t+b)

def polynomial_n(t, a, b, c, d, e, f):
	return (a * t) + (b * t**2) + (c * t**3) + (d * t**4) + (e * t**5) + f

def error(cp,cp_fit):
	SSE = sum((np.array(cp)-np.array(cp_fit))**2)
	SSR = sum((np.array(cp_fit)-np.mean(cp))**2)
	#root mean square error R2 = SSR/SST
	r2 = SSR/(SSR+SSE)
	return(r2)

def read_file():
	temperature = []
	cp = []
	for i in open('data','r'):
		values = i.split(',')
		temperature.append(float(values[0]))
		cp.append(float(values[1]))
	return [temperature,cp]

temperature, cp = read_file()
popt, pcov = curve_fit(polynomial_1, temperature, cp)
fit_cp = polynomial_1(np.array(temperature), *popt)
popt, pcov = curve_fit(polynomial_n, temperature, cp)
fit_cp_n = polynomial_n(np.array(temperature), *popt)


poly1 = error(cp,fit_cp)
poly2 = error(cp,fit_cp_n)
E1 = print('R2 for 1st order polynomial is = ',poly1)
E2 = print('R2 for nth order polynomial is = ',poly2)

plt.figure(1)
plt.title("CURVE FITTING", fontsize='20', backgroundcolor='green', color='white')
plt.plot(temperature,cp,'r--', label= r'actual data')
plt.plot(temperature,fit_cp,'g-',label = r'linear polynomial')
plt.xlabel('temperature')
plt.ylabel('pressure')
plt.savefig('curve_fitting0.png')
plt.legend(loc = 'best')


plt.figure(2)
plt.title("CURVE FITTING", fontsize='20', backgroundcolor='green', color='white')
plt.plot(temperature,cp,'r--', label= r'actual data')
plt.plot(temperature,fit_cp_n,'b-',label = r'nth order polynomial')
plt.xlabel('temperature')
plt.ylabel('pressure')
plt.savefig('curve_fitting1.png')
plt.legend(loc = 'best')
plt.show()
Plots:
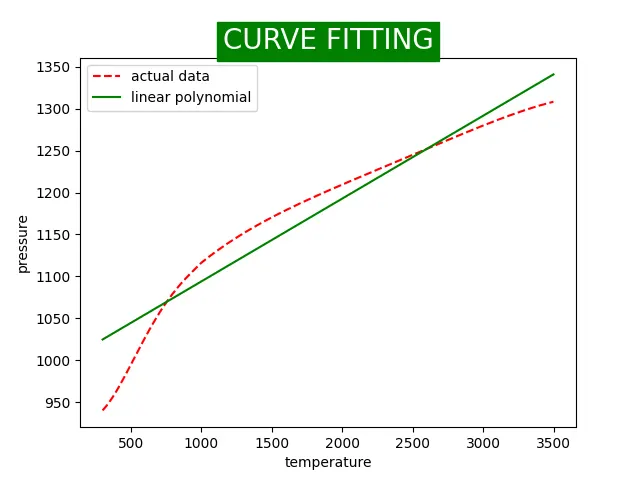
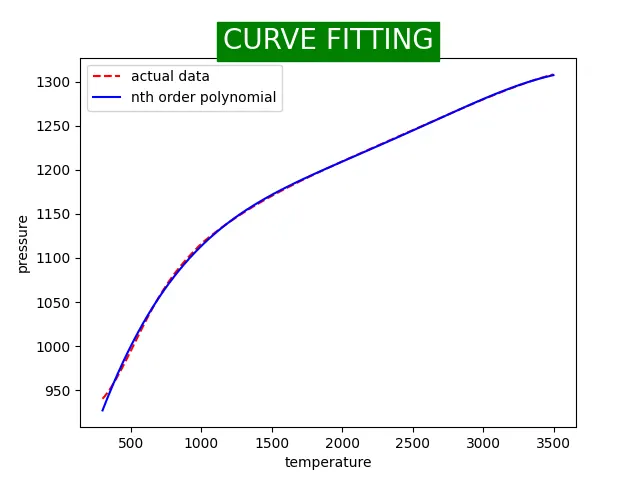
R2 error values:
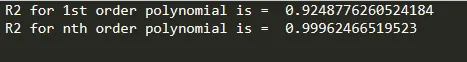
The R2 value near to 1 resembles the fit is good, the value specifies that 0.92,0.99 pecentage of the polynomial resembles actual curve.
There is other way too for writing program for curve fit using numpy module.
Steps:
- Use polyfit operator specify the values and degree of polynomial such as linear, quardatic, cubic or nth order with number and assign it to any variable.
- Use polyval command to get the value of variable.
Python code using numpy module for curve fitting:
import math
import matplotlib.pyplot as plt
import numpy as np
from scipy.optimize import curve_fit


def read_file():
	temperature = []
	cp = []
	for i in open('data','r'):
		values = i.split(',')
		temperature.append(float(values[0]))
		cp.append(float(values[1]))
	return [temperature,cp]

temperature, cp = read_file()

p1 =np.polyfit(temperature,cp,2)
fit_cp1 = np.polyval(p1,temperature)
p2 =np.polyfit(temperature,cp,3)
fit_cp2 = np.polyval(p2,temperature)

#root mean square error
#Error for 2nd order polynomial
#SSE = Sum of squares due to error
def error(cp,cp_fit):
	SSE = sum((np.array(cp)-np.array(cp_fit))**2)
	SSR = sum((np.array(cp_fit)-np.mean(cp))**2)
	#root mean square error R2 = SSR/SST
	r2 = SSR/(SSR+SSE)
	return(r2)

poly1 = error(cp,fit_cp1)
poly2 = error(cp,fit_cp2)
print('R2 for second order polynomial is = ',poly1)
print('R2 for third order polynomial is = ',poly2)


plt.figure(1)
plt.title("CURVE FITTING", fontsize='20', backgroundcolor='green', color='white')
plt.plot(temperature,cp,'r--', label= r'actual data')
plt.plot(temperature,fit_cp1,'g-',label = r'quadratic polynomial')
plt.xlabel('temperature')
plt.ylabel('pressure')
plt.savefig('curve_fitting2.png')
plt.legend(loc = 'best')


plt.figure(2)
plt.title("CURVE FITTING", fontsize='20', backgroundcolor='green', color='white')
plt.plot(temperature,cp,'r--', label= r'actual data')
plt.plot(temperature,fit_cp2,'b-',label = r'cubic polynomial')
plt.xlabel('temperature')
plt.ylabel('pressure')
plt.savefig('curve_fitting3.png')
plt.legend(loc = 'best')
plt.show()
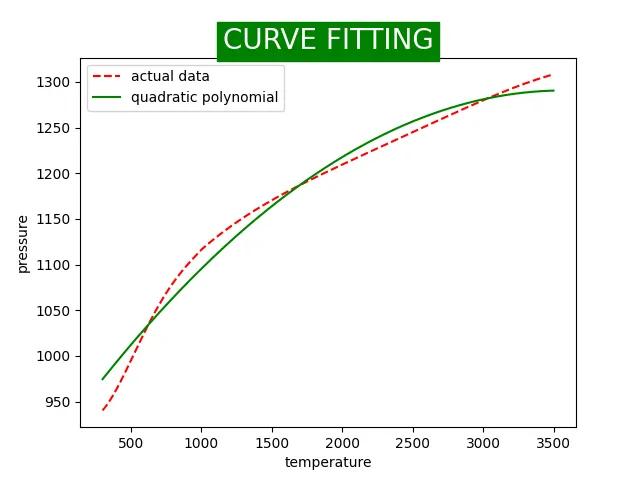
Plots:
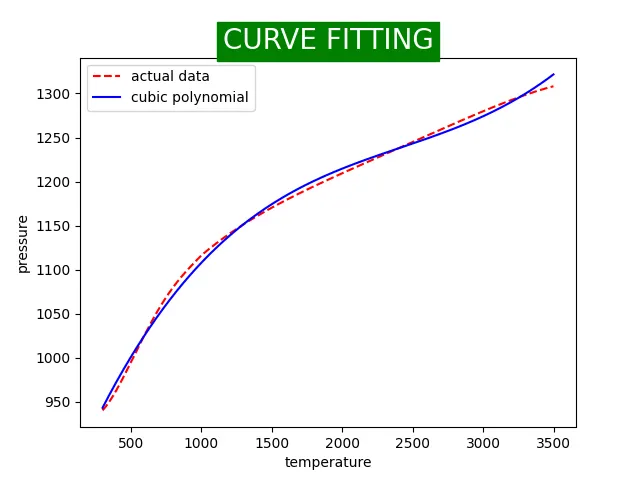
R2 error values:
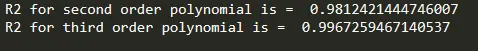
Error value for quadratic and cubic polynomials.
Python code using split-wise method for curve fitting:
import math
import matplotlib.pyplot as plt
import numpy as np

def read_file():
	temperature = []
	cp = []
	for i in open('data','r'):
		values = i.split(',')
		temperature.append(float(values[0]))
		cp.append(float(values[1]))
	return [temperature,cp]

temperature, cp = read_file()

temp1 = temperature[1:640]
cp1 = cp[1:640]

temp2 = temperature[641:1280]
cp2 = cp[641:1280]

temp3 = temperature[1281:1920]
cp3 = cp[1281:1920]

temp4 = temperature[1921:2560]
cp4 = cp[1921:2560]

temp5 = temperature[2561:3200]
cp5 = cp[2561:3200]

p1 =np.polyfit(temp1,cp1,2)
fit_cp1 = np.polyval(p1,temp1)

p2 =np.polyfit(temp2,cp2,2)
fit_cp2 = np.polyval(p2,temp2)

p3 =np.polyfit(temp3,cp3,2)
fit_cp3 = np.polyval(p3,temp3)

p4 =np.polyfit(temp4,cp4,2)
fit_cp4 = np.polyval(p4,temp4)

p5 =np.polyfit(temp5,cp5,2)
fit_cp5 = np.polyval(p5,temp5)


plt.plot(temperature,cp,'r--')
plt.plot(temp1,fit_cp1,'g-')
plt.plot(temp2,fit_cp2,'g-')
plt.plot(temp3,fit_cp3,'g-')
plt.plot(temp4,fit_cp4,'g-')
plt.plot(temp5,fit_cp5,'g-')
plt.show()
Plot:
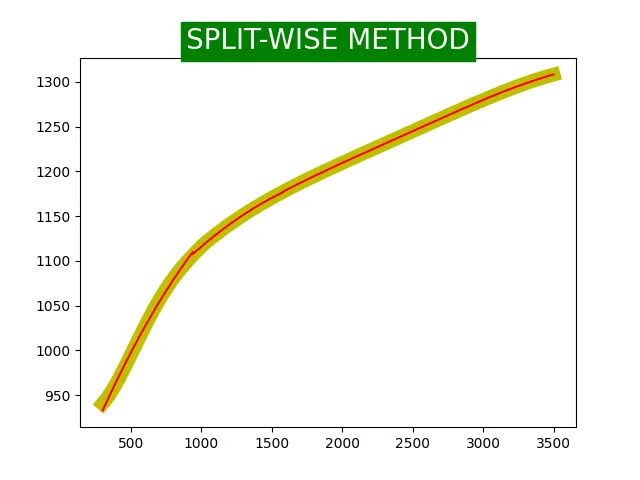
For split-wise method we get the exact curve to actual value and the r2 value is 1, this method is one of the best for getting good fit.
1.What does popt and pcov mean ?
- The popt resembles the optimization of parameters, the parameters here depends on order of polynomial, for linear polynomial there are '2' parameters for quadratic '3' and so on.
The PCOV variable contains the covariance matrix, which indicates the uncertainties and correlations between parameters. This is mostly useful when the data has uncertainties.
2. What does np.array(temperature) do ?
- A np.array is a grid of values,and the np.array(temperature) here resembles the grid of values of same type 'temperature, and is indexed by a tuple of nonnegative integers.
A tuple is a collection which is ordered and unchangeable.
3. What does the * in *popt mean?
- The *popt means we are considering all the parameters such as in equation ax+b the parameters are (a,b), once we have optimized the parameters we should use them to calculate our function and final value is being compared with actual values
How to make a curve fit perfectly?
The perfect curve fit is something in which the fit we get must follow the actual data points .the fit must go through all the points tracing the curve . Using interpolation technique we can get the perfect curve fit.
How to get the best fit?
The best fit is one in which the difference of y for model and that actual curve is minimized .The techniques to get a best fit are:
- Using higher order polynomial.
- Using different optimization techniques for example fminsearch.
ERRORS: No errors
Conclusion:
While programming this challenge I learnt various methods for curve fitting how to check goodness of fit and found out different methods for the curve fitting.
To get a best fit we can use split-wise method and higher order polynomial or interpolation method