Supervised Learning - Prediction Week 3 Challenge
1.pfa
2.
|
Mean absolute error |
Mean square error |
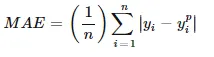 |
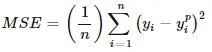 |
|
Sum of absolute differences between target and predicted variables |
Sum of squared differences between target and predicted variables |
|
Error is minimal as there is no square |
Error is high as there is square especially if e >1 |
3. The different loss functions are
a) Mean absolute error
b) Mean square error
c)Huber loss, Smooth mean abs error
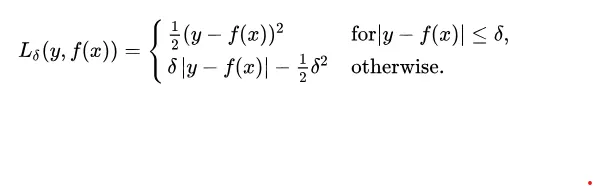
d) Log cosh loss
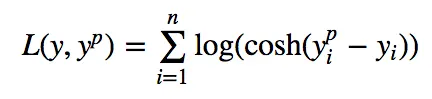 .
4.
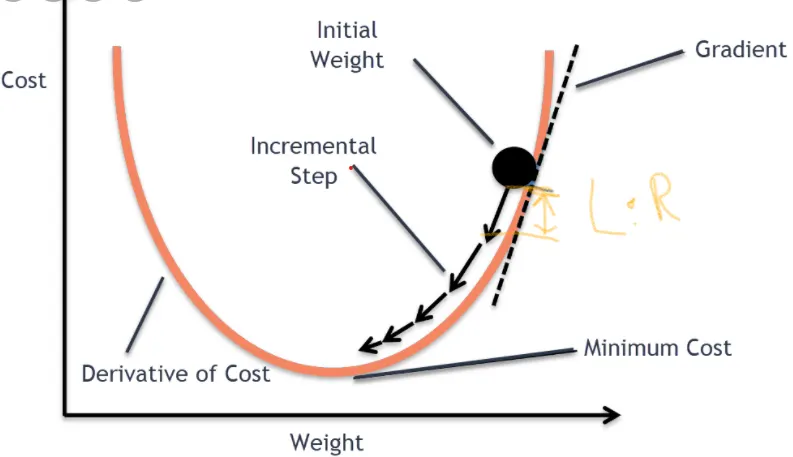
Stochastic gradient descent is an optimization algorithm that estimates the error gradient for the current state of the model using examples from the training dataset, then updates the weights of the model using the back-propagation of errors algorithm, referred to as simply backpropagation.
The amount that the weights are updated during training is referred to as the step size or the “learning rate.”
5. There are different ways for evaluating a linear regression model. Evaluating basically does determine the fit by calculating the error between the actual values predicted data set.
The primary objective is to find the variations of Y using the knowledge of X.
Coefficient of determination = R^2 = SSR/SST = 1- (SSE/SST)
where
SST is the sum of squares of total variation, SSR is the sum of squares of explained variation due
to the regression model, and SSE is the sum of squares of unexplained variation (error).
6.If the dependent variables depend on multiple independent variables its is called multiple coefficient of determination .
The adjusted coefficient of determination is a method in which the parameters do not contribute towards the predicted value
Multiple R squared is simply a measure of Rsquared for models that have multiple predictor variables. Therefore it measures the amount of variation in the response variable that can be explained by the predictor variables.
Adjusted Rsquared controls against this increase, and adds penalties for the number of predictors in the model. Therefore it shows a balance between the most parsimonious model, and the best fitting model.