Supervised Learning - Classification Week 8 Challenge
1) Apply knn to the “Surface defects in stainless steel plates” and identify the difference
KNN is a simple algorithm, based on the local minimum of the target function which is used to learn an unknown function of desired precision and accuracy. The algorithm also finds the neighborhood of an unknown input, its range or distance from it, and other parameters. It’s based on the principle of “information gain”—the algorithm finds out which is most suitable to predict an unknown value.
KNN is widely known as an ML algorithm that doesn’t need any training on data. This is much different from eager learning approaches that rely on a training dataset to perform predictions on unseen data. With KNN, you don’t need a training phase at all.
import pandas as pd
import matplotlib.pyplot as plt
import seaborn as sn
import scipy.stats as stats
steels= pd.read_csv('faults.csv')
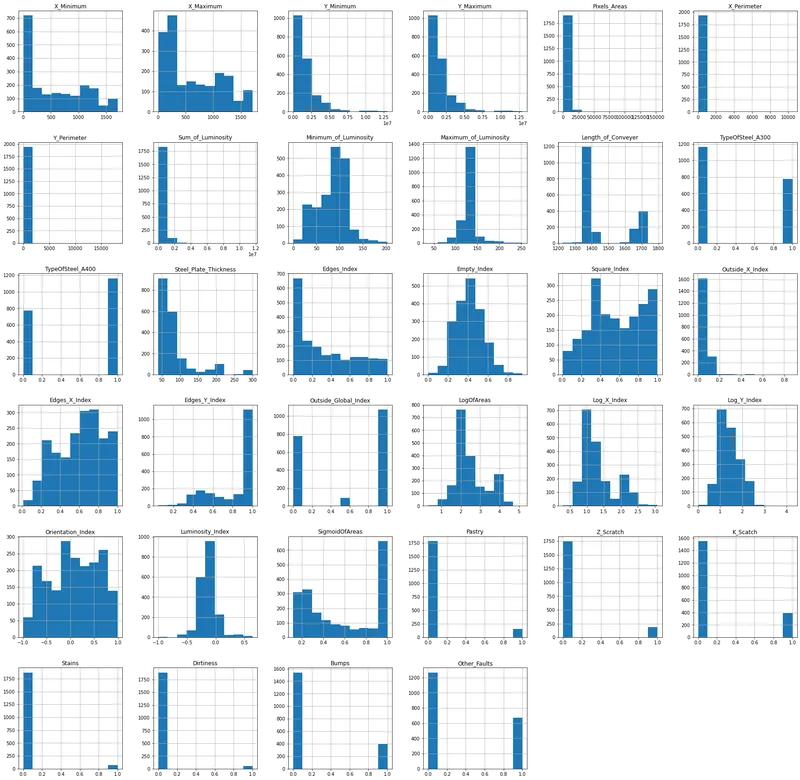
steels.hist(figsize=(30,30))
plt.show()
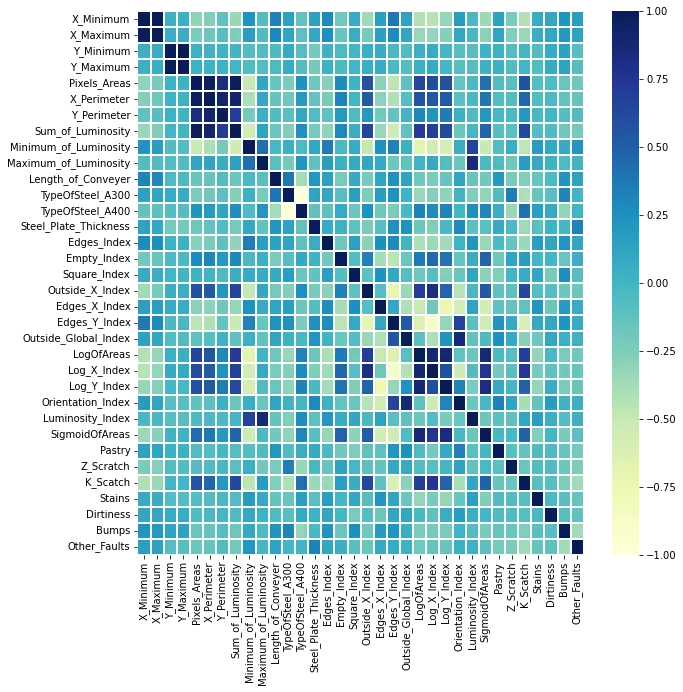
corrmat = steels.corr()
f, ax = plt.subplots(figsize=(10,10))
sn.heatmap(corrmat, ax=ax, cmap="YlGnBu", linewidths = 0.1)
plt.show()
pd.set_option('display.max_columns', None)
factors=steels.iloc[:, 0:27]
df=steels.iloc[:, 27:34]
factors_zscore = stats.zscore(factors)
df['Class']=0
df['DefType']=''
df.loc[df.Pastry==1,'Class'] =
df.loc[df.Z_Scratch==1,'Class'] = 2
df.loc[df.K_Scatch==1,'Class'] = 3
df.loc[df.Stains==1,'Class'] = 4
df.loc[df.Dirtiness==1,'Class'] = 5
df.loc[df.Bumps==1,'Class'] = 6
df.loc[df.Other_Faults==1,'Class'] = 7
df.loc[df.Pastry==1,'DefType'] = 'Pastry'
df.loc[df.Z_Scratch==1,'DefType'] = 'Z_Scratch'
df.loc[df.K_Scatch==1,'DefType'] = 'K_Scatch'
df.loc[df.Stains==1,'DefType'] = 'Stains'
df.loc[df.Dirtiness==1,'DefType'] = 'Dirtiness'
df.loc[df.Bumps==1,'DefType'] = 'Bumps'
df.loc[df.Other_Faults==1,'DefType'] = 'Other_Faults'
df.drop(['Pastry','Z_Scratch','K_Scatch','Stains','Dirtiness','Bumps','Other_Faults','DefType'], axis=1, inplace=True)
print(df.describe())
print(df.head())
print(df)
print(factors)
print(factors.describe())
print(factors.head())
Class
count 1941.000000
mean 4.841319
std 2.144175
min 1.000000
25% 3.000000
50% 6.000000
75% 7.000000
max 7.000000
Class
0 1
1 1
2 1
3 1
4 1
Class
0 1
1 1
2 1
3 1
4 1
... ...
1936 7
1937 7
1938 7
1939 7
1940 7
[1941 rows x 1 columns]
X_Minimum X_Maximum Y_Minimum Y_Maximum Pixels_Areas X_Perimeter \
0 42 50 270900 270944 267 17
1 645 651 2538079 2538108 108 10
2 829 835 1553913 1553931 71 8
3 853 860 369370 369415 176 13
4 1289 1306 498078 498335 2409 60
... ... ... ... ... ... ...
1936 249 277 325780 325796 273 54
1937 144 175 340581 340598 287 44
1938 145 174 386779 386794 292 40
1939 137 170 422497 422528 419 97
1940 1261 1281 87951 87967 103 26
Y_Perimeter Sum_of_Luminosity Minimum_of_Luminosity \
0 44 24220 76
1 30 11397 84
2 19 7972 99
3 45 18996 99
4 260 246930 37
... ... ... ...
1936 22 35033 119
1937 24 34599 112
1938 22 37572 120
1939 47 52715 117
1940 22 11682 101
Maximum_of_Luminosity Length_of_Conveyer TypeOfSteel_A300 \
0 108 1687 1
1 123 1687 1
2 125 1623 1
3 126 1353 0
4 126 1353 0
... ... ... ...
1936 141 1360 0
1937 133 1360 0
1938 140 1360 0
1939 140 1360 0
1940 133 1360 1
TypeOfSteel_A400 Steel_Plate_Thickness Edges_Index Empty_Index \
0 0 80 0.0498 0.2415
1 0 80 0.7647 0.3793
2 0 100 0.9710 0.3426
3 1 290 0.7287 0.4413
4 1 185 0.0695 0.4486
... ... ... ... ...
1936 1 40 0.3662 0.3906
1937 1 40 0.2118 0.4554
1938 1 40 0.2132 0.3287
1939 1 40 0.2015 0.5904
1940 0 80 0.1162 0.6781
Square_Index Outside_X_Index Edges_X_Index Edges_Y_Index \
0 0.1818 0.0047 0.4706 1.0000
1 0.2069 0.0036 0.6000 0.9667
2 0.3333 0.0037 0.7500 0.9474
3 0.1556 0.0052 0.5385 1.0000
4 0.0662 0.0126 0.2833 0.9885
... ... ... ... ...
1936 0.5714 0.0206 0.5185 0.7273
1937 0.5484 0.0228 0.7046 0.7083
1938 0.5172 0.0213 0.7250 0.6818
1939 0.9394 0.0243 0.3402 0.6596
1940 0.8000 0.0147 0.7692 0.7273
Outside_Global_Index LogOfAreas Log_X_Index Log_Y_Index \
0 1.0 2.4265 0.9031 1.6435
1 1.0 2.0334 0.7782 1.4624
2 1.0 1.8513 0.7782 1.2553
3 1.0 2.2455 0.8451 1.6532
4 1.0 3.3818 1.2305 2.4099
... ... ... ... ...
1936 0.0 2.4362 1.4472 1.2041
1937 0.0 2.4579 1.4914 1.2305
1938 0.0 2.4654 1.4624 1.1761
1939 0.0 2.6222 1.5185 1.4914
1940 0.0 2.0128 1.3010 1.2041
Orientation_Index Luminosity_Index SigmoidOfAreas
0 0.8182 -0.2913 0.5822
1 0.7931 -0.1756 0.2984
2 0.6667 -0.1228 0.2150
3 0.8444 -0.1568 0.5212
4 0.9338 -0.1992 1.0000
... ... ... ...
1936 -0.4286 0.0026 0.7254
1937 -0.4516 -0.0582 0.8173
1938 -0.4828 0.0052 0.7079
1939 -0.0606 -0.0171 0.9919
1940 -0.2000 -0.1139 0.5296
[1941 rows x 27 columns]
X_Minimum X_Maximum Y_Minimum Y_Maximum Pixels_Areas \
count 1941.000000 1941.000000 1.941000e+03 1.941000e+03 1941.000000
mean 571.136012 617.964451 1.650685e+06 1.650739e+06 1893.878413
std 520.690671 497.627410 1.774578e+06 1.774590e+06 5168.459560
min 0.000000 4.000000 6.712000e+03 6.724000e+03 2.000000
25% 51.000000 192.000000 4.712530e+05 4.712810e+05 84.000000
50% 435.000000 467.000000 1.204128e+06 1.204136e+06 174.000000
75% 1053.000000 1072.000000 2.183073e+06 2.183084e+06 822.000000
max 1705.000000 1713.000000 1.298766e+07 1.298769e+07 152655.000000
X_Perimeter Y_Perimeter Sum_of_Luminosity Minimum_of_Luminosity \
count 1941.000000 1941.000000 1.941000e+03 1941.000000
mean 111.855229 82.965997 2.063121e+05 84.548686
std 301.209187 426.482879 5.122936e+05 32.134276
min 2.000000 1.000000 2.500000e+02 0.000000
25% 15.000000 13.000000 9.522000e+03 63.000000
50% 26.000000 25.000000 1.920200e+04 90.000000
75% 84.000000 83.000000 8.301100e+04 106.000000
max 10449.000000 18152.000000 1.159141e+07 203.000000
Maximum_of_Luminosity Length_of_Conveyer TypeOfSteel_A300 \
count 1941.000000 1941.000000 1941.000000
mean 130.193715 1459.160227 0.400309
std 18.690992 144.577823 0.490087
min 37.000000 1227.000000 0.000000
25% 124.000000 1358.000000 0.000000
50% 127.000000 1364.000000 0.000000
75% 140.000000 1650.000000 1.000000
max 253.000000 1794.000000 1.000000
TypeOfSteel_A400 Steel_Plate_Thickness Edges_Index Empty_Index \
count 1941.000000 1941.000000 1941.000000 1941.000000
mean 0.599691 78.737764 0.331715 0.414203
std 0.490087 55.086032 0.299712 0.137261
min 0.000000 40.000000 0.000000 0.000000
25% 0.000000 40.000000 0.060400 0.315800
50% 1.000000 70.000000 0.227300 0.412100
75% 1.000000 80.000000 0.573800 0.501600
max 1.000000 300.000000 0.995200 0.943900
Square_Index Outside_X_Index Edges_X_Index Edges_Y_Index \
count 1941.000000 1941.000000 1941.000000 1941.000000
mean 0.570767 0.033361 0.610529 0.813472
std 0.271058 0.058961 0.243277 0.234274
min 0.008300 0.001500 0.014400 0.048400
25% 0.361300 0.006600 0.411800 0.596800
50% 0.555600 0.010100 0.636400 0.947400
75% 0.818200 0.023500 0.800000 1.000000
max 1.000000 0.875900 1.000000 1.000000
Outside_Global_Index LogOfAreas Log_X_Index Log_Y_Index \
count 1941.000000 1941.000000 1941.000000 1941.000000
mean 0.575734 2.492388 1.335686 1.403271
std 0.482352 0.788930 0.481612 0.454345
min 0.000000 0.301000 0.301000 0.000000
25% 0.000000 1.924300 1.000000 1.079200
50% 1.000000 2.240600 1.176100 1.322200
75% 1.000000 2.914900 1.518500 1.732400
max 1.000000 5.183700 3.074100 4.258700
Orientation_Index Luminosity_Index SigmoidOfAreas
count 1941.000000 1941.000000 1941.000000
mean 0.083288 -0.131305 0.585420
std 0.500868 0.148767 0.339452
min -0.991000 -0.998900 0.119000
25% -0.333300 -0.195000 0.248200
50% 0.095200 -0.133000 0.506300
75% 0.511600 -0.066600 0.999800
max 0.991700 0.642100 1.000000
X_Minimum X_Maximum Y_Minimum Y_Maximum Pixels_Areas X_Perimeter \
0 42 50 270900 270944 267 17
1 645 651 2538079 2538108 108 10
2 829 835 1553913 1553931 71 8
3 853 860 369370 369415 176 13
4 1289 1306 498078 498335 2409 60
Y_Perimeter Sum_of_Luminosity Minimum_of_Luminosity \
0 44 24220 76
1 30 11397 84
2 19 7972 99
3 45 18996 99
4 260 246930 37
Maximum_of_Luminosity Length_of_Conveyer TypeOfSteel_A300 \
0 108 1687 1
1 123 1687 1
2 125 1623 1
3 126 1353 0
4 126 1353 0
TypeOfSteel_A400 Steel_Plate_Thickness Edges_Index Empty_Index \
0 0 80 0.0498 0.2415
1 0 80 0.7647 0.3793
2 0 100 0.9710 0.3426
3 1 290 0.7287 0.4413
4 1 185 0.0695 0.4486
Square_Index Outside_X_Index Edges_X_Index Edges_Y_Index \
0 0.1818 0.0047 0.4706 1.0000
1 0.2069 0.0036 0.6000 0.9667
2 0.3333 0.0037 0.7500 0.9474
3 0.1556 0.0052 0.5385 1.0000
4 0.0662 0.0126 0.2833 0.9885
Outside_Global_Index LogOfAreas Log_X_Index Log_Y_Index \
0 1.0 2.4265 0.9031 1.6435
1 1.0 2.0334 0.7782 1.4624
2 1.0 1.8513 0.7782 1.2553
3 1.0 2.2455 0.8451 1.6532
4 1.0 3.3818 1.2305 2.4099
Orientation_Index Luminosity_Index SigmoidOfAreas
0 0.8182 -0.2913 0.5822
1 0.7931 -0.1756 0.2984
2 0.6667 -0.1228 0.2150
3 0.8444 -0.1568 0.5212
4 0.9338 -0.1992 1.0000
from sklearn.neighbors import KNeighborsClassifier
from sklearn.model_selection import train_test_split
X_train, X_test, y_train, y_test = train_test_split(factors_zscore, df, test_size = 0.2, random_state=0)
knn = KNeighborsClassifier(n_neighbors=7)
knn.fit(X_train, y_train)
# Predict on dataset which model has not seen before
print(knn.predict(X_test))
# Calculate the accuracy of the model
print('score = ',knn.score(X_test, y_test))
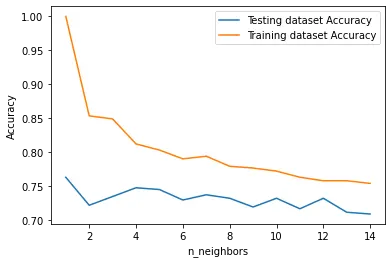
neighbors = np.arange(1, 15)
train_accuracy = np.empty(len(neighbors))
test_accuracy = np.empty(len(neighbors))
[4 3 3 2 6 5 3 6 1 7 7 7 7 7 6 7 3 7 5 7 2 1 6 7 7 3 3 2 7 1 3 6 1 3 6 7 7
 6 7 3 7 2 3 2 6 7 3 6 3 7 6 3 3 2 4 4 6 7 7 2 3 4 6 6 6 6 3 6 2 3 2 7 3 2
 6 6 5 3 7 6 1 1 6 3 6 1 3 1 7 1 7 6 7 7 5 7 1 7 7 4 7 3 7 7 3 7 3 2 7 1 6
 3 1 6 2 7 6 3 7 7 6 6 7 6 1 4 7 7 7 6 2 5 7 6 3 4 7 7 7 7 6 7 6 3 1 2 7 5
 6 7 7 6 6 7 7 6 6 2 7 7 7 7 1 3 7 6 5 7 3 7 6 3 3 7 3 4 7 2 4 3 3 3 3 3 4
 7 5 7 3 3 2 6 7 7 6 1 6 2 3 7 7 2 1 3 3 3 6 2 6 6 3 2 6 7 6 3 3 3 7 6 7 6
 2 1 2 4 7 6 1 3 5 6 7 7 7 7 3 3 6 6 6 3 6 2 3 7 4 2 3 6 7 3 7 6 3 6 6 6 2
 6 3 3 7 6 6 6 7 2 6 3 6 6 3 2 6 3 6 2 7 6 2 7 7 6 6 6 3 6 2 7 7 7 3 7 6 6
 6 6 6 7 3 4 3 2 7 1 3 6 7 1 6 6 7 7 7 7 7 3 7 1 6 6 6 7 1 7 1 7 7 7 6 7 2
 6 4 2 1 2 7 6 6 3 1 3 7 6 6 6 7 3 3 7 1 2 7 5 4 7 2 7 3 2 7 2 2 3 3 2 7 7
 2 7 7 6 7 6 6 6 7 6 6 7 6 2 6 7 1 7 7]
score =  0.7377892030848329
plt.plot(neighbors, test_accuracy, label = 'Testing dataset Accuracy')
plt.plot(neighbors, train_accuracy, label = 'Training dataset Accuracy')
plt.legend()
plt.xlabel('n_neighbors')
plt.ylabel('Accuracy')
plt.show()
Y_predict = knn.predict(X_test)
from sklearn import metrics
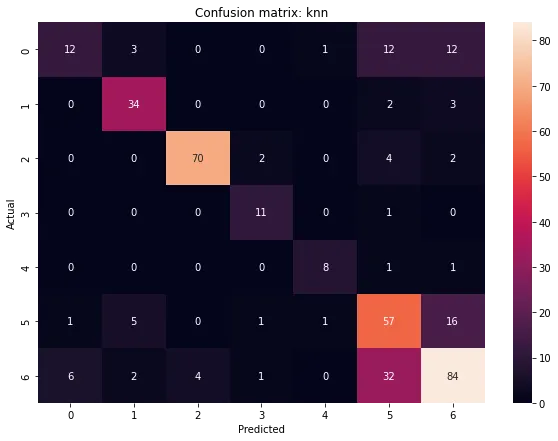
cm = metrics.confusion_matrix(y_test, Y_predict)
print(cm)
print(cm.shape)
print(type(cm))
print(cm[0, 0])
import seaborn as sn
plt.figure(figsize=(10, 7))
sn.heatmap(cm, annot=True)
plt.xlabel("Predicted")
plt.ylabel("Actual")
plt.title('Confusion matrix: knn')
plt.show()
[[12  3  0  0  1 12 12]
 [ 0 34  0  0  0  2  3]
 [ 0  0 70  2  0  4  2]
 [ 0  0  0 11  0  1  0]
 [ 0  0  0  0  8  1  1]
 [ 1  5  0  1  1 57 16]
 [ 6  2  4  1  0 32 84]]
(7, 7)
<class 'numpy.ndarray'>
12
from sklearn import svm
clf = svm.SVC(kernel='linear')
clf.fit(X_train, y_train)
Y_predict_svm = clf.predict(X_test)
cm = metrics.confusion_matrix(y_test, Y_predict_svm)
print(cm)
print(cm.shape)
print(type(cm))
print(cm[0, 0])
import seaborn as sn
plt.figure(figsize=(10, 7))
sn.heatmap(cm, annot=True)
plt.xlabel("Predicted")
plt.ylabel("Actual")
plt.title('Confusion matrix: SVM')
plt.show()
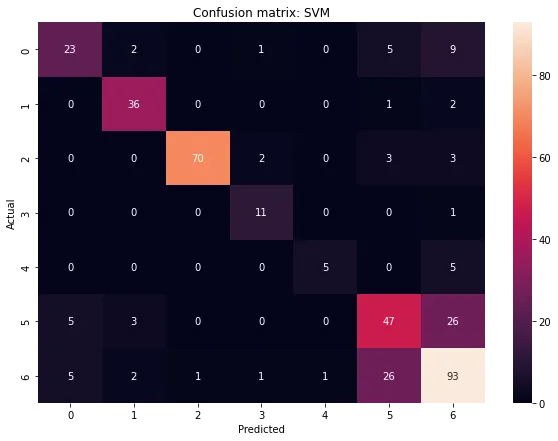
[[23  2  0  1  0  5  9]
 [ 0 36  0  0  0  1  2]
 [ 0  0 70  2  0  3  3]
 [ 0  0  0 11  0  0  1]
 [ 0  0  0  0  5  0  5]
 [ 5  3  0  0  0 47 26]
 [ 5  2  1  1  1 26 93]]
(7, 7)
<class 'numpy.ndarray'>
23
from sklearn.tree import DecisionTreeClassifier
clf_tree = DecisionTreeClassifier(criterion = "entropy", random_state = 100, max_depth = 3, min_samples_leaf = 5)
# Performing training
clf_tree.fit(X_train, y_train)
Y_predict_tree = clf_tree.predict(X_test)
cm = metrics.confusion_matrix(y_test, Y_predict_tree)
print(cm)
print(cm.shape)
print(type(cm))
print(cm[0, 0])
import seaborn as sn
plt.figure(figsize=(10, 7))
sn.heatmap(cm, annot=True)
plt.xlabel("Predicted")
plt.ylabel("Actual")
plt.title('Confusion matrix: Decision tree')
plt.show()
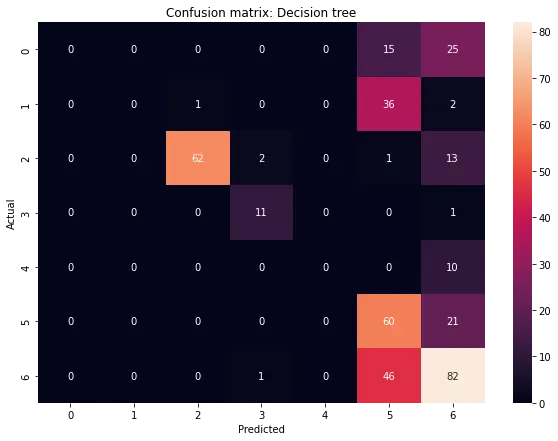
[[ 0  0  0  0  0 15 25]
 [ 0  0  1  0  0 36  2]
 [ 0  0 62  2  0  1 13]
 [ 0  0  0 11  0  0  1]
 [ 0  0  0  0  0  0 10]
 [ 0  0  0  0  0 60 21]
 [ 0  0  0  1  0 46 82]]
(7, 7)
<class 'numpy.ndarray'>
0
clf_rf=RandomForestClassifier(n_estimators = 100, random_state = 0)
clf_rf.fit(X_train, y_train)
Y_predict_rf = clf_rf.predict(X_test)
cm = metrics.confusion_matrix(y_test, Y_predict_rf)
print(cm)
print(cm.shape)
print(type(cm))
print(cm[0, 0])
import seaborn as sn
plt.figure(figsize=(10, 7))
sn.heatmap(cm, annot=True)
plt.xlabel("Predicted")
plt.ylabel("Actual")
plt.title('Confusion matrix: Random forest')
plt.show()
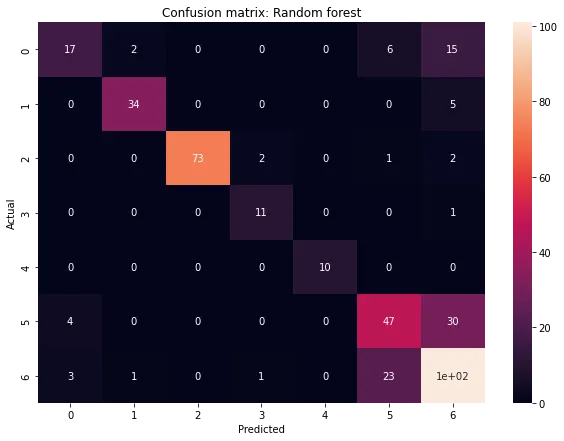
[[ 17   2   0   0   0   6  15]
 [  0  34   0   0   0   0   5]
 [  0   0  73   2   0   1   2]
 [  0   0   0  11   0   0   1]
 [  0   0   0   0  10   0   0]
 [  4   0   0   0   0  47  30]
 [  3   1   0   1   0  23 101]]
(7, 7)
<class 'numpy.ndarray'>
17
from sklearn.linear_model import LinearRegression
regr = LinearRegression()
regr.fit(X_train, y_train)
Y_predict_reg = regr.predict(X_test)
print('Regression = ', regr.predict(X_test))
print('knn = ', knn.predict(X_test))
print('SVM = ', clf.predict(X_test))
print('Decision tree = ', clf_tree.predict(X_test))
print('Random forest = ', clf_rf.predict(X_test))
score_lr=regr.score(X_test, y_test)
print('Score of linear regression = ',score_lr)
score_knn=knn.score(X_test, y_test)
print('Score of knn = ',score_knn)
score_svm=clf.score(X_test, y_test)
print('Score of SVM = ',score_svm)
score_tree=clf_tree.score(X_test, y_test)
print('Score of decision tree = ',score_tree)
score_rf=clf_rf.score(X_test, y_test)
print('Score of random forest = ',score_rf)
Regression =  [[5.22588405]
 [3.53872548]
 [1.72446934]
 [4.73715225]
 [4.76560934]
 [4.3932702 ]
 [4.74762018]
 [5.8344865 ]
 [3.99686633]
 [5.17305894]
 [4.92404818]
 [6.54047949]
 [5.2341654 ]
 [4.73919863]
 [5.69739848]
 [6.16304004]
2) What are the pros and cons of knn
Pros
1) No Training Period
KNN modeling does not include a training period as the data itself is a model which will be the reference for future prediction and because of this it is very time efficient in terms of improvising for random modeling on the available data.
2) Easy Implementation
KNN is very easy to implement as the only thing to be calculated is the distance between different points on the basis of data of different features and this distance can easily be calculated using distance formulas such as- Euclidian or Manhattan
3) As there is no training period thus new data can be added at any time since it won't affect the model.
4) K-NN is pretty intuitive and simple:
K-NN algorithm is very simple to understand and equally easy to implement. To classify the new data point K-NN algorithm reads through whole dataset to find out K nearest neighbors.
5)K-NN has no assumptions:
K-NN is a non-parametric algorithm which means there are assumptions to be met to implement K-NN. Parametric models like linear regression has lots of assumptions to be met by data before it can be implemented which is not the case with K-NN.
Cons
1) Does not work well with large datasets as calculating distances between each data instance would be very costly.
2) Does not work well with high dimensionality as this will complicate the distance calculating process to calculate the distance for each dimension.
3) Sensitive to noisy and missing data
4) Feature Scaling
Data in all the dimensions should be scaled (normalized and standardized) properly.
5) K-NN slow algorithm:
K-NN might be very easy to implement but as dataset grows efficiency or speed of algorithm declines very fast.