Supervised Learning - Classification Week 7 Challenge
1) Pros and cons of SVM
SVM
1) SVM stands for support vector machines.SVM is simple and provides good accuracy with less computational power, SVM is also used for regression but is widely applied for classification projects. There are several hyperplanes possible to classify the data points, but the optimal hyperplane is the one with the maximum margin.
2) The name support vector machines is because the data points closest to the hyperplane are called support vectors as these points decide the optimal position of hyperplanes. changing the position of the support vector will change the position orientation of the hyperplane and also these support vectors are used to maximize the margin.
1)Pros:
1)It works really well with a clear margin of separation
2)It is effective in high-dimensional spaces.
3) It is effective in cases where the number of dimensions is greater than the number of samples.
4) It uses a subset of training points in the decision function (called support vectors), so it is also memory efficient
2)Cons:
1) It doesn’t perform well when we have large data set because the required training time is higher
2) It also doesn’t perform very well when the data set has more noise i.e. target classes are overlapping
3)SVM doesn’t directly provide probability estimates, these are calculated using an expensive five-fold cross-validation. It is included in, the related SVC method of the Python scikit-learn library.
4) SVM algorithm is not suitable for the large data set
5) As the support vector classifier works by putting data points, above and below the classifying hyperplane there is no probabilistic, explanation for the classification.
2) Apply SVM to the “Surface defects in stainless steel plates” dataset and evaluate it
import pandas as pd
import numpy as np
import matplotlib.pyplot as plt
import seaborn as sn
import scipy.stats as stats
steel = pd.read_csv( 'faults.csv')
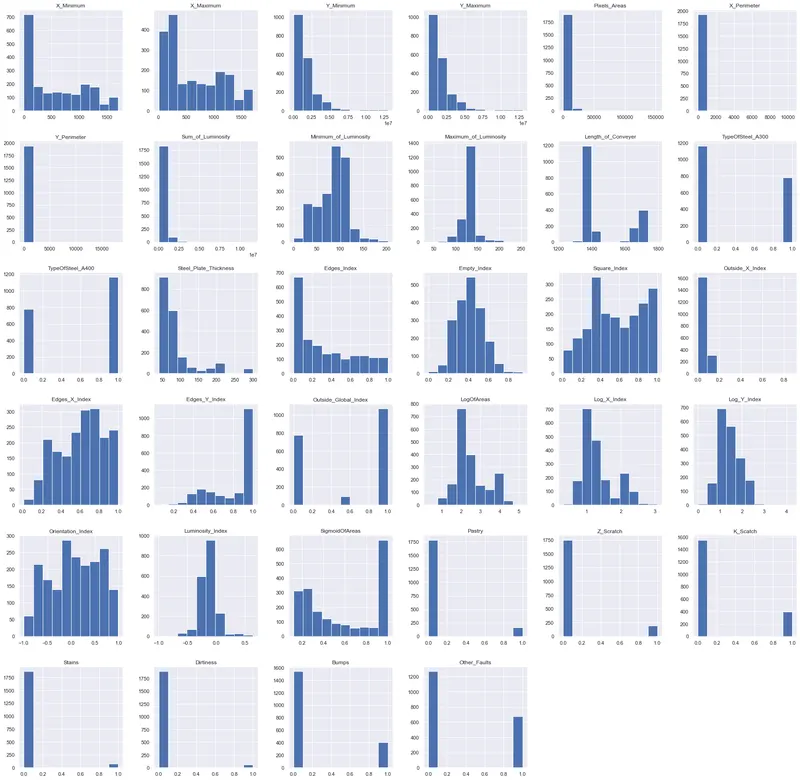
steel.hist(figsize=(30,30))
plt.show()
print('steel head command = ', steel.head())
steel head command =     X_Minimum  X_Maximum  Y_Minimum  Y_Maximum  Pixels_Areas  X_Perimeter  \
0         42         50     270900     270944           267           17
1        645        651    2538079    2538108           108           10
2        829        835    1553913    1553931            71            8
3        853        860     369370     369415           176           13
4       1289       1306     498078     498335          2409           60

   Y_Perimeter  Sum_of_Luminosity  Minimum_of_Luminosity  \
0           44              24220                     76
1           30              11397                     84
2           19               7972                     99
3           45              18996                     99
4          260             246930                     37

   Maximum_of_Luminosity  ...  Orientation_Index  Luminosity_Index  \
0                    108  ...             0.8182           -0.2913
1                    123  ...             0.7931           -0.1756
2                    125  ...             0.6667           -0.1228
3                    126  ...             0.8444           -0.1568
4                    126  ...             0.9338           -0.1992

   SigmoidOfAreas  Pastry  Z_Scratch  K_Scatch  Stains  Dirtiness  Bumps  \
0          0.5822       1          0         0       0          0      0
1          0.2984       1          0         0       0          0      0
2          0.2150       1          0         0       0          0      0
3          0.5212       1          0         0       0          0      0
4          1.0000       1          0         0       0          0      0

   Other_Faults
0             0
1             0
2             0
3             0
4             0

[5 rows x 34 columns]
print('steel describe command = ',steel.describe())
steel describe command =           X_Minimum    X_Maximum     Y_Minimum     Y_Maximum   Pixels_Areas  \
count  1941.000000  1941.000000  1.941000e+03  1.941000e+03    1941.000000
mean    571.136012   617.964451  1.650685e+06  1.650739e+06    1893.878413
std     520.690671   497.627410  1.774578e+06  1.774590e+06    5168.459560
min       0.000000     4.000000  6.712000e+03  6.724000e+03       2.000000
25%      51.000000   192.000000  4.712530e+05  4.712810e+05      84.000000
50%     435.000000   467.000000  1.204128e+06  1.204136e+06     174.000000
75%    1053.000000  1072.000000  2.183073e+06  2.183084e+06     822.000000
max    1705.000000  1713.000000  1.298766e+07  1.298769e+07  152655.000000

        X_Perimeter   Y_Perimeter  Sum_of_Luminosity  Minimum_of_Luminosity  \
count   1941.000000   1941.000000       1.941000e+03            1941.000000
mean     111.855229     82.965997       2.063121e+05              84.548686
std      301.209187    426.482879       5.122936e+05              32.134276
min        2.000000      1.000000       2.500000e+02               0.000000
25%       15.000000     13.000000       9.522000e+03              63.000000
50%       26.000000     25.000000       1.920200e+04              90.000000
75%       84.000000     83.000000       8.301100e+04             106.000000
max    10449.000000  18152.000000       1.159141e+07             203.000000

       Maximum_of_Luminosity  ...  Orientation_Index  Luminosity_Index  \
count            1941.000000  ...        1941.000000       1941.000000
mean              130.193715  ...           0.083288         -0.131305
std                18.690992  ...           0.500868          0.148767
min                37.000000  ...          -0.991000         -0.998900
25%               124.000000  ...          -0.333300         -0.195000
50%               127.000000  ...           0.095200         -0.133000
75%               140.000000  ...           0.511600         -0.066600
max               253.000000  ...           0.991700          0.642100

       SigmoidOfAreas       Pastry    Z_Scratch     K_Scatch       Stains  \
count     1941.000000  1941.000000  1941.000000  1941.000000  1941.000000
mean         0.585420     0.081401     0.097888     0.201443     0.037094
std          0.339452     0.273521     0.297239     0.401181     0.189042
min          0.119000     0.000000     0.000000     0.000000     0.000000
25%          0.248200     0.000000     0.000000     0.000000     0.000000
50%          0.506300     0.000000     0.000000     0.000000     0.000000
75%          0.999800     0.000000     0.000000     0.000000     0.000000
max          1.000000     1.000000     1.000000     1.000000     1.000000

         Dirtiness        Bumps  Other_Faults
count  1941.000000  1941.000000   1941.000000
mean      0.028336     0.207110      0.346728
std       0.165973     0.405339      0.476051
min       0.000000     0.000000      0.000000
25%       0.000000     0.000000      0.000000
50%       0.000000     0.000000      0.000000
75%       0.000000     0.000000      1.000000
max       1.000000     1.000000      1.000000

[8 rows x 34 columns]
# heatmap Visualization
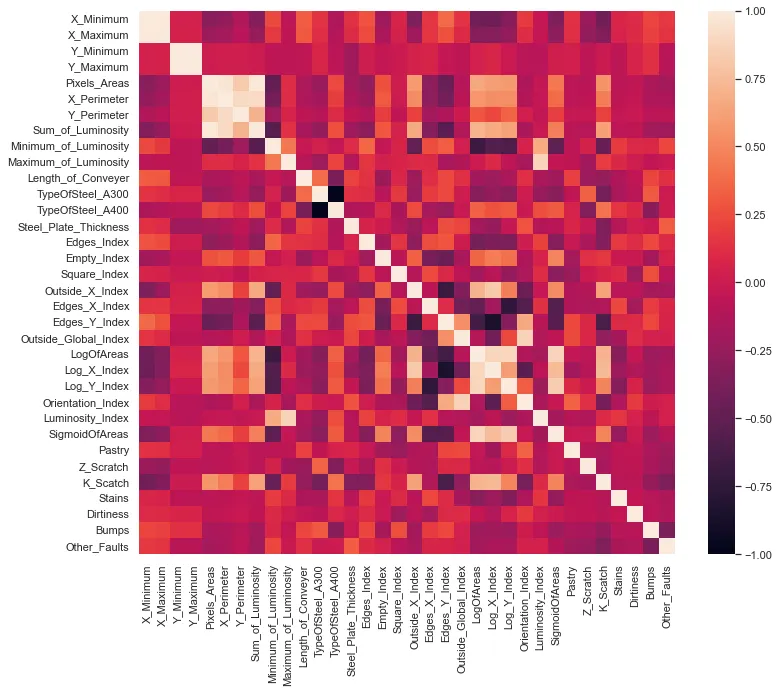
sns.set(rc={'figure.figsize':(12,10)})
corr = steel.corr()
sns.heatmap(corr, xticklabels=corr.columns.values,yticklabels=corr.columns.values)
plt.show()
# Divide the dataset into features and faults
fault = steel.values
fault_data=steel[["Pastry","Z_Scratch","K_Scatch","Stains","Dirtiness","Bumps","Other_Faults"]]
features = fault[:,0:27]
x=pd.DataFrame(features)
print(fault_data)
      Pastry  Z_Scratch  K_Scatch  Stains  Dirtiness  Bumps  Other_Faults
0          1          0         0       0          0      0             0
1          1          0         0       0          0      0             0
2          1          0         0       0          0      0             0
3          1          0         0       0          0      0             0
4          1          0         0       0          0      0             0
...      ...        ...       ...     ...        ...    ...           ...
1936       0          0         0       0          0      0             1
1937       0          0         0       0          0      0             1
1938       0          0         0       0          0      0             1
1939       0          0         0       0          0      0             1
1940       0          0         0       0          0      0             1

[1941 rows x 7 columns]
from sklearn import svm
model=svm.SVC(C=1,gamma="auto",kernel="linear")
# Convert to single column
faults_single = []
for i in range(fault_data.shape[0]):
if fault_data["Pastry"].values[i]==1:
faults_single.append("Pastry")
elif fault_data["Z_Scratch"].values[i] == 1:
faults_single.append("Z_Scratch")
elif fault_data["K_Scatch"].values[i] == 1:
faults_single.append("K_Scatch")
elif fault_data["Stains"].values[i] == 1:
faults_single.append("Stains")
elif fault_data["Dirtiness"].values[i] == 1:
faults_single.append("Dirtiness")
elif fault_data["Bumps"].values[i] == 1:
faults_single.append("Bumps")
else:
faults_single.append("Other_fault")
# heatmap visualization
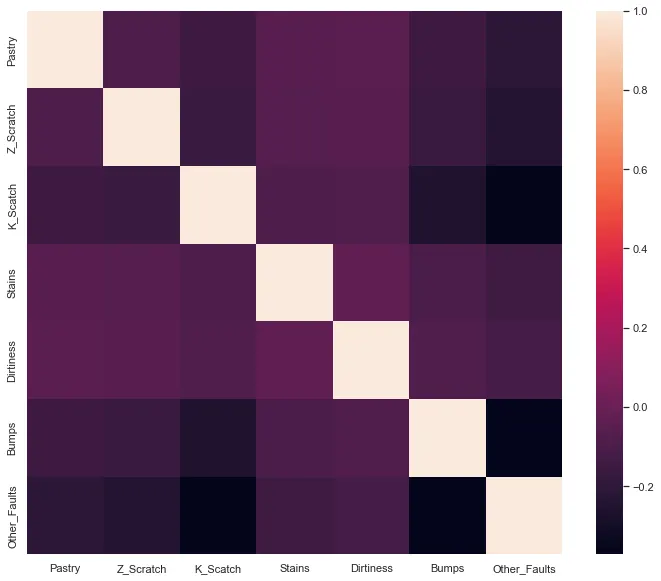
sns.set(rc={'figure.figsize':(12,10)})
corr = fault_data.corr()
sns.heatmap(corr,xticklabels=corr.columns.values,yticklabels =corr.columns.values)
plt.show()
# Covert to single column with transpose
fault_single_col = []
for i in range(fault_dataframe.shape[0]):
if fault_dataframe["Pastry"].values[i] == 1:
fault_single_col.append("Pastry")
elif fault_dataframe["Z_Scratch"].values[i] == 1:
fault_single_col.append("Z_Scratch")
elif fault_dataframe["K_Scatch"].values[i] == 1:
fault_single_col.append("K_Scatch")
elif fault_dataframe["Stains"].values[i] == 1:
fault_single_col.append("Stains")
elif fault_dataframe["Dirtiness"].values[i] == 1:
fault_single_col.append("Dirtiness")
elif fault_dataframe["Bumps"].values[i] == 1:
fault_single_col.append("Bumps")
else:
fault_single_col.append("Other_Faults")
# heatmap Visualization
sns.set(rc={'figure.figsize':(12,10)})
corr = fault_dataframe.corr()
sns.heatmap(corr, xticklabels=corr.columns.values,yticklabels=corr.columns.values)
plt.show()
fault_single =np.array(faults_single)
print(fault_single.shape)
faultstype = pd.DataFrame({'faults':fault_single})
print(faultstype)
(1941,)
           faults
0          Pastry
1          Pastry
2          Pastry
3          Pastry
4          Pastry
...           ...
1936  Other_fault
1937  Other_fault
1938  Other_fault
1939  Other_fault
1940  Other_fault

[1941 rows x 1 columns]
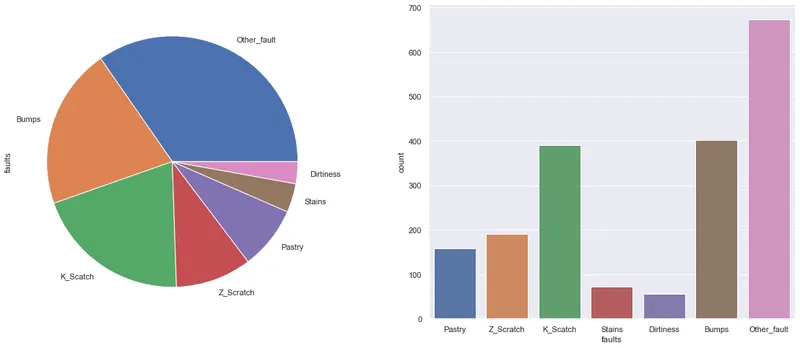
# countplot visualization
fig, ax=plt.subplots(1,2,figsize=(20,8))
faultstype['faults'].value_counts().plot.pie(ax=ax[0])
sns.countplot(x='faults',data=faultstype, ax=ax[1])
plt.show()
sc=StandardScaler()
X=sc.fit_transform(x)
x_train, x_test,y_train,y_test =train_test_split(X, faultstype, test_size =0.40, random_state =1000)
from sklearn.svm import SVC
model =SVC(C=1,gamma ="auto",kernel ="linear")
print(model.fit(x_train,y_train))
print(model.score(x_test,y_test))
SVC(C=1, gamma='auto', kernel='linear')
0.6975546975546976
y_predict =model.predict(x_test)
from sklearn import metrics
cm=metrics.confusion_matrix(y_test,y_predict)
print(cm)
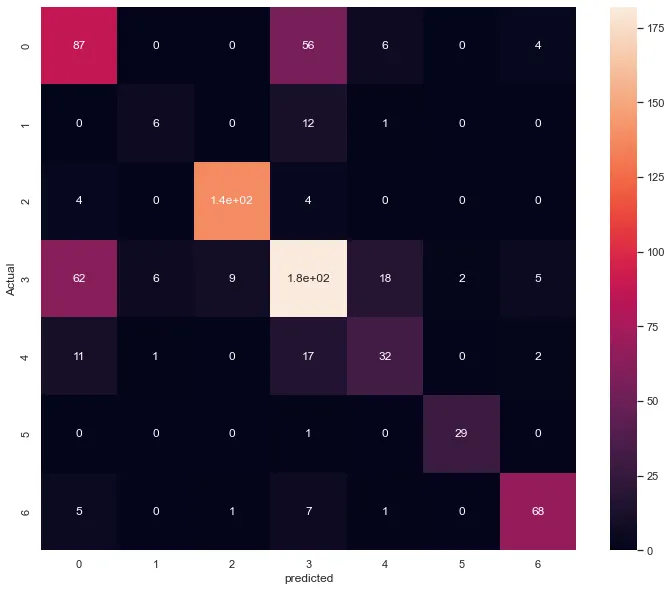
[[ 87   0   0  56   6   0   4]
 [  0   6   0  12   1   0   0]
 [  4   0 138   4   0   0   0]
 [ 62   6   9 182  18   2   5]
 [ 11   1   0  17  32   0   2]
 [  0   0   0   1   0  29   0]
 [  5   0   1   7   1   0  68]]
# heatmap visualization
sns.set(rc={'figure.figsize':(12,10)})
sns.heatmap(cm,annot=True)
plt.xlabel("predicted")
plt.ylabel("Actual")
plt.show()