Basics of Probability and Statistics Week 1 Challenge
1. Why there is a difference in the formula of variance for population and sample?
Ans:
The main difference between population variance and sample variance relates to calculation of variance. i.e.; There is a difference in the formula in the denominator, (N-1) is used in the denominator to reduce the bias. There are two types of sample variances, Baised & Unbaised variances, we use (N-1) in the denominator to reduce the variation of the sample variance from the true mean (Polulation mean). Variance is calculated in five steps. First mean is calculated, then we calculate deviations from the mean, and thirdly the deviations are squared, fourthly the squared deviations are summed up and finally this sum is divided by number of items for which the variance is being calculated.
Thus variance of population is `sigma^2 = (sum(X_i-mu_x)^2)/N`
Where `X_i = i^(th)`Number
`mu_x` = mean and
`N` = number of items.
and the variance of the `S^2 = (sum(X_i-mu_x)^2)/(N-1)`
Now, when the variance is to be calculated from population data, `N` is equal to the number of items. Thus if variance in blood pressure of all the 1000 people is to be calculated from data on blood pressures of all the 1000 people, then `N` = 1000. However when the variance is calculated from sample data 1 is to be deducted from `N` before dividing the sum of the squared deviations. Thus in the above example if sample data have 100 items, the denominator would be 100 – 1 = 99.
Due to this, the value of variance calculated from sample data is higher than the value that could have been found out by using population data.
2. Difference between stratified and clustered sampling ?
Ans:
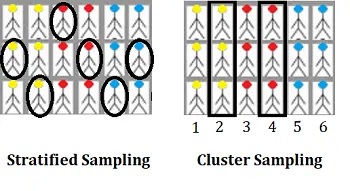
The main difference between stratified sampling and cluster sampling is that with cluster sampling, you have natural groups separating your population. For example, you might be able to divide your data into natural groupings like city blocks, voting districts or school districts. With stratified random sampling, these breaks may not exist, so you divide your target population into groups (more formally called "strata").
- In stratified sampling, a sample is drawn from each strata (using a random sampling method like stratified random samplingor systematic sampiling). In the image below, let's say you need a sample size of 6. Two members from each group (yellow, red, and blue) are selected randomly. Make sure to sample proportionally: In this simple example, 1/3 of each group (2/6 yellow, 2/6 red and 2/6 blue) has been sampled. If you have one group that's a different size, make sure to adjust your proportions. For example, if you had 9 yellow, 3 red and 3 blue, a 5-item sample would consist of 3/9 yellow (i.e. one third), 1/3 red and 1/3 blue.
- In cluster sampling, the sampling unit is the whole cluster; Instead of sampling individuals from within each group, a researcher will study whole clusters. In the image below, the strata are natural groupings by head color (yellow, red, blue). A sample size of 6 is needed, so two of the complete strata are selected randomly (in this example, groups 2 and 4 are chosen).
3. How many different samples can be created out of population of size n ?
Ans:
If the population has 'n' elements in it, Then the no.of samples that can be created is `2^n`
Where 'n' is the no.of individual elements in the population. For example:
If A {11, 13, 17} is the population containing three elements then the all possible sunsets of A are {}, {11}, {13}, {17}, {11,13}, {11,17}, {13,17}, {11, 13, 17}.
Therefore, the no.of possible subsets of A is 8, which is equal to `2^3` including the null set.
4. What is the probability of drawing 2 jacks from a pack of card ?
Ans:
The probality of drawing 2 jacks from a pack of card is `(4c_2)/(52c_2)`.
`implies (((4 times3)/2))/((52 times51)/(2 times 1))`
`=6/1326`
5. What is the probability that both the numbers on dice are same while rolling 2 dice ?
Ans:
Total no.of favourable outcomes = `6` i.e.; ({1,1}, {2,2},{3,3},{4,4},{5,5},{6,6})
Total no.of possible outscomes = `6^2 = 36`
Probality = `6/36 = 1/6`
6. Why standard deviation when variance can measure the dispersion in data ?
Variance is an intermediate stage to obtain standard deviation. Variance can messure the dispersion of data, but the units are in the second power which do not match the orginal units of data.
Variance: `sigma^2 = (sum(X_i-mu_x)^2)/N`
Standard Deviation: `S.D = sqrt((sum(X_i-mu_x)^2)/N)`
For example, if we are calculating the standard deviation of the speed and variance of the speed for a set of data. The units of variance km^2/h^2 which do not match with the original data units, whereas the S.D will have the same units of the original data, in this instance it will be km/h which is the same units system of original data.