Week 4.1 - Genetic Algorithm
AIM:
- To understand the concept of genetic algorithm and to write a code in MATLAB to optimise the stalagmite function and find the global maxima of the function.
Theory:
INTRODUCTION TO OPTIMIZATION
Optimization is the process of making something better. In any process, we have a set of inputs and a set of outputs as shown in the following figure.
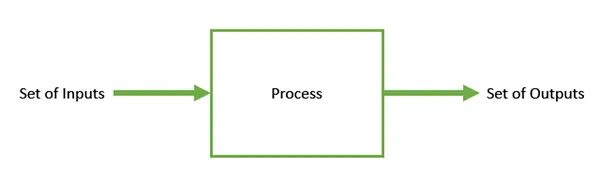
Optimization refers to finding the values of inputs in such a way that we get the “best” output values. The definition of “best” varies from problem to problem, but in mathematical terms, it refers to maximizing or minimizing one or more objective functions, by varying the input parameters.
The set of all possible solutions or values which the inputs can take make up the search space. In this search space, lies a point or a set of points which gives the optimal solution. The aim of optimization is to find that point or set of points in the search space.
In complex machine learning models, the performance usually depends on multiple input parameters. In order to get the optimal model, the parameters must be properly tuned. However, when there are multiple parameter variables, each ranging across a wide spectrum of values, there are too many possible configurations for each set of parameters to be tested. In these cases, optimization methods should be used to attain the optimal input parameters without spending vast amounts of time finding them.
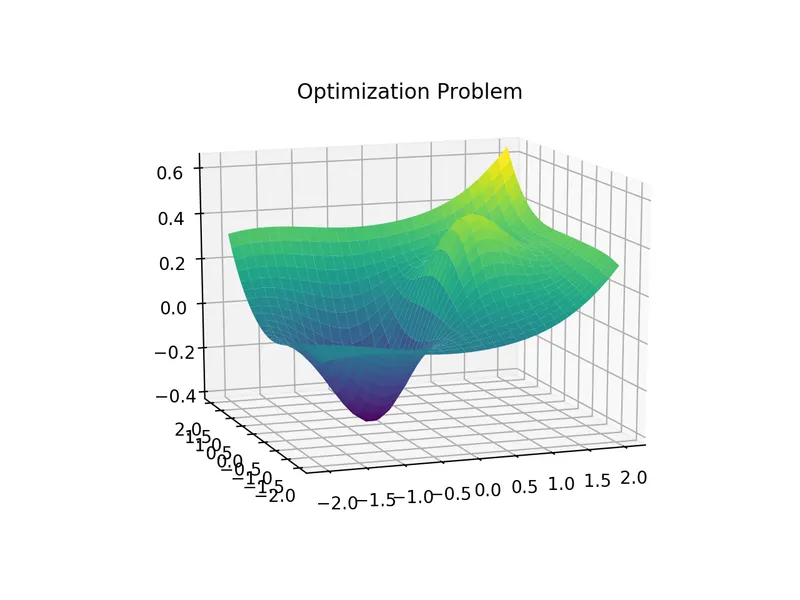
In the diagram above, it shows the distribution of the model based on only two parameters. As evident in the example shown, it is not always an easy task to find the maximum or minimum of the curve. This is why optimization methods and algorithms are crucial in the field of machine learning.
BASIC TERMINOLOGY ON GENETIC ALGORITHMS
Before beginning a discussion on Genetic Algorithms, it is essential to be familiar with some basic terminology which will be used throughout this tutorial.
-
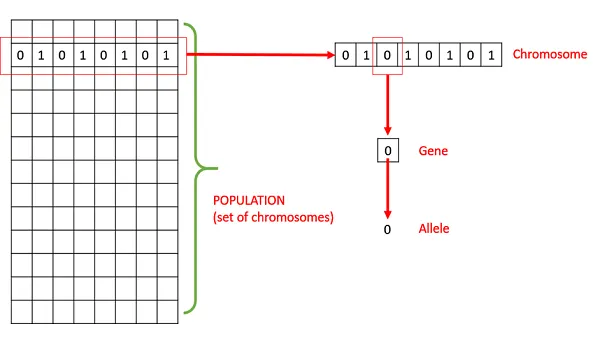
Population − It is a subset of all the possible (encoded) solutions to the given problem. The population for a GA is analogous to the population for human beings except that instead of human beings, we have Candidate Solutions representing human beings.
-
Chromosomes − A chromosome is one such solution to the given problem.
-
Gene − A gene is one element position of a chromosome.
-
Allele − It is the value a gene takes for a particular chromosome.
-
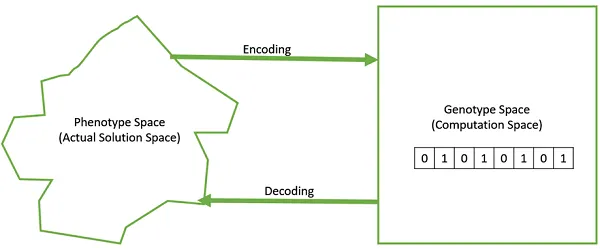
Genotype − Genotype is the population in the computation space. In the computation space, the solutions are represented in a way which can be easily understood and manipulated using a computing system.
-
Phenotype − Phenotype is the population in the actual real world solution space in which solutions are represented in a way they are represented in real world situations.
-
Decoding and Encoding − For simple problems, the phenotype and genotype spaces are the same. However, in most of the cases, the phenotype and genotype spaces are different. Decoding is a process of transforming a solution from the genotype to the phenotype space, while encoding is a process of transforming from the phenotype to genotype space. Decoding should be fast as it is carried out repeatedly in a GA during the fitness value calculation.
For example, consider the 0/1 Knapsack Problem. The Phenotype space consists of solutions which just contain the item numbers of the items to be picked.
However, in the genotype space it can be represented as a binary string of length n (where n is the number of items). A 0 at position x represents that xth item is picked while a 1 represents the reverse. This is a case where genotype and phenotype spaces are different.
-
Fitness Function − A fitness function simply defined is a function which takes the solution as input and produces the suitability of the solution as the output. In some cases, the fitness function and the objective function may be the same, while in others it might be different based on the problem.
-
Genetic Operators − These alter the genetic composition of the offspring. These include crossover, mutation, selection, etc.
Genetic Algorithm:
The most commonly used optimization strategy are Genetic Algorithms. Genetic Algorithms are based off of Darwin’s theory of natural selection. It is relatively easy to implement and there is a lot of flexibility for the setup of the algorithm so that it can be applied to a wide range of problems.
Choosing a fitness function:
To start off, there must be a fitness function that measures how well a set of input parameters perform. Solutions with a higher fitness derived from a fitness function will be better than ones with a lower fitness.
For example, if a solution has a cost of x + y + z, then the fitness function should try to minimize the cost. This can be done with the following fitness function:
`FITNESS FUNCTION = 1/(X+Y+Z)`
This fitness function will generate a fitness value for each set of input parameters and is used to evaluate how well each set of parameters perform.
GENERATE POPULATION:
To run a genetic algorithm, first start off with a population of individuals where each individual is a solution. The solution is represented with a set of genes where each gene in the solution is a variable within the model. Each solution is randomly generated and evaluated against the fitness function to generate a fitness score. It is very important to choose an appropriate population size. If the population size is too low, then it is much harder to explore the entire state space of the problem. If the population is too large, then it will take a very long time to process each generation as system costs for calculating fitness and generating each population will take exponentially more time to process.
SELECTION OF PARENT
Next, the population goes through a process called parent selection where the best solutions (most fit individuals) will be selected to create the next generation of solutions. There are many ways to do this, such as Fitness-Proportion Selection (FPS), Rank-Based Selection, and Tournament Selection. These methods all have their pros and cons and should be picked based on the model.
CROSS OVER
Once the parents have been selected, the parents undergo a process called crossover. Crossover is when two parents crossover their genes in order to create a new solution (also known as a child). This promotes exploration in the state space of the problem and potentially generates new solutions that have never been tested before.
This is done differently based on the data types of the solutions. For solutions where the genes are represented in binary, there are methods such as 1-point crossover, n-point crossover, and uniform crossover.
For solutions where the genes are real-valued, there are methods such as single arithmetic crossover and whole arithmetic crossover.
Also, for permutation problems (such as the Traveling Salesman problem, etc) there are methods such as the Partially-Mapped Crossover (a.k.a. PMX), Edge crossover, Order 1 Crossover, and Cycle crossover.
MUTATION
After the crossover phase, the children generated goes through a mutation phase. Mutation is when each gene could potentially change according to a random probability. This allows for exploitation as the children solution will not change as drastically as during the crossover phase but will still be able to explore around the neighbourhood of its current solution.
For binary solutions, the mutation process is relatively simple where each bit is toggled according to some mutation probability.
For real-valued solutions, the different genes can be chosen according to some acceptable range for that variable or by adding some noise that centers around 0 and varies according to some Gaussian distribution.
Finally, for permutation problems, there are four main methods; insert mutation, swap mutation, inversion mutation, and scramble mutation.
SURVIVOR SELECTION
Once the children population is created, the next stage is survivor selection. This is the stage that decides which individuals get to move on to the next generation. There are multiple ways to do this as the new generation can be selected from both the pool of parents and the pool of children. There are two main methods to select the survivors of each generation, Age-Based Selection and Fitness-Based Selection (FBS). In FBS, there is Elitism, where the most fit of every population is selected, and Genitor, where the worst fit of every population gets eliminated.
ALGORITHM REPETITION
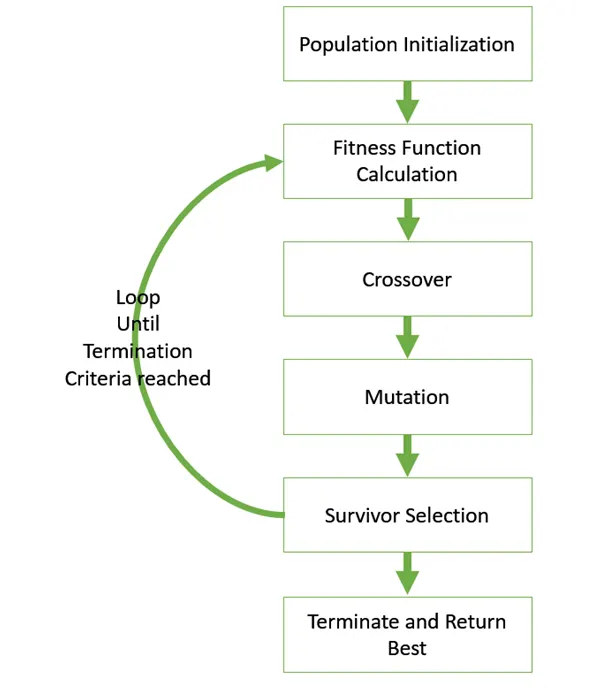
Once the new generation is selected, this whole process repeats until the algorithm converges based off of some convergence criteria. After the whole algorithm runs, the best solution from all of the generations is returned.
ADVANTAGES OF GA:
GAs have various advantages which have made them immensely popular. These include −
-
Does not require any derivative information (which may not be available for many real-world problems).
-
Is faster and more efficient as compared to the traditional methods.
-
Has very good parallel capabilities.
-
Optimizes both continuous and discrete functions and also multi-objective problems.
-
Provides a list of “good” solutions and not just a single solution.
-
Always gets an answer to the problem, which gets better over the time.
-
Useful when the search space is very large and there are a large number of parameters involved.
LIMITATIONS OF GA:
Like any technique, GAs also suffer from a few limitations. These include −
-
GAs are not suited for all problems, especially problems which are simple and for which derivative information is available.
-
Fitness value is calculated repeatedly which might be computationally expensive for some problems.
-
Being stochastic, there are no guarantees on the optimality or the quality of the solution.
-
If not implemented properly, the GA may not converge to the optimal solution.
GOVERNING EQUATION FOR STALAGMITE FUNCTION:
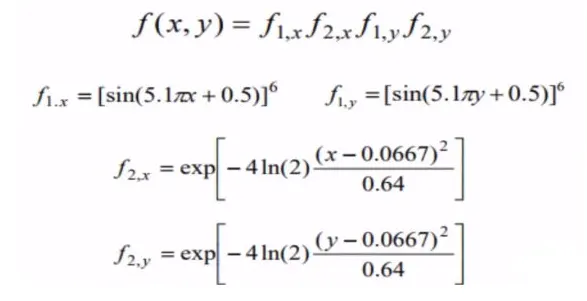
CODE:
%Stalagmite
clear all
close all
clc

%defining our search space
x = linspace(0,0.6,150);
y = linspace(0,0.6,150);
num_cases = 50;
[xx yy] = meshgrid(x,y);


%evaluating stalagmite function
for i = 1:length(xx)         %runs loop for i values of 1 to 150
   for j = 1:length(yy)        %runs loop for j values of 1 to 150
       input_vector(1) = xx(i,j);  %last value of xx(i,j) = 0.6
       input_vector(2) = yy(i,j);      %last value of yy(i,j) = 0.6
       f(i,j) = stalagmite(input_vector);   %new function f to store all values of i,j from 1 to 150 iterations
   end
end

%*********************************************************************************************************
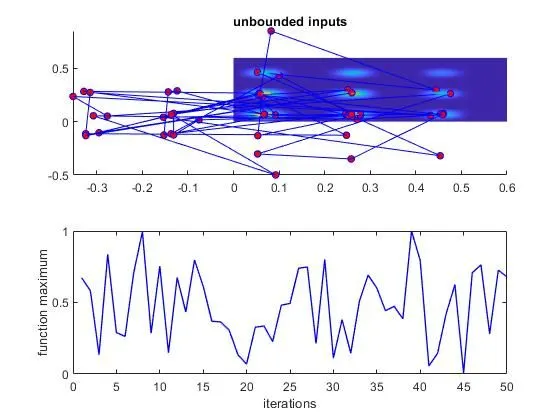
%case 1 statistical behaviour of GA
tic

%evaluating the stalagmite function
for k = 1:num_cases
   [inputs, fopt(k)] = ga(@stalagmite,2)
        xopt(k) = inputs(1);
        yopt(k) = inputs(2);

end
fopt = -fopt;
f = -f;

study1_time = toc
%
figure(1)
subplot(2,1,1) %to have multiple subplots in same figure window
hold on
surfc(x,y,f)
shading interp
plot3(xopt,yopt,fopt,'color','b','marker','o','markersize',5,'markerfacecolor','r')
title('unbounded inputs')
subplot(2,1,2)
plot(fopt,'color','b','linewidth',1)
xlabel('iterations')
ylabel ('function maximum')

tic
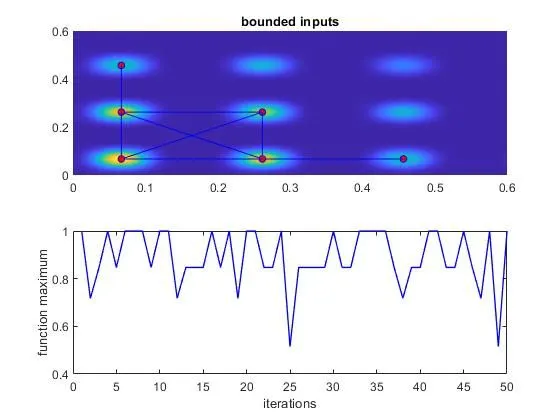
%study 2 - statistical behaviour with upper and lower bounds

for k = 1:num_cases
   [inputs2, fopt2(k)] = ga(@stalagmite,2,[],[],[],[],[0;0],[1;1]);
        xopt2(k) = inputs2(1);
        yopt2(k) = inputs2(2);

end
fopt2 = -fopt2;
study2_time = toc
%
figure(2)
subplot(2,1,1) %to have multiple subplots in same figure window
hold on
surfc(x,y,f)
shading interp
plot3(xopt2,yopt2,fopt2,'color','b','marker','o','markersize',5,'markerfacecolor','r')
title('bounded inputs')
subplot(2,1,2)
plot(fopt2,'color','b','linewidth',1)
xlabel('iterations')
ylabel ('function maximum')

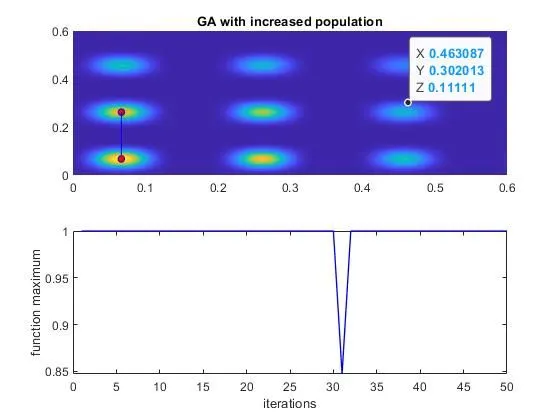
%study 2 - statistical behaviour by increasing number of iterations

options = optimoptions('ga');
options = optimoptions(options, 'populationSize',200);
tic
for k = 1:num_cases
   [inputs3, fopt3(k)] = ga(@stalagmite,2,[],[],[],[],[0;0],[1;1],[],[],options);
        xopt3(k) = inputs3(1);
        yopt3(k) = inputs3(2);

end
fopt3 = -fopt3;
study3_time = toc
%
figure(3)
subplot(2,1,1) %to have multiple subplots in same figure window
hold on
surfc(x,y,f)
shading interp
plot3(xopt3,yopt3,fopt3,'color','b','marker','o','markersize',5,'markerfacecolor','r')
title('GA with increased population')
subplot(2,1,2)
plot(fopt3,'color','b','linewidth',1)
xlabel('iterations')
ylabel ('function maximum')
rng('default');
CODE FOR STALAGMITE:
function f_max = stalagmite(input_vector)
x = input_vector(1);
y = input_vector(2);

f1x = (sin(5.1*pi*x+0.5))^6;
f1y = (sin(5.1*pi*y+0.5))^6;
f2x = exp((-4*log(2)*(x-0.0667)^2)/(0.64));
f2y = exp((-4*log(2)*(y-0.0667)^2)/(0.64));

f_max = -(f1x*f1y*f2x*f2y)

end
CODE EXPLANATION:
- Firstly we use linspace command to create 150 values from 0 to 0.6.
- Then use meshgrid command to evaluate the functions of 2 variables and 3 dimensional plots.
- We use the stalagmite function for various iterations.
- Use the ga function to define the stalagmite functin for different iterations.
- We measure the time taken for 50 iterations by using TIC and TOC command.
SYNTAX OF GA:
The syntax of GA in MATLAB is as follows
x = ga(fitnessfcn,nvars)
x = ga(fitnessfcn,nvars,A,b)
x = ga(fitnessfcn,nvars,A,b,Aeq,beq)
x = ga(fitnessfcn,nvars,A,b,Aeq,beq,LB,UB)
x = ga(fitnessfcn,nvars,A,b,Aeq,beq,LB,UB,nonlcon)
x = ga(fitnessfcn,nvars,A,b,Aeq,beq,LB,UB,nonlcon,options)
x = ga(fitnessfcn,nvars,A,b,[],[],LB,UB,nonlcon,IntCon)
x = ga(fitnessfcn,nvars,A,b,[],[],LB,UB,nonlcon,IntCon,options)
x = ga(problem)
[x,fval] = ga(fitnessfcn,nvars,...)
[x,fval,exitflag] = ga(fitnessfcn,nvars,...)
[x,fval,exitflag,output] = ga(fitnessfcn,nvars,...)
[x,fval,exitflag,output,population] = ga(fitnessfcn,nvars,...)
[x,fval,exitflag,output,population,scores] = ga(fitnessfcn,nvars,...)
x = ga(fitnessfcn,nvars) finds a local unconstrained minimum, x, to the objective function, fitnessfcn. nvars is the dimension (number of design variables) of fitnessfcn.
x = ga(fitnessfcn,nvars,A,b) finds a local minimum x to fitnessfcn, subject to the linear inequalities A x ≤ b.
x = ga(fitnessfcn,nvars,A,b,Aeq,beq) finds a local minimum x to fitnessfcn, subject to the linear equalities Aeq x = beq as well as A x ≤ b. (Set A=[] and b=[] if no inequalities exist.)
x = ga(fitnessfcn,nvars,A,b,Aeq,beq,LB,UB) defines a set of lower and upper bounds on the design variables, x, so that a solution is found in the range LB ≤ x ≤ UB. Use empty matrices for LB and UB if no bounds exist.
x = ga(fitnessfcn,nvars,A,b,Aeq,beq,LB,UB,nonlcon) subjects the minimization to the constraints defined in nonlcon. The function nonlcon accepts x and returns vectors C and Ceq, representing the nonlinear inequalities and equalities respectively. ga minimizes the fitnessfcn such that C(x) ≤ 0 and Ceq(x) = 0. (Set LB=[] and UB=[] if no bounds exist.)
x = ga(fitnessfcn,nvars,A,b,Aeq,beq,LB,UB,nonlcon,options) minimizes with the default optimization parameters replaced by values in the structure options, which can be created using the gaoptimset function.
x = ga(fitnessfcn,nvars,A,b,[],[],LB,UB,nonlcon,IntCon) requires that the variables listed in IntCon take integer values.
x = ga(fitnessfcn,nvars,A,b,[],[],LB,UB,nonlcon,IntCon,options) minimizes with integer constraints and with the default optimization parameters replaced by values in the options structure.
x = ga(problem) finds the minimum for problem, where problem is a structure.
[x,fval] = ga(fitnessfcn,nvars,...) returns fval, the value of the fitness function at x.
[x,fval,exitflag] = ga(fitnessfcn,nvars,...) returns exitflag, an integer identifying the reason the algorithm terminated.
[x,fval,exitflag,output] = ga(fitnessfcn,nvars,...) returns output, a structure that contains output from each generation and other information about the performance of the algorithm.
[x,fval,exitflag,output,population] = ga(fitnessfcn,nvars,...) returns the matrix, population, whose rows are the final population.
[x,fval,exitflag,output,population,scores] = ga(fitnessfcn,nvars,...) returns scores the scores of the final population