Project 2
Implement Clustering and then predict the class of car from “Car dataset”.
ans: I chose the " CarPrice_Assignment " dataset as there was no dataset with the exact name as “Car dataset”.
- The data was read and checked for any missing data or anomalies.
- Dropped 'car ID' and 'CarName' features since car ID was Just an index for the rows and CarName had a different name for each row.
- The data was one hot encoded to change the categorical values to numerical ones.
- I've used hierarchical clustering for this analysis
- A Dendrogram was drawn to find the optimal number of clusters for this data.
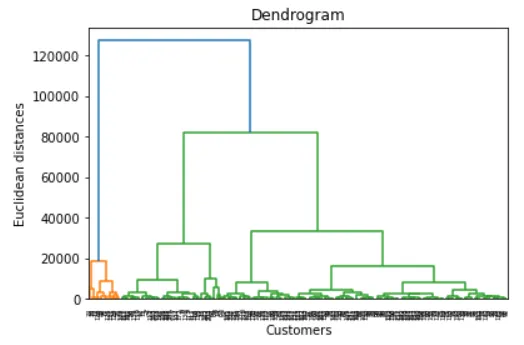
- From looking at the dendrogram it appears that the number clusters should either be 2 or 3. but by measuring the 2 longest vertical lines which are without any intersection from the extended horizontal lines we can conclude that the number cluters is 3.
- Dataset was trained on the hierarchical clustering model and the outcome was added as a dependant variable to the same dataset.
- with the initial dataset as independent variables and clustering output as the dependant variable Random Forrest classification model was created.
- I chose Random Forrest for two reasons.
- As per my past experiences Ran Random Forrest showed the most accuracy when it came to classification (considering the number of features in the dataset).
- It would also show me the accuracy of a single Decision Tree (when the n_estimators is 1)
- The data was split into training set and test set and the independent features were feature scaled.
- For loop was used to find the optimal number of trees. i did this while having the split data ratio of 8:2 and 7:3 and the later gave a perfect accuracy score.
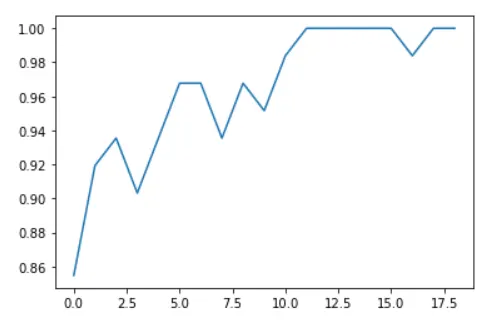
12 proved to be the ideal number of trees for this model.
- confusion matrix:
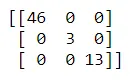
- The accuracy was as perfect score: 1.
This shows the effectiveness of unsupervised learning. without having a variable to learn from the clustering algorithm was able perfectly classify into groups correctly.