Project 12
3D object detection:
Using the media pipe objectron, we can detect the 2D images with 3D. Object Detection is an extensively studied computer vision problem. 2D prediction only provides 2D bounding boxes, by extending prediction to 3D.
ML PIPELINE FOR 3D OBJECT DETECTION:
we built two ML pipelines to predict the 3D bounding box of an object from a single RGB Image. One is a two-stage pipeline and the other is a single-stage pipeline. The two-stage pipeline is 3X faster than the single-stage pipeline with better accuracy.
DETECTION AND TRACKING:
When the model is applied to every frame captured by the mobile device. The tracking subgraph runs every frame, using the box tracker in media pipe Box tracking to track the 2D box tightly enclosing the projection of the 3D bounding box.
The solution API is STATIC_IMAGE_MODE,MAX_NUM_MODEL,MIN_DETECTION_CONFIDENCE,MIN_TRACKING_CONFIDENCE,MODEL_NAME.
STATIC_IMAGE_MODE:
If it is set to false, the solution treats the input images as video streams. It will try to detect objects in the very first image, and upon successful detection.
MAX_NUM_MODEL:
It is used to detect the maximum number of models that it can detect.
MIN_DETECTION_CONFIDENCE:
Minimum confidence value from an object-detection model for the detection to be considered successful.
MIN_TRACKING_CONFIDENCE:
Minimum confidence value from the landmark tracking model for the 3D bounding box landmarks to be considered tracked successfully; otherwise, object detection will be invoked automatically on the next input image.
HUMAN POSE ESTIMATION:
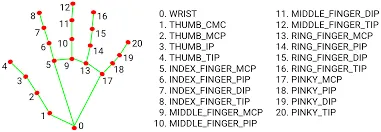
Human pose Estimation is a way of identifying and classifying the joints in the human body. Essentially it is
a way of capturing a set of coordinates from each joint such as arm, head, torso, etc which is known as a key point that can describe a pose of a person. The connection between these points is known as pair. 3d human pose estimation predicts the locations of human joints in 3D spaces. It works on monocular images or videos and helps provide 3D structure information on the human body. It can power various applications, including 3d animations, 3d action prediction and virtual and augmented reality.
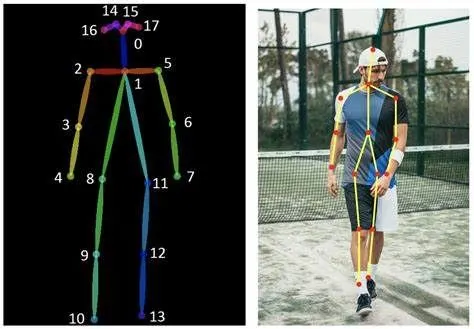
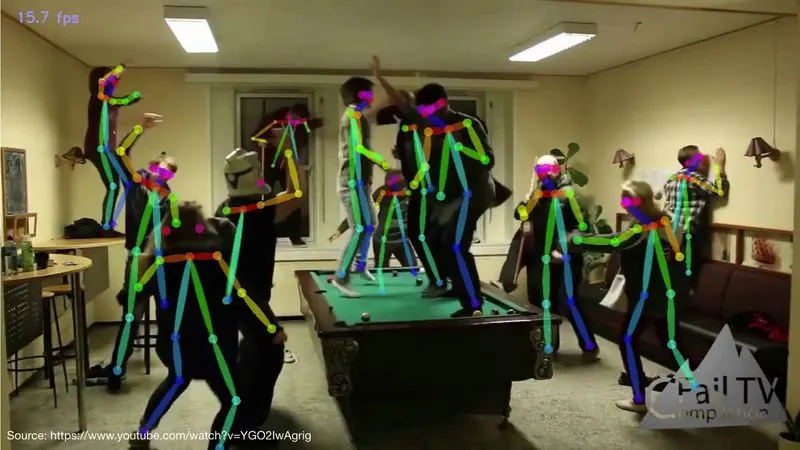
We can predict the multi-person estimation which is mainly used in sports and exercise-based applications. The model can detect six people in an image or video and 17 keypoints joints per person.
PANOPTIC -SEGMENTATION:
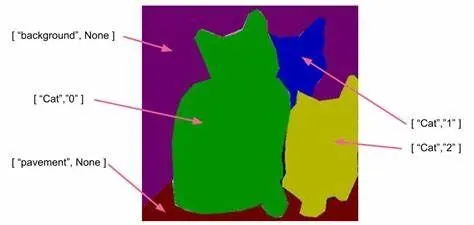
It is a combination of instance and semantic segmentation. In panoptic segmentation, we need to classify all the pixels in the image as belonging to a class label, yet also identify what instance of that class they belong to. The format for doing so is to have each pixel in our image have two values associated with it. This means that pixels that are contained in uncountable "stuff-region", will have an index of none or an integer reflecting that categorization.