Supervised Learning - Prediction Week 3 Challenge
1.)
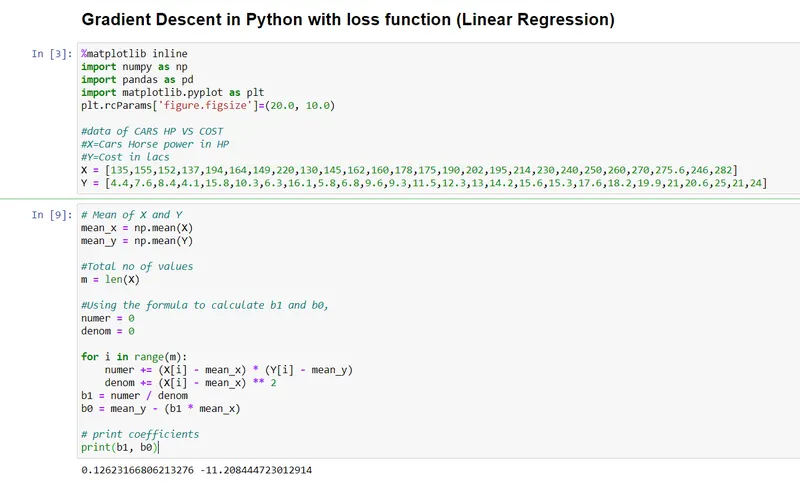
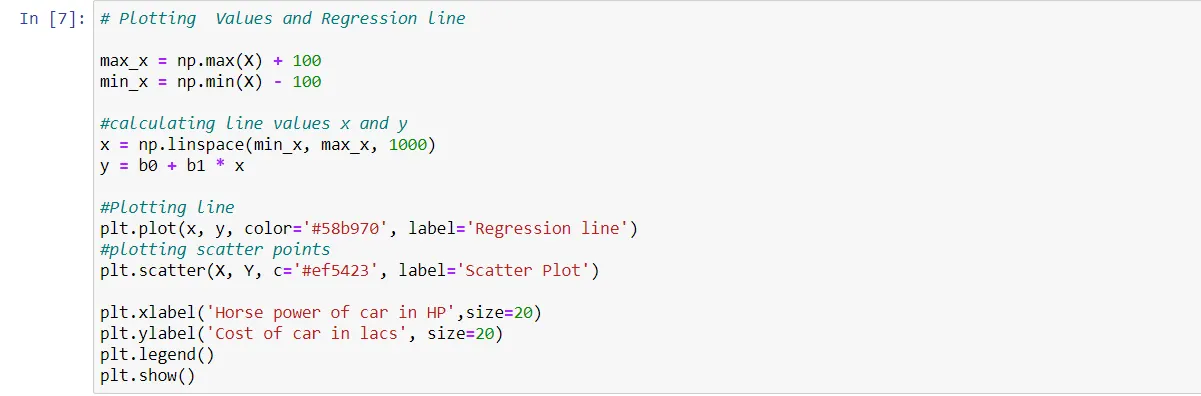
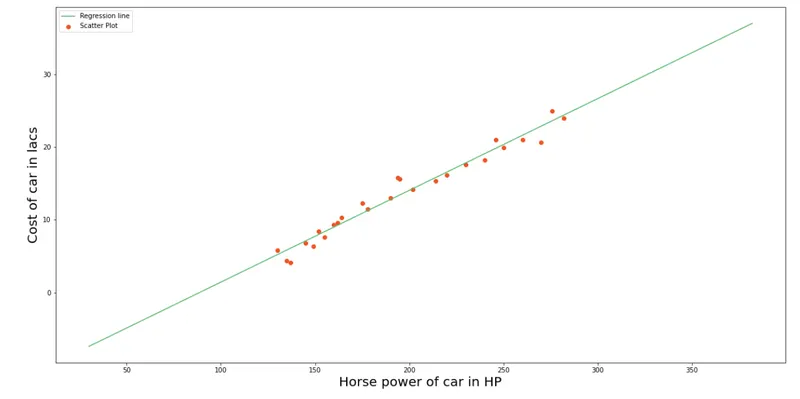
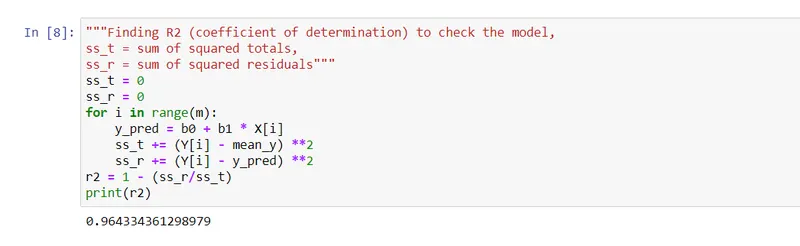
2.)
| L1 Gradient Descent Method | L2 gradient descent method |
| MAE (MEAN ABSOLUTE ERROR) | MSE (MEAN SQUARED ERROR) |
3.) Different Loss Functions for Regression are:
- Mean Absolute Error (MAE)
- Mean Squared Error (MSE)
- Root Mean Squared Error (RMSE)
- Mean Absolute Percentage Error (MAPE)
- Huber Loss
- Log-Cosh Loss
4.) Learning reate is a Tuning Parameter in an optimization algorithm that determines the step size at each iteration while moving toward a minimum of a loss function. Learning Rate is used to scale the magnitude of parameter updates during gradient descent. The choice of the value for learning rate can be impact two things: 1) How fast the algorithm learns and 2) whether the cost function is minimised or not.
5.) There are 3 main metrics for model evaluation in regression. they are
- R squared
- Mean Squared Error (MSE)
- Mean Absolute Error (MAE)
6.) Difference between Multiple and adjusted coefficient of determination
| Multiple Coefficient of Determination | Adjusted Coefficient of Determination |
| R squared or coefficient of determination is the proportion of the variance in the dependent variable that is predicted from independent variable. |
We can Use Adjusted Coefficient of Determination to determine how well a multiple regression equation "fits" the sample data. Adjusted R2 alsways takes on a value between 0 and 1. the closer adjusted R2 is to 1, the better the estimated regression equation fits. |