Project 1
Project 1
When you working on the health of patients then accuracy is deciding factor, Apply different machine learning algorithms and check the accuracy about predicting whether or not the patient has heart disease.
Apply all five different machine learning models Logistic Regression, K-Nearest Neighbours Classifier, Support Vector machine, Decision Tree Classifier, Random Forest Classifier on the given dataset.
In [1]:
1
import pandas as pd
2
import numpy as np
In [2]:
1
# Load data
2
data = pd.read_csv('heart.csv')
In [3]:
1
# before data sorting
2
data.info()
3
data.describe()
RangeIndex: 303 entries, 0 to 302
Data columns (total 14 columns):
 #   Column    Non-Null Count  Dtype
---  ------    --------------  -----
 0   age       303 non-null    int64
 1   sex       303 non-null    int64
 2   cp        303 non-null    int64
 3   trtbps    303 non-null    int64
 4   chol      303 non-null    int64
 5   fbs       303 non-null    int64
 6   restecg   303 non-null    int64
 7   thalachh  303 non-null    int64
 8   exng      303 non-null    int64
 9   oldpeak   303 non-null    float64
 10  slp       303 non-null    int64
 11  caa       303 non-null    int64
 12  thall     303 non-null    int64
 13  output    303 non-null    int64
dtypes: float64(1), int64(13)
memory usage: 33.3 KB
Out[3]:
| age | sex | cp | trtbps | chol | fbs | restecg | thalachh | exng | oldpeak | slp | caa | thall | output | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| count | 303.000000 | 303.000000 | 303.000000 | 303.000000 | 303.000000 | 303.000000 | 303.000000 | 303.000000 | 303.000000 | 303.000000 | 303.000000 | 303.000000 | 303.000000 | 303.000000 |
| mean | 54.366337 | 0.683168 | 0.966997 | 131.623762 | 246.264026 | 0.148515 | 0.528053 | 149.646865 | 0.326733 | 1.039604 | 1.399340 | 0.729373 | 2.313531 | 0.544554 |
| std | 9.082101 | 0.466011 | 1.032052 | 17.538143 | 51.830751 | 0.356198 | 0.525860 | 22.905161 | 0.469794 | 1.161075 | 0.616226 | 1.022606 | 0.612277 | 0.498835 |
| min | 29.000000 | 0.000000 | 0.000000 | 94.000000 | 126.000000 | 0.000000 | 0.000000 | 71.000000 | 0.000000 | 0.000000 | 0.000000 | 0.000000 | 0.000000 | 0.000000 |
| 25% | 47.500000 | 0.000000 | 0.000000 | 120.000000 | 211.000000 | 0.000000 | 0.000000 | 133.500000 | 0.000000 | 0.000000 | 1.000000 | 0.000000 | 2.000000 | 0.000000 |
| 50% | 55.000000 | 1.000000 | 1.000000 | 130.000000 | 240.000000 | 0.000000 | 1.000000 | 153.000000 | 0.000000 | 0.800000 | 1.000000 | 0.000000 | 2.000000 | 1.000000 |
| 75% | 61.000000 | 1.000000 | 2.000000 | 140.000000 | 274.500000 | 0.000000 | 1.000000 | 166.000000 | 1.000000 | 1.600000 | 2.000000 | 1.000000 | 3.000000 | 1.000000 |
| max | 77.000000 | 1.000000 | 3.000000 | 200.000000 | 564.000000 | 1.000000 | 2.000000 | 202.000000 | 1.000000 | 6.200000 | 2.000000 | 4.000000 | 3.000000 | 1.000000 |
In [4]:
1
data.shape
Out[4]:
(303, 14)
In [5]:
1
data=data.dropna()
In [6]:
1
data.shape
Out[6]:
(303, 14)
In [7]:
1
# plot the data into features & target
2
features = pd.DataFrame(data.iloc[:,:-1])
3
target = pd.DataFrame(data.iloc[:,-1])
In [8]:
1
X = features
2
y = target
In [9]:
1
X
Out[9]:
| age | sex | cp | trtbps | chol | fbs | restecg | thalachh | exng | oldpeak | slp | caa | thall | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | 63 | 1 | 3 | 145 | 233 | 1 | 0 | 150 | 0 | 2.3 | 0 | 0 | 1 |
| 1 | 37 | 1 | 2 | 130 | 250 | 0 | 1 | 187 | 0 | 3.5 | 0 | 0 | 2 |
| 2 | 41 | 0 | 1 | 130 | 204 | 0 | 0 | 172 | 0 | 1.4 | 2 | 0 | 2 |
| 3 | 56 | 1 | 1 | 120 | 236 | 0 | 1 | 178 | 0 | 0.8 | 2 | 0 | 2 |
| 4 | 57 | 0 | 0 | 120 | 354 | 0 | 1 | 163 | 1 | 0.6 | 2 | 0 | 2 |
| ... | ... | ... | ... | ... | ... | ... | ... | ... | ... | ... | ... | ... | ... |
| 298 | 57 | 0 | 0 | 140 | 241 | 0 | 1 | 123 | 1 | 0.2 | 1 | 0 | 3 |
| 299 | 45 | 1 | 3 | 110 | 264 | 0 | 1 | 132 | 0 | 1.2 | 1 | 0 | 3 |
| 300 | 68 | 1 | 0 | 144 | 193 | 1 | 1 | 141 | 0 | 3.4 | 1 | 2 | 3 |
| 301 | 57 | 1 | 0 | 130 | 131 | 0 | 1 | 115 | 1 | 1.2 | 1 | 1 | 3 |
| 302 | 57 | 0 | 1 | 130 | 236 | 0 | 0 | 174 | 0 | 0.0 | 1 | 1 | 2 |
303 rows × 13 columns
In [10]:
1
y
Out[10]:
| output | |
|---|---|
| 0 | 1 |
| 1 | 1 |
| 2 | 1 |
| 3 | 1 |
| 4 | 1 |
| ... | ... |
| 298 | 0 |
| 299 | 0 |
| 300 | 0 |
| 301 | 0 |
| 302 | 0 |
303 rows × 1 columns
In [11]:
1
# split dataset
2
from sklearn.model_selection import train_test_split
3
X_train, X_test,y_train, y_test = train_test_split(X, y, test_size=0.2, random_state = 1)
In [12]:
1
# StandardScaler
2
from sklearn.preprocessing import StandardScaler
3
sc = StandardScaler()
4
X_train = sc.fit_transform(X_train)
5
X_test = sc.transform(X_test)
1.LogisticRegression
In [13]:
1
# Import LogisticRegression
2
from sklearn.linear_model import LogisticRegression
In [14]:
1
LR = LogisticRegression()
2
print(LR.fit(X_train, y_train))
LogisticRegression()
C:\Users\HP\anaconda3\lib\site-packages\sklearn\utils\validation.py:993: DataConversionWarning: A column-vector y was passed when a 1d array was expected. Please change the shape of y to (n_samples, ), for example using ravel().
  y = column_or_1d(y, warn=True)
In [15]:
1
y_pred = LR.predict(X_test)
In [16]:
1
y_pred
Out[16]:
array([0, 1, 0, 0, 0, 0, 0, 1, 0, 1, 0, 0, 1, 0, 0, 1, 1, 0, 0, 1, 1, 0,
       1, 1, 1, 1, 0, 1, 1, 1, 1, 1, 1, 1, 0, 0, 0, 0, 1, 0, 1, 0, 0, 0,
       1, 1, 0, 1, 1, 1, 1, 1, 1, 1, 1, 1, 1, 0, 1, 0, 1], dtype=int64)
In [17]:
1
from sklearn.metrics import confusion_matrix
2
CM = confusion_matrix(y_test, y_pred)
In [18]:
1
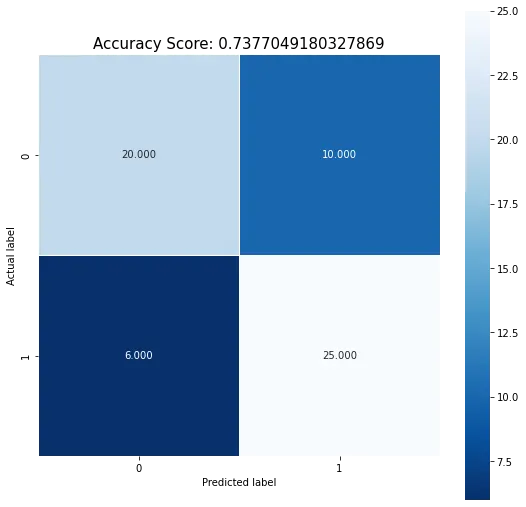
CM
Out[18]:
array([[20, 10],
       [ 6, 25]], dtype=int64)
True positive is 20. True negative is 27. False positive is 10. False negative is 4.
In [19]:
1
score = LR.score(X_test, y_test)
2
print(score)
3
4
# 0.7377049180327869
5
# 0.7704918032786885
0.7377049180327869
In [20]:
1
import matplotlib.pyplot as plt
2
import seaborn as sns
3
from sklearn import metrics
In [21]:
1
plt.figure(figsize=(9,9))
2
sns.heatmap(CM, annot=True, fmt=".3f", linewidths=.5, square = True, cmap = 'Blues_r');
3
plt.ylabel('Actual label');
4
plt.xlabel('Predicted label');
5
all_sample_title = 'Accuracy Score: {0}'.format(score)
6
plt.title(all_sample_title, size = 15);
In [22]:
1
from sklearn import metrics
2
LR_Accuracy = metrics.accuracy_score(y_test, y_pred)
3
print('LogisticRegression Accuracy: ', LR_Accuracy)
LogisticRegression Accuracy: 0.7377049180327869
2.K-Nearest Neighbours Classifier
In [23]:
1
from sklearn.neighbors import KNeighborsClassifier
In [24]:
1
KNN = KNeighborsClassifier()
2
3
KNN.fit(X, y)
4
y_pred = KNN.predict(X)
C:\Users\HP\anaconda3\lib\site-packages\sklearn\neighbors\_classification.py:198: DataConversionWarning: A column-vector y was passed when a 1d array was expected. Please change the shape of y to (n_samples,), for example using ravel().
  return self._fit(X, y)
In [25]:
1
KNN_Accuracy = metrics.accuracy_score(y, y_pred)
2
print('KNN_Accuracy: ', KNN_Accuracy)
KNN_Accuracy: 0.7656765676567657
3.Support Vector machine
In [26]:
1
# Importing libraries
2
from sklearn.svm import SVC
3
from sklearn.metrics import accuracy_score
In [27]:
1
clf = SVC(kernel= 'linear')
2
clf.fit(X_train, y_train)
C:\Users\HP\anaconda3\lib\site-packages\sklearn\utils\validation.py:993: DataConversionWarning: A column-vector y was passed when a 1d array was expected. Please change the shape of y to (n_samples, ), for example using ravel().
  y = column_or_1d(y, warn=True)
Out[27]:
SVC(kernel='linear')
In [28]:
1
# performing predictions on the test dataset
2
y_pred = clf.predict(X_test)
3
print('SVM_Accuracy: ',accuracy_score(y_test, y_pred))
SVM_Accuracy: 0.7213114754098361
4.Decision Tree Classifier
In [29]:
1
# Load libraries
2
from sklearn.tree import DecisionTreeClassifier
In [30]:
1
# classifer object
2
clf = DecisionTreeClassifier()
3
4
# Train Decision Tree Classifer
5
clf = clf.fit(X_train,y_train)
In [31]:
1
# performing predictions on the test dataset
2
y_pred = clf.predict(X_test)
In [32]:
1
# Model Accuracy, how often is the classifier correct?
2
DTC_Accuracy = metrics.accuracy_score(y_test, y_pred)
3
print("Accuracy:", DTC_Accuracy)
Accuracy: 0.7377049180327869
5.Random Forest Classifier
In [33]:
1
from sklearn.ensemble import RandomForestClassifier
In [34]:
1
# classifer object
2
clf = RandomForestClassifier()
3
4
clf.fit(X_train, y_train)
5
6
# performing predictions on the test dataset
7
y_pred = clf.predict(X_test)
8
9
# accuracy calculation
10
RFC_Accuracy = metrics.accuracy_score(y_test, y_pred)
11
print("ACCURACY Random Forest Classifier: ", RFC_Accuracy)
C:\Users\HP\AppData\Local\Temp\ipykernel_7612\2306489415.py:4: DataConversionWarning: A column-vector y was passed when a 1d array was expected. Please change the shape of y to (n_samples,), for example using ravel().
  clf.fit(X_train, y_train)
ACCURACY Random Forest Classifier: 0.7704918032786885