Week 5 - Curve fitting
AIM : To write codes in Python to perform curve fitting.
OBJECTIVE :
- To wite codes to fit a linear and cubic polynomial for the Cp data.
- To plot the linear and cubic fit curves along with the raw data points.
- To measure the fitness characteristics for both the curves.
THEORY :
Curve fitting is a method of modeling or representing data distribution by assigning the best fitting function (curve) along the entire range. Ideally, you want to catch trends in your data so you can predict how your data series will behave in the future.
Types of curve fitting include:
interpolation. Find a function that fits the data points exactly. It assumes no measurement error and therefore has limited applicability to practical scenarios.
Smoothing leaves room for error when you find a function that roughly fits the data points, allowing the actual points to be closer, but not necessarily on a straight line. If the overall error is minimized.
Linear and Polynomial Curve fitting :
(i) Linear curve fitting or linear regression fits a straight line to the data. The data may show some curves, but a straight line provides a good enough fit to make predictions.
The general straight line equation is always given by f(x)= a x + b, which raises the question: At what a and b will the straight line best fit the data?
Taking the vertical distance from each point to the predicted line as the error and summing it over the range gives a concrete number of how far the predicted line is from "best".
The straight line that gives the smallest error can be considered the best straight line.
Since we are interested in the distance from the point to the line (whether the distance is positive or negative), we square the distance in the error calculation. This allows larger errors to be weighted more heavily. This method is therefore called the least squares method.
(ii) Polynomial curve fitting is fitting the data to the graph of a polynomial function. The same least squares method can be used to find the polynomial of a particular degree that minimizes the total error.
To select the best fit for a curve, the following four parameters are used to measure how well a fitting criterion, or equation, represents a given data point:
- The sum of squares due to error (SSESSE),
- R-square (R2R2),
- Adjusted R-squrae,
- Root mean squared error (RMSERMSE)
GOVERNING EQUATIONS USED :
- Error = ∣y(i))−∣y(i))-value of f(x)f(x)at x(i)∣x(i)∣ = |y(i)−f(x(i))||y(i)-f(x(i))|,
- SSE (sum of squared error) = n∑i=1∑i=1nError(i)2(i)2,
- SSR (sum of square of regression) = n∑i=1(f(x(i))−Mean)2∑i=1n(f(x(i))-Mean)2,
- SST (sum of the squared total) = SSE+SSRSSE+SSR ,
- R2R2 ( R squared) = SSRSSTSSRSST,
- RMSE (root mean squared error) = √SSEnSSEn,
where n is the total number of datapoints available.
The raw data of Temperature (K) and specific heat (kJ/kcalK) is obtained from here : Data
SOLUTION STEPS :
- At first necessary modules such as math,matplotlib,numpy,scipy are imported to perform their respective functions.
- Two functions are defined which return linear and cubic equations.
- The following data is loaded into Python by placing it in right directory and a function read_file is created. For loop is used to run each line by using 'open' command with 'r' to read it.
- From the data obtained, two individual column matrices of temperature and specific heat are derived.
- For curve fitting, 'popt' and 'pcov' are used as output for storing parameters obtained by 'curve_fit' command which takes input as the required function(linear or cubic) ,temperature and Cp. Now, another variable named 'fit_cp' stores the new values of Cp calculated by using temperature array.
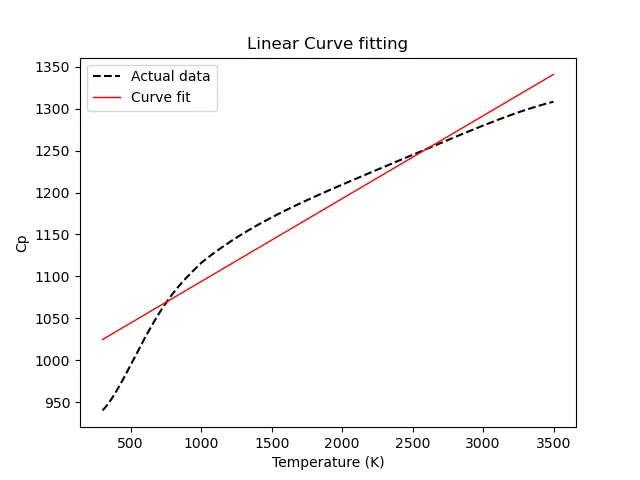
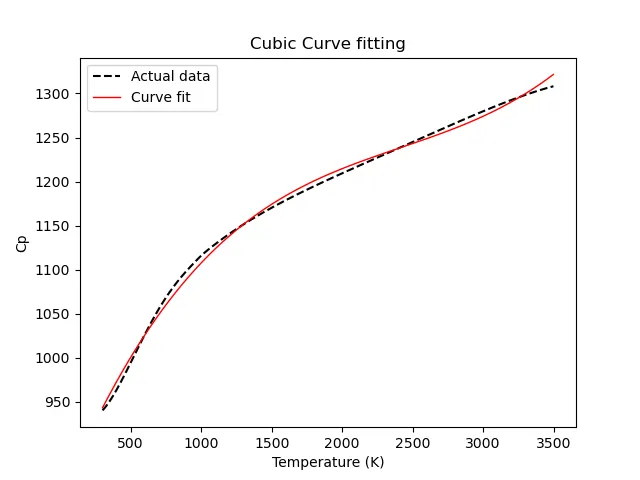
- Plots of both raw dataset and predicted dataset are made and compared to find fitness characteristics for both the curves for both linear and cubic polynomial.
- To measure the fitness characteristics for both the curves, various parameters such as SSESSE,SSRSSR,SSTSST,R2R2,RMSERMSE are calculated. The plot which has highest R2R2 or closest to 1 is considered to be good fit.
PYTHON CODE :
# A program to measure fitness characteristics for the linear and cubic polynomial for the Cp data:
import math
import matplotlib.pyplot as plt
import numpy as np
from scipy.optimize import curve_fit

# Curve fit function
# Linear function
def function_0(t,a,b):
	return a*t + b
# Cubic function
def function_2(t,a,b,c,d):
	return a*pow(t,3) + b*pow(t,2) + c*t +d


# Reading thermodynamic data file
def read_file():
	temperature = []
	cp = []
	for line in open('data','r'):
		values = line.split(',')
		temperature.append(float(values[0]))
		cp.append(float(values[1]))

	return [temperature , cp]

# Main Program
temperature , cp = read_file()

popt, pcov = curve_fit(function_0,temperature,cp)
fit_cp_l = function_0(np.array(temperature), *popt)
plt.figure(1)
plt.plot(temperature,cp,'k--')
plt.plot(temperature,fit_cp_l,color='red',linewidth = 1)
plt.legend(['Actual data','Curve fit'])
plt.xlabel('Temperature (K)')
plt.ylabel('Cp')
plt.title('Linear Curve fitting')
plt.show()

popt, pcov = curve_fit(function_2,temperature,cp)
fit_cp_c = function_2(np.array(temperature), *popt)
plt.figure(3)
plt.plot(temperature,cp,'k--')
plt.plot(temperature,fit_cp_c,color='red',linewidth = 1)
plt.legend(['Actual data','Curve fit'])
plt.xlabel('Temperature (K)')
plt.ylabel('Cp')
plt.title('Cubic Curve fitting')
plt.show()


'''
Measuring the fitness characetristics of the curves

 SSE (sum of error squared)
 SSR (sum of squares of the regression)
 SST = SSE + SSR
 R^2 = SSR/SST
 RMSE = (SSE/l)^0.5

 Finding mean of Cp data
 mean = ( sum of all elements)/(total number of elements)'''

s = np.sum(cp)
l = np.size(cp)
m = s/l
print('Mean of all cp :',m)
print('')
# For Linear curve fit

linear_sse = 0
linear_ssr = 0
for i in range(l):
    linear_error = abs((np.sum((cp[i] - fit_cp_l[i]))))
    linear_sse = linear_sse+pow(linear_error,2)
    linear_ssr = linear_ssr+ np.sum(pow((fit_cp_l[i] - m),2))


linear_sst = linear_sse + linear_ssr
print('linear_sst :',linear_sst)
linear_R2 = linear_ssr/linear_sst
print('linear_R2 :',linear_R2)
linear_rmse = pow((linear_sse/l),0.5)
print('linear_RMSE :',linear_rmse)
print('')


# For Cubic curve fit
cubic_sse = 0
cubic_ssr = 0
for j in range(l):
    cubic_error = abs(np.sum((cp[i] - fit_cp_c[i])))
    cubic_sse = cubic_sse+(pow(cubic_error,2))
    cubic_ssr = cubic_ssr+np.sum(pow((fit_cp_c[i] - m),2))


cubic_sst = cubic_sse + cubic_ssr
print('cubic_sst :',cubic_sst)
cubic_R2= cubic_ssr/cubic_sst
print('cubic_R2 :',cubic_R2)
cubic_rmse = pow((cubic_sse/l),0.5)
print('cubic_RMSE :',cubic_rmse)
RESULTS :
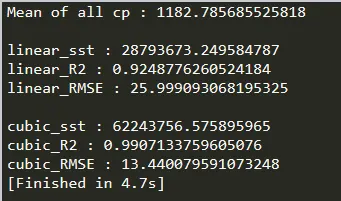
- The following are the output of the above program-
- For Linear Curve fitting the plot obtained is-
- For Cubic Curve fitting the plot obtained is-
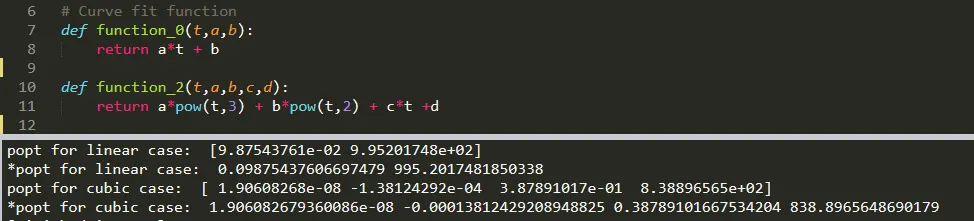
Based on the above work, we can answer the following questions:
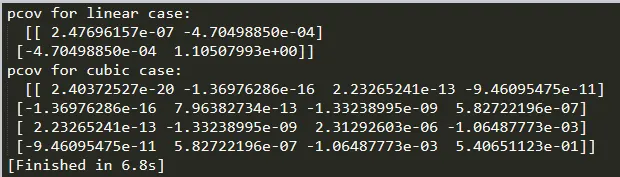
Q. What does popt and pcov mean?
Ans. 'popt' represents the matrix which stores and extracts the coefficients for the fitting functions according to the general equations defined.
popt : array, Optimal values for the parameters so that the sum of the squared residuals of f(xdata, *popt) - ydata is minimized
'pcov' represents the square matrix which stores the estimated values of covariance of the coefficients of the above. The diagonal element of this square matrix also represents variance of that coefficients .
pcov : 2d array
Estimated covariance of popt. The diagonal line gives the variance of the parameter estimates. To compute the standard deviation error of the parameters, use perr = np.sqrt(np.diag(pcov)). How the sigma parameter affects the estimated covariance depends on the absolute_sigma argument. If true, sigma is used in an absolute sense and the estimated parameter covariance pcov reflects these absolute values. If False, only the relative magnitude of the sigma value matters. The returned parameter covariance matrix pcov is based on scaling sigma by a constant factor.
Q. What does np.array(temperature) do?
Ans This command converts each value of temperature in the data file into an array using numpy module.
Q. What does the * in *popt mean?
Ans '*' , '*popt' indicates and returns each coefficients stored in popt array.
Q. What needs to be done in order to make the curve fit perfect?
Ans If we increase the order of the polynomial, the error produced will be less and curve fit perfectly. On increasing the order of the polynomial the value of R2R2 will be close to 1 and is assumed to perfect fit.
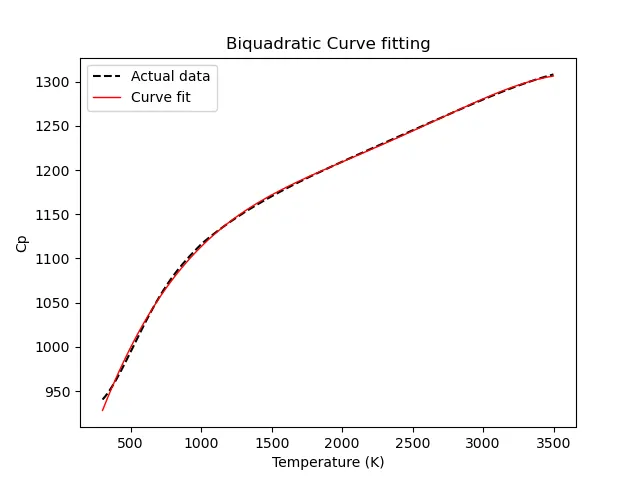
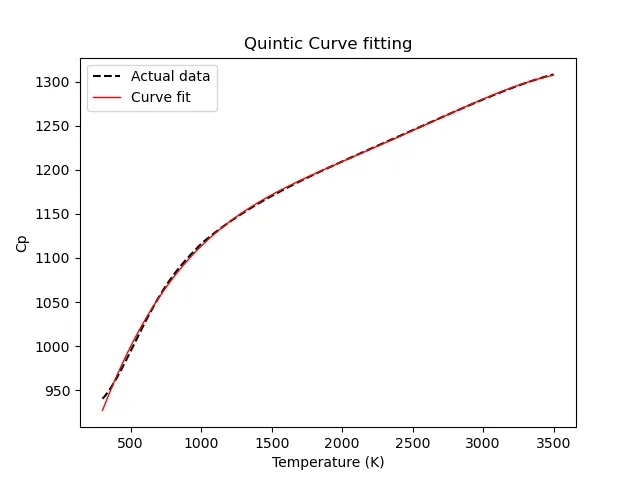
This method requires defining functions every time for another polynomial and can be considered lengthy. Instead of this method the one of the data say temperature can be split into multiple domains say temperature column has 5000 data in it, we can split it into 10 domains of 500 values and if we plot them it will fit perfectly on curve.
CONCLUSION : Hence we can conclude that to make curve fit good R2R2 should be close to 1. It can be found from the results obtained as for linear curve fit R2R2 is approximately 0.93 and for cubic curve fit it is nearly 0.99. So it can be said that cubic polynomial fits better than linear polynomial. If the order of the polynomial increases, the value of R2R2 will inch towards 1 and fit will be assumed to be good.