Supervised Learning - Prediction Week 3 Challenge
1. Perform Gradient Descent in Python with any loss function
Ans::
Let us consider the below dataset for performing gradient descent
x = [1, 2,3,4,5]
y =[2,4,6,8,10]
The loss function to be used is the mean square error which is defined as
MSE = sum_(i=1)^n ( y_a - y_p)^2/n
n=total number of data points
Yp=predicted outcome
Yi=actual outcome
Gradient descent method
Gradient descent is an optimization algorithm. It's based on a convex function and tweaks its parameters iteratively
to minimize the loss function to its local minimum
Let us define the y_predicted as:
Y_predicted=mx+b
where m,b are constants.
Therefore, we can rewrite MSE as:
MSE = sum_(i=1)^n ( y_a - (mx+b))^2/n
To find the local minima, the gradient of MAE wrt to b and m is calculated:
(delMSE)/(delb) = 2/n.sum_(i=1)^n(-1) ( y_a - (mx+b))^2/n
(delMSE)/(delm) = 2/n.sum_(i=1)^n(-x) ( y_a - (mx+b))^2/n
Using these differentials, we iterate the values of b and mas follows
b = b - "learning_rate" * (delMSE)/(delb)
m = m - "learning_rate" * (delMSE)/(delm)
2. Difference between L1 & L2 Gradient descent method
Ans::
* L1-Mean absolute error
* L2-Mean square error
The advantage of the MAE is that its advantage directly covers the MSE disadvantage. In MAE all the errors will be weighted on the same linear scale. The disadvantage of MAE is large errors coming from outliers end up being weighted the exact same as lower errors.
The advantage with MSE is great ensuring that our trained model has no outlier predictions with huge errors since MSE puts larger weight on these errors due to squaring part of the function. The disadvantage with MSE is the squaring part of the function magnifies the error.
3. What are the different loss functions for regression
Ans::
* Mean square error/L2 loss
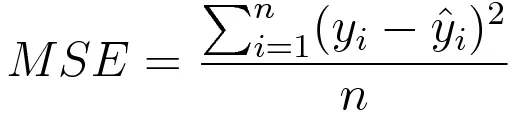
* Mean absolute error/L2 loss
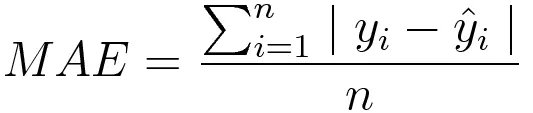
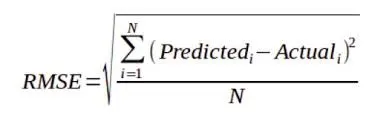
* Root mean square error
4. What is the importance of the learning rate
Ans::
In the process of finding the best linear fit. As we find Y(predicted)[error] from one of the loss functions, differentiation of error gives tangent, but we want tangent to move slowly then learning rate comes into the picture. The importance of linear rate is it allows the tangents to move slowly. In most cases, the learning rate is 0.001.
5. How to evaluate linear regression
Ans::
Coefficient of determination (R^2). If the RA2 is close to one then our prediction of what we are making is with good accuracy.R^2 value going down means the prediction is wrong completely. make sure R^2 is close to one. RA2 is a measure of evaluating the best fit curve.
6. What is the difference between multiple and adjusted coefficients of determination
Ans::
The adjusted coefficient of determination is a modified version of the coefficient of determination(R^2). An adjusted coefficient of determination will increase only if a new data point improves the regression more than you expected. the adjusted coefficient of determination does not include all data points it is always lower than the coefficient of determination(R^2).
The multiple coefficients of determination measure the portion of the variation in the dependent variable that can be predicted from independent variables
Multiple coefficients of determination= the sum of squares of determination/total sum of squares