Supervised Learning - Prediction Week 3 Challenge
Assignment - 2
- Perform Gradient Descent in Python with any loss function.
For Solution please refer to the attached Jupyter notebook.
- What is the difference between L1 and L2 gradient descent method?
L1 and L2 are two loss functions in machine learning which are used to minimize the error. L1 Loss function stands for Least Absolute Deviations. Also known as LAD.L2 Loss function stands for Least Square Errors. Also known as LS.
L1 Loss Function:
L1 Loss Function is used to minimize the error which is the sum of the all the absolute differences between the true value and the predicted value.
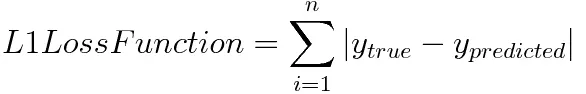
Pros:
- L1 loss function is more robust and is generally not affected by outliers
Cons:
- Its derivatives are not continuous, making it inefficient to find the solution
L2 Loss Function
L2 Loss Function is used to minimize the error which is the sum of all the squared differences between the true value and the predicted value.
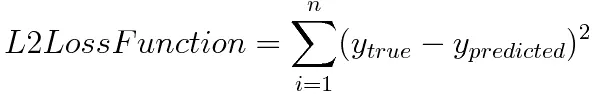
As apparent from above formulae that L2 error will be much larger in the case of outliers compared to L1. Since, the difference between an incorrectly predicted target value and original target value will be quite large and squaring it will make it even larger.
As a result, L1 loss function is more robust and is generally not affected by outliers. On the contrary L2 loss function will try to adjust the model according to these outlier values, even on the expense of other samples. Hence, L2 loss function is highly sensitive to outliers in the dataset.
Pros:
- Using the squared error is easier to solve.
Cons:
- The L2 loss function is highly sensitive to outliers in the dataset. Therefore, the error will be very high for outliers.
- What are the different loss functions for regression?
- Mean Square Error, Quadratic loss, L2 Loss
Mean Squared Error (MSE) is the most commonly used regression loss function. MSE is the sum of squared distances between our target variable and predicted values.
Below is a plot of an MSE function where the true target value is 100, and the predicted values range between -10,000 to 10,000. The MSE loss (Y-axis) reaches its minimum value at prediction (X-axis) = 100. The range is 0 to ∞.
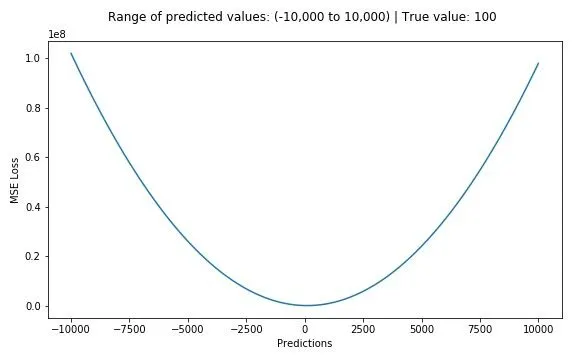
Plot of MSE Loss (Y-axis) vs. Predictions (X-axis)
- Mean Absolute Error, L1 Loss
Mean Absolute Error (MAE) is another loss function used for regression models. MAE is the sum of absolute differences between our target and predicted variables. So, it measures the average magnitude of errors in a set of predictions, without considering their directions. (If we consider directions also, that would be called Mean Bias Error (MBE), which is a sum of residuals/errors). The range is also 0 to ∞.
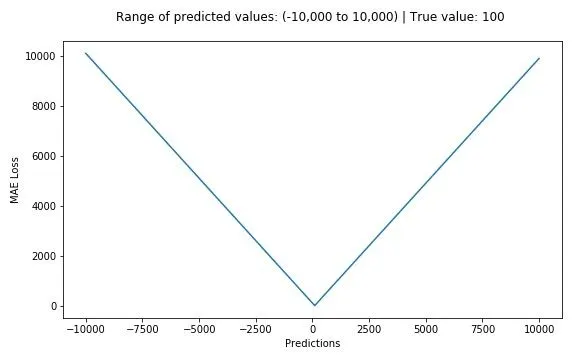
The plot of MAE Loss (Y-axis) vs. Predictions (X-axis).
- Huber Loss, Smooth Mean Absolute Error
Huber Loss is less sensitive to outliers in data than the squared error loss. It’s also differentiable at 0. It’s basically an absolute error, which becomes quadratic when error is small. How small that error has to be to make it quadratic depends on a hyperparameter, 𝛿 (delta), which can be tuned. Huber loss approaches MAE when 𝛿 ~ 0 and MSE when 𝛿 ~ ∞ (large numbers.)
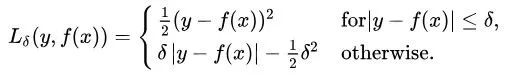
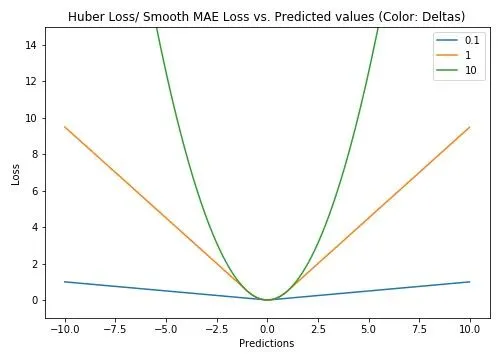
The choice of the delta is critical because it determines what you’re willing to consider as an outlier. Residuals larger than delta are minimized with L1 (which is less sensitive to large outliers), while residuals smaller than delta are minimized “appropriately” with L2.
One big problem with using MAE for the training of neural nets is its constantly large gradient, which can lead to missing minima at the end of training using gradient descent. For MSE, the gradient decreases as the loss gets close to its minima, making it more precise.
Huber loss can be really helpful in such cases, as it curves around the minima which decreases the gradient. And it’s more robust to outliers than MSE. Therefore, it combines good properties from both MSE and MAE. However, the problem with Huber loss is that we might need to train hyperparameter delta which is an iterative process.
- Log-Cosh Loss:
Log-cosh is another function used in regression tasks that’s smoother than L2. Log-cosh is the logarithm of the hyperbolic cosine of the prediction error.
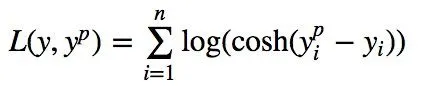
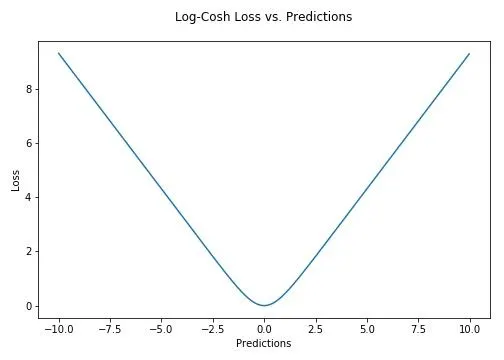
Advantage: log(cosh(x)) is approximately equal to (x ** 2) / 2 for small x and to abs(x) - log(2) for large x. This means that 'logcosh' works mostly like the mean squared error but will not be so strongly affected by the occasional wildly incorrect prediction. It has all the advantages of Huber loss, and it’s twice differentiable everywhere, unlike Huber loss.
- Quantile Loss
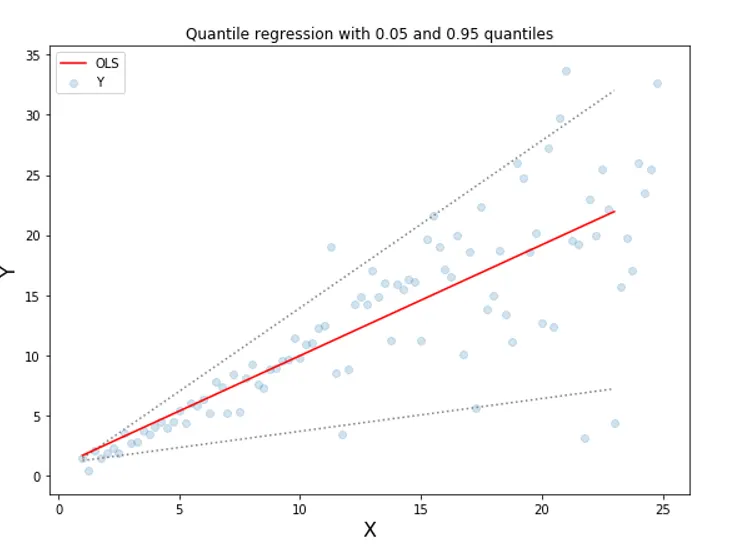
In most of real-world prediction problems, we are often interested to know about the uncertainty in our predictions. Knowing about the range of predictions as opposed to only point estimates can significantly improve decision-making processes for many business problems.
Quantile loss functions turn out to be useful when we are interested in predicting an interval instead of only point predictions. Prediction interval from least square regression is based on an assumption that residuals have constant variance across values of independent variables. We cannot trust linear regression models which violate this assumption. We cannot also just throw away the idea of fitting the linear regression model as a baseline by saying that such situations would always be better modeled using non-linear functions or tree-based models. This is where quantile loss and quantile regression come to the rescue as regression-based on quantile loss provides sensible prediction intervals even for residuals with non-constant variance or non-normal distribution.
4.What is the importance of the learning rate?
Learning rate (λ) is one such hyper-parameter that defines the adjustment in the weights of our network with respect to the loss gradient descent. It determines how fast or slow we will move towards the optimal weights
The Gradient Descent Algorithm estimates the weights of the model in many iterations by minimizing a cost function at every step.
Learning rate is a scalar, a value which tells the machine how fast or how slow to arrive at some conclusion. The speed at which a model learns is important and it varies with different applications. A super-fast learning algorithm can miss a few data points or correlations which can give better insights on the data. Missing this will eventually lead to wrong classifications.
And, to find the next step or the adjacent data point, the gradient descent algorithms multiply the gradient by learning rate (also called step size).
For example, if the gradient magnitude is 1.5 and the learning rate is 0.01, then the gradient descent algorithm will pick the next point 0.015 away from the previous point.
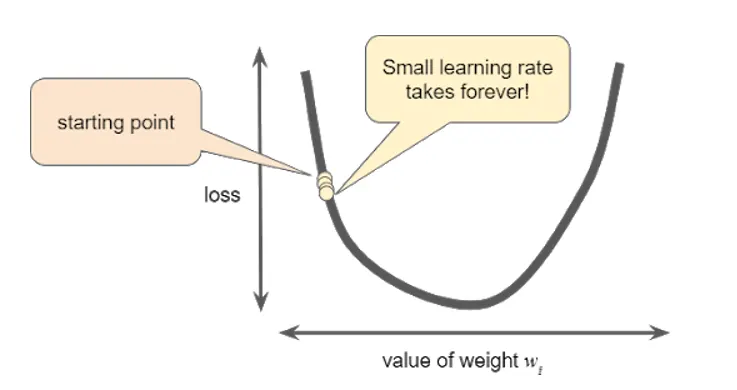
If a learning rate is too small, learning will take too long:
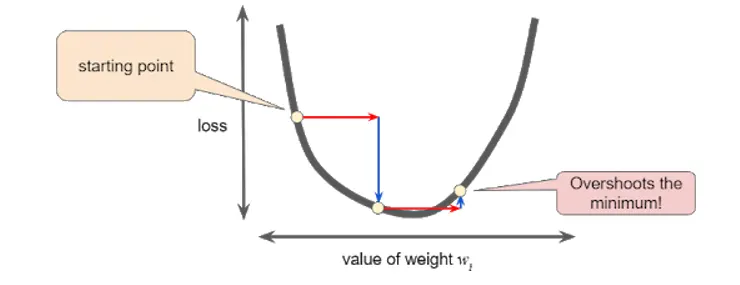
And if a learning rate is too large, the next point will perpetually bounce haphazardly across the bottom of the valley:
5.How to evaluate linear regression?
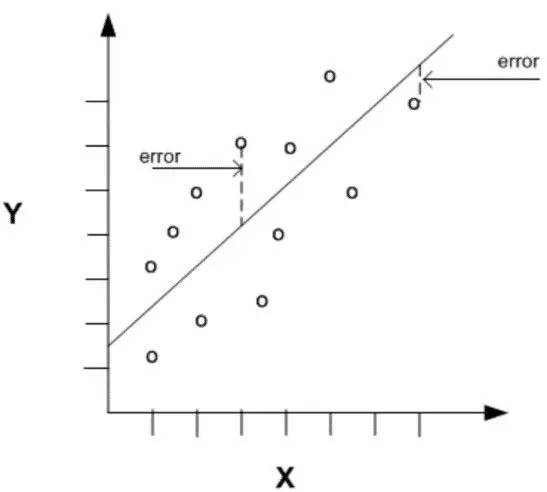
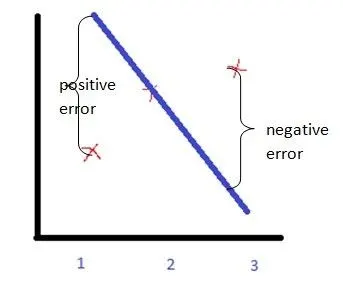
There are three main errors (metrics) used to evaluate models, mean absolute error, Mean Squared error and R2 score.
MAE is the sum of absolute differences between our target and predicted variables. So, it measures the average magnitude of errors in a set of predictions, without considering their directions. (If we consider directions also, that would be called Mean Bias Error (MBE), which is a sum of residuals/errors). The range is also 0 to ∞. The lesser the MAE better the line fits all the data points.
Mean Squared Error(MSE) is the sum of squared distances between our target variable and predicted values. MAE is similar to MAE but the errors are squared.
R2 Square:
R2 score answers the question that if this simple model has a larger error than the linear regression model. However, it terms of metrics the answer we need is how much larger. The R2 score answers this question. R2 score is 1 Best possible score is 1.0 and it can be negative (because the model can be arbitrarily worse). A constant model that always predicts the expected value of y, disregarding the input features, would get an R² score of 0.0
6.What is the difference between adjusted and multiple coefficients of determination?
Adjusted R-Squared
The adjusted R-squared compares the descriptive power of regression models—two or more variables—that include a diverse number of independent variables—known as a predictor. Every predictor or independent variable, added to a model increases the R-squared value and never decreases it. So, a model that includes several predictors will return higher R2 values and may seem to be a better fit. However, this result is due to it including more terms.
The adjusted R-squared compensates for the addition of variables and only increases if the new predictor enhances the model above what would be obtained by probability. Conversely, it will decrease when a predictor improves the model less than what is predicted by chance.
When too few data points are used in a statistical model it is called overfitting. Overfitting can return an unwarranted high R-squared value. This incorrect figure can lead to a decreased ability to predict performance outcomes. The adjusted R-squared is a modified version of R2 for the number of predictors in a model. The adjusted R-squared can be negative but isn't always.
While an R-squared value between 0 and 100 and shows the linear relationship in the sample of data even when there is no basic relationship, the adjusted R-squared gives the best estimate of the degree of relationship in the basic population.
To show the correlation of models with R-squared, pick the model with the highest limit. However, the best, and easiest, way to compare models is to select one with the smaller adjusted R-squared. Adjusted R-squared is not a typical model for comparing nonlinear models but, instead, shows multiple linear regressions.