Project 12
Traffic light Classification System By applying transfer learning on a Vision Transformer(ViT) on the "Cropped LISA Traffic Light Dataset"
Vision Transformers are gaining wide popularity as an alternative to conventional CNN models for various Computer vision tasks such as Image Segmentation, Object Detection, and Image Classification. Transformers have also taken the world by storm with modern Language models(LLMs or Large Language Models) such as OpenAI's ChatGPT and BART. They can model the human "natural language" to a great extent and are very accurate in many problems involving Natural Language Processing such as Open Domain Question Answering, Image-based Question Answering and so on.
Vision Transformers are special types of transformers that are specially trained on images such that the model is able to learn the features in an Image. These can be used for many computer vision tasks such as Image Classification. Training transformers from scratch can be a very computationally expensive and cumbersome process as they require a very large amount of data. For this reason, Transfer Learning can be applied to Transformers. HuggingFace is a platform that has pipelines for a large number of pre-trained transformers. For this project, I have taken the 'google/vit-base-patch16-224-in21k' transformer.
The Training was done using the transformer module from Hugging Face and the transformer was trained on the Kaggle's Cropped LISA Traffic Light Dataset
The Summary of the Dataset
- Training Set
| Label | Number of Images |
| go | 12840 |
| stop | 14865 |
| warning | 985 |
| stopLeft | 2845 |
| goLeft | 1030 |
| goForward | 184 |
| warningLeft | 48 |
| Total | 32797 |
- Validation Set
| Label | Number of Images |
| go | 1372 |
| stop | 1777 |
| warning | 108 |
| stopLeft | 345 |
| goLeft | 109 |
| goForward | 21 |
| warningLeft | 5 |
| Total | 3737 |
The Transformer was trained using this google collab notebook Train Transformer Collab
It was for 2 epochs with a training rate of 2e-5 on the GPU setting in Collab.
The Model was saved as checkpoints in the Drive link attached here.
The classification model was used along with a Yolov5 Object detection model to predict the traffic light in the image attached below:
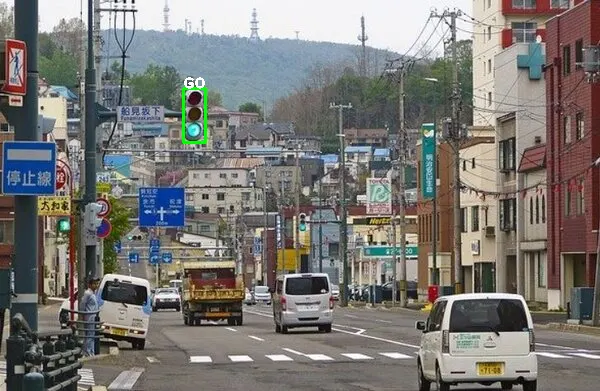
The Collab notebook used to perform the Inference can be found here.
Alternate Links:
Drive link with All Notebooks and model checkpoints: https://colab.research.google.com/drive/1wUWeQvkJmyzoCqLEQswtMrDEnzT_UvCX?usp=sharing.