Project 1
Objective: In this project we are going to clean the dataset of '1985 Automobile Dataset'.
About the Dataset:
This is a raw dataset about cars in 1985.
This data set consists of three types of entities:
(a) the specification of an auto in terms of various characteristics,
(b) its assigned insurance risk rating,
(c) its normalized losses in use as compared to other cars. The second rating corresponds to the degree to which the auto is more risky than its price indicates. Cars are initially assigned a risk factor symbol associated with its price. Then, if it is more risky (or less), this symbol is adjusted by moving it up (or down) the scale. Actuarians call this process "symboling". A value of +3 indicates that the auto is risky, -3 that it is probably pretty safe. The third factor is the relative average loss payment per insured vehicle year. This value is normalized for all autos within a particular size classification (two-door small, station wagons, sports/specialty, etc…), and represents the average loss per car per year.
Note: Several of the attributes in the database could be used as a "class" attribute.
Number of Instances: 205
Number of Attributes: 26 total
-- 15 continuous
-- 1 integer
-- 10 nominal.
Attribute Information:
- symboling: -3, -2, -1, 0, 1, 2, 3
- normalized-losses: continuous from 65 to 256
- make: alfa-romero, audi, bmw, chevrolet, dodge, honda, isuzu, jaguar, mazda, mercedes-benz, mercury, mitsubishi, nissan, peugot, plymouth, porsche, renault, saab, subaru, toyota, volkswagen, volvo
- fuel-type: diesel, gas
- aspiration: std, turbo
- num-of-doors: four, two
- body-style: hardtop, wagon, sedan, hatchback, convertible
- drive-wheels: 4wd, fwd, rwd
- engine-location: front, rear
- wheel-base: continuous from 86.6 120.9
- length: continuous from 141.1 to 208.1
- width: continuous from 60.3 to 72.3
- height: continuous from 47.8 to 59.8
- curb-weight: continuous from 1488 to 4066
- engine-type: dohc, dohcv, l, ohc, ohcf, ohcv, rotor
- num-of-cylinders: eight, five, four, six, three, twelve, two
- engine-size: continuous from 61 to 326
- fuel-system: 1bbl, 2bbl, 4bbl, idi, mfi, mpfi, spdi, spfi
- bore: continuous from 2.54 to 3.94
- stroke: continuous from 2.07 to 4.17
- compression-ratio: continuous from 7 to 23
- horsepower: continuous from 48 to 288
- peak-rpm: continuous from 4150 to 6600
- city-mpg: continuous from 13 to 49
- highway-mpg: continuous from 16 to 54
- price: continuous from 5118 to 45400.
Overview:
- Importing the necessary libraries and the raw data.
- Renaming the columns.
- Finding the missing values.
- Filling the missing values.
- Exporting the data into a new csv file.
- Summary and Conclusion.
1. Importing the necessary libraries and the raw data.
- In the first step, we are going to import the libraries like pandas, numpy, and matplotlib. After that we are going to import the csv file called 'auto.csv' .
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
df = pd.read_csv('auto.csv')
df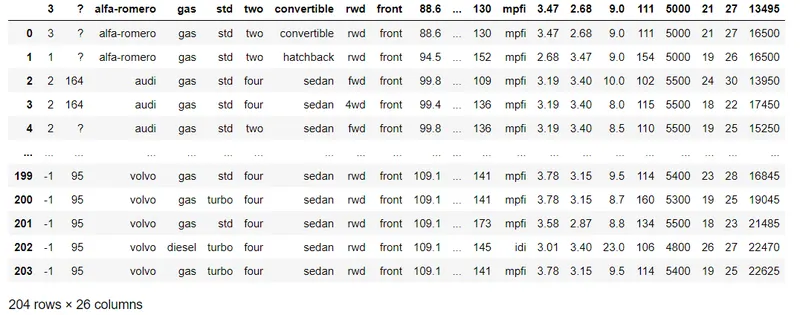
- As we can see that there are 204 data points and 26 attributes in the dataset but the column names are absurdly written. Lets see all the columns at once so that we can get the idea on the number of absurdly written columns.
df.info()<class 'pandas.core.frame.DataFrame'>
RangeIndex: 204 entries, 0 to 203
Data columns (total 26 columns):
# Column Non-Null Count Dtype
--- ------ -------------- -----
0 3 204 non-null int64
1 ? 204 non-null object
2 alfa-romero 204 non-null object
3 gas 204 non-null object
4 std 204 non-null object
5 two 204 non-null object
6 convertible 204 non-null object
7 rwd 204 non-null object
8 front 204 non-null object
9 88.6 204 non-null float64
10 168.8 204 non-null float64
11 64.1 204 non-null float64
12 48.8 204 non-null float64
13 2548 204 non-null int64
14 dohc 204 non-null object
15 four 204 non-null object
16 130 204 non-null int64
17 mpfi 204 non-null object
18 3.47 204 non-null object
19 2.68 204 non-null object
20 9.0 204 non-null float64
21 111 204 non-null object
22 5000 204 non-null object
23 21 204 non-null int64
24 27 204 non-null int64
25 13495 204 non-null object
dtypes: float64(5), int64(5), object(16)
memory usage: 41.6+ KB- By observing the above data we can find that all the column names are absurdly written. So in the next step we will be renaming the columns.
2. Renaming the Columns:
- In this step we will first pass a variable named 'column' which contains the array of the new column names and then we will pass this variable to the pandas dataframe to replace it with the new column names.
column = ['Symboling','Normalized Losses','Make','Fuel Type','Aspiration','No. of Doors','Body Style','Drive Wheels',
         'Engine Location','Wheel Base','Length','Width','Height','Curb Weight','Engine Type','No. of Cylinders','Engine Size',
         'Fuel System','Bore','Stroke','Compression Ratio','Horsepower','Peak RPM','City MPG','Highway MPG','Price']

df.columns = column
df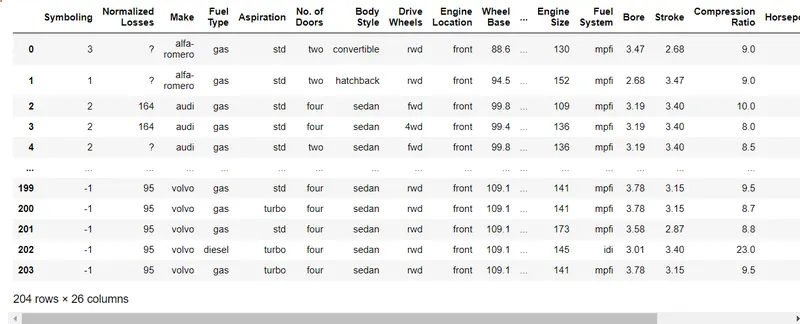
- So in this way we have replaced the new column names with old one.
3. Finding the missing values:
- If we closely look at the data we will find that there are several '?' sign on the data points which indicates that there are some missing values in the dataset.
- As it is difficult to deal with '?' in tha dataset we will replacing it with 'NaN' value so that we can easily deal with the null values.
df[df == '?'] # Finding the locations of all '?' in the dataset.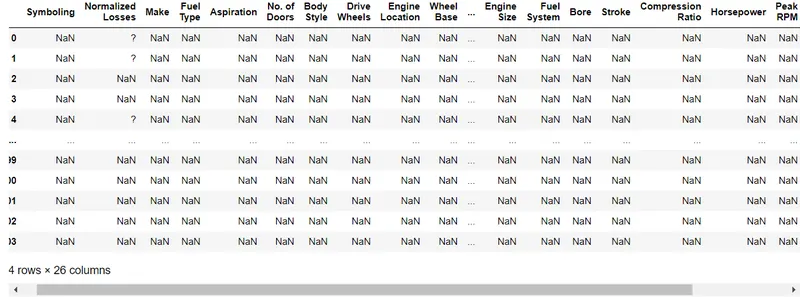
df = df.replace('?',np.NaN) # replacing the '?' with NaN value.
df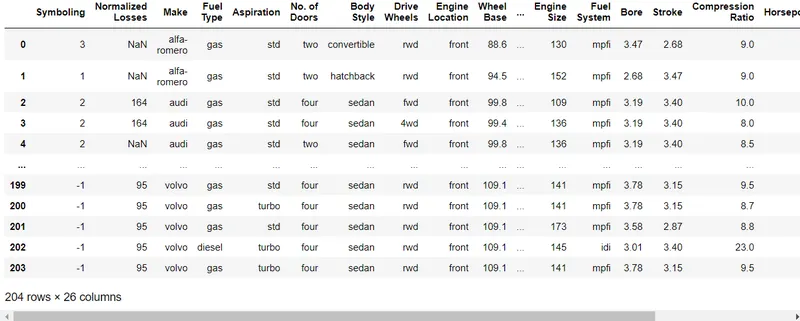
The replancement of '?' sign to null values is successfully changed.
- Now we can easily determine the columns containing the null values.
df.isna().sum() # Counting the NaN values in the dataset.Symboling 0
Normalized Losses 40
Make 0
Fuel Type 0
Aspiration 0
No. of Doors 2
Body Style 0
Drive Wheels 0
Engine Location 0
Wheel Base 0
Length 0
Width 0
Height 0
Curb Weight 0
Engine Type 0
No. of Cylinders 0
Engine Size 0
Fuel System 0
Bore 4
Stroke 4
Compression Ratio 0
Horsepower 2
Peak RPM 2
City MPG 0
Highway MPG 0
Price 4
dtype: int64By observing the above results we have successfully counted the number missing values in different columns.
According to the results,
- Normalized Losses has 40 missing values.
- No. of Doors has 2 missing values.
- Bore has 4 missing values.
- Stroke has 4 missing values.
- Horsepower and Peak RPM have 2 missing values each.
- Price has 4 missing values.
- We are now going to check for the number of rows having at least one missing values.
For this process, we will first find the indexes of the datasets which contains at least one null values and then pass it on to the dataframe.
d = df.isnull().any(axis = 1)
index = d.index[d.values]
index
Int64Index([ 0, 1, 4, 6, 8, 13, 14, 15, 16, 26, 42, 43, 44,
45, 47, 48, 54, 55, 56, 57, 62, 65, 70, 72, 73, 74,
81, 82, 83, 108, 109, 112, 113, 123, 125, 126, 127, 128, 129,
130, 180, 188, 190, 191, 192],
dtype='int64')These are the indexes of the dataset having at least one missing value throughout the datapoint.
Now we are going to locate all these datapoints at once and counting it.
missing = df.iloc[index,:] # No of rows having at least one missing value.
missing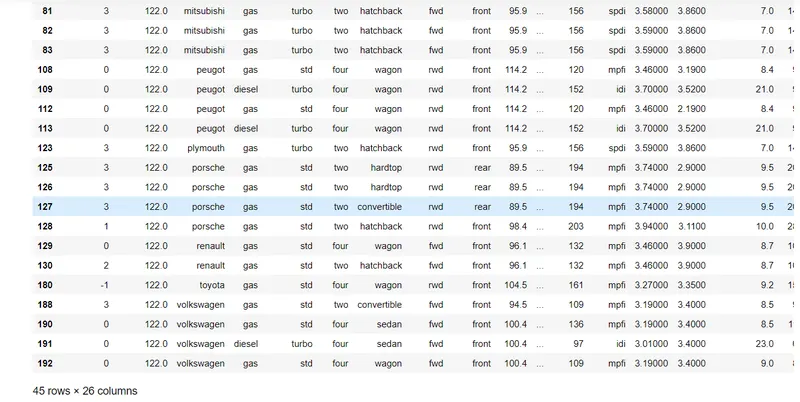
So its been foound out that there are 45 datapoints exist which has at least one missing value.
- Now we are going to check if there is any row or column having all null values.
df.isnull().all(axis=0).sum() # If any columns having all missing values?0df.isnull().all(axis=1).sum() # If any rows having all missing values?0So there is no column or row exist which has all the null values.
- Now lets find out the % of the missing values in all the columns.
round(df.isnull().sum().sort_values(ascending = False)/len(df) * 100,2)Normalized Losses 19.61
Price 1.96
Stroke 1.96
Bore 1.96
Peak RPM 0.98
Horsepower 0.98
No. of Doors 0.98
Length 0.00
Make 0.00
Fuel Type 0.00
Aspiration 0.00
Body Style 0.00
Drive Wheels 0.00
Engine Location 0.00
Wheel Base 0.00
Height 0.00
Width 0.00
Highway MPG 0.00
Curb Weight 0.00
Engine Type 0.00
No. of Cylinders 0.00
Engine Size 0.00
Fuel System 0.00
Compression Ratio 0.00
City MPG 0.00
Symboling 0.00
dtype: float64According to the results it has been found that:
- Normalized Losses is the column having the most null values of about 19.61 %.
- Price,Stroke and Bore are the columns containing 1.96% null values each.
- Peak RPM,Horsepower and No. of Doors are the columns containing 0.98 % null values each.
4. Filling the missing values:
Now that we know every detail about the missing values in the dataset we will now fill the null values.
We will replace the null values with the mean of the values of that particular column.
In order to do that, the data type of the particular columns should be in floating types, otherwise we will not be able to find the mean of that particular column.
- Changing the data types of the target columns.
Here our target columns are 'Normalized Losses','Price','Stroke','Bore','Peak RPM','Horsepower' and 'No. of Doors. As 'No. of Doors' column is a categorical data it can't be change into float data type. We will deal with this column later.
First we will change the data type of the target columns excluding 'No. of Doors'.
df[['Normalized Losses','Price','Stroke','Bore','Peak RPM','Horsepower']] = df[['Normalized Losses','Price','Stroke','Bore','Peak RPM','Horsepower']].apply(pd.to_numeric)Now checking whether the mean can be calculated or not.
df[['Normalized Losses','Price','Stroke','Bore','Peak RPM','Horsepower']].describe()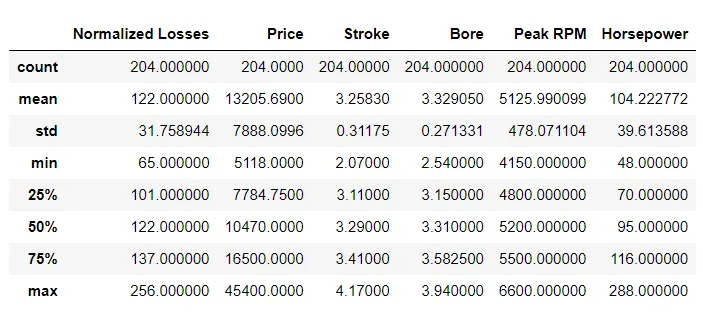
So it is clear that we can find out the mean of the each target columns.
- Replacing the null values in 'Normalized Losses' column with the mean of the column i.e. 122.
Let us deal with the 'Normalized Losses' column first as it contains the most number of null values. We will replace the null values with its mean which is 122.
df.loc[:,'Normalized Losses'].fillna(df['Normalized Losses'].mean(),inplace = True)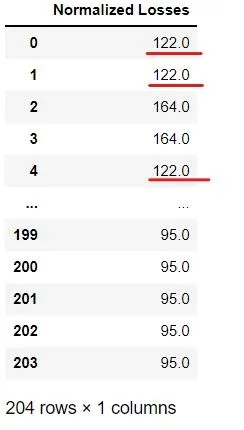
It looks like all the null values are replaced with the mean value of the column.
Let's check whether actually all the null values are gone or not.
round(df.isnull().sum().sort_values(ascending = False)/len(df) * 100,2)Price 1.96
Stroke 1.96
Bore 1.96
Peak RPM 0.98
Horsepower 0.98
No. of Doors 0.98
Length 0.00
Normalized Losses 0.00
Make 0.00
Fuel Type 0.00
Aspiration 0.00
Body Style 0.00
Drive Wheels 0.00
Engine Location 0.00
Wheel Base 0.00
Height 0.00
Width 0.00
Highway MPG 0.00
Curb Weight 0.00
Engine Type 0.00
No. of Cylinders 0.00
Engine Size 0.00
Fuel System 0.00
Compression Ratio 0.00
City MPG 0.00
Symboling 0.00
dtype: float64It is clear from the abpve results that there is no null value left in the 'Normalized Losses' column.
- Similarly performing the same procedure with the rest of the target columns.
We will apply the same method for filling the null values as we did in the previous step.
df.loc[:,'Price'].fillna(df['Price'].mean(),inplace = True)
df.loc[:,'Stroke'].fillna(df['Stroke'].mean(),inplace = True)
df.loc[:,'Bore'].fillna(df['Bore'].mean(),inplace = True)
df.loc[:,'Peak RPM'].fillna(df['Peak RPM'].mean(),inplace = True)
df.loc[:,'Horsepower'].fillna(df['Horsepower'].mean(),inplace = True)
round(df.isnull().sum().sort_values(ascending = False)/len(df) * 100,2)No. of Doors 0.98
Price 0.00
Highway MPG 0.00
Normalized Losses 0.00
Make 0.00
Fuel Type 0.00
Aspiration 0.00
Body Style 0.00
Drive Wheels 0.00
Engine Location 0.00
Wheel Base 0.00
Length 0.00
Width 0.00
Height 0.00
Curb Weight 0.00
Engine Type 0.00
No. of Cylinders 0.00
Engine Size 0.00
Fuel System 0.00
Bore 0.00
Stroke 0.00
Compression Ratio 0.00
Horsepower 0.00
Peak RPM 0.00
City MPG 0.00
Symboling 0.00
dtype: float64The null values have been filled successfully except in 'No. of Doors' column.
- Filling the null values in 'No. of Doors' columns.
In this case the data the data is categorical so we first need to look at the data finding the unique values of it.
df[['No. of Doors']]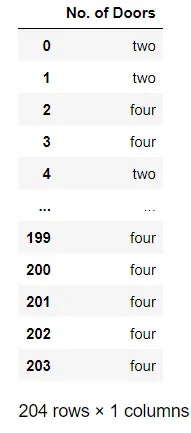
df['No. of Doors'].unique()array(['two', 'four', nan], dtype=object)So it is clear from the above results that there are two unique values under which the column is classified.
As it is a categorical data the 'mean' method won't work here. In this case we need to count the number of these categorical indicators. The indicator which has more number of counts will be used in filling the null value.
df['No. of Doors'].astype('category').value_counts()four 114
two 88
Name: No. of Doors, dtype: int64The above result indicates that there are more number of cars having 'four' doors than 'two' doors. So, accordingly we will use the 'four' indicator to fill the null values.
df.loc[:,'No. of Doors'].fillna('four',inplace = True)
df['No. of Doors'].astype('category').value_counts()
Price 0.0
Highway MPG 0.0
Normalized Losses 0.0
Make 0.0
Fuel Type 0.0
Aspiration 0.0
No. of Doors 0.0
Body Style 0.0
Drive Wheels 0.0
Engine Location 0.0
Wheel Base 0.0
Length 0.0
Width 0.0
Height 0.0
Curb Weight 0.0
Engine Type 0.0
No. of Cylinders 0.0
Engine Size 0.0
Fuel System 0.0
Bore 0.0
Stroke 0.0
Compression Ratio 0.0
Horsepower 0.0
Peak RPM 0.0
City MPG 0.0
Symboling 0.0We have successfully removed all the null values and hence we have cleaned our whole dataset in this way.
5. Exporting the cleaned dataframe to a csv file:
df.to_csv('clean_auto.csv')
6. Summary and Conclusion:
- The raw data was imported.
- All the columns was renamed.
- The null values was counted.
- All the null values was replaced by the columns's mean value.
- In the 'No. of Doors' column the null values are replaced by the most numbered categorical indicator.
- The new dataframe is exported to a csv file.
- Hence the '1985 Automobile Dataset' is cleaned.