Unsupervised Learning - Kmeans Week 11 Challenge
1. How does similarity is calculated if data is categorical in nature
We have Kmean to cluster data but it uses the distance between data to find clusters So we need Kmode
Kmode clustering is one of the unsupervised Machine learning techniques used to cluster categorical variables, It uses dissimilarity(total difference) between data points. Lesser the dissimilarity more data are in the same cluster It uses Mode instead of mean
2. Implement K-means for “Car dataset” and come up with the business insights
CarPrice_Assignment.csv
from sklearn.cluster import KMeans
data3=data.apply(preprocessing.LabelEncoder().fit_transform)
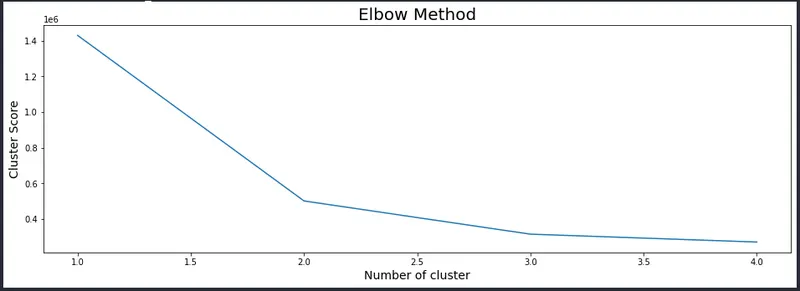
clu = KMeans(n_clusters=2, random_state=0) # here 2 gives best result
clu_fit=clu.fit(data3)
data3_pred=clu.predict(data3)
##
from sklearn.metrics import silhouette_score
score=silhouette_score(data3,data3_pred)
print('silhouette_score ',score)
silhouette_score  0.5094869582218358

From above analysis best way for dividing our dataset will be two cluster's


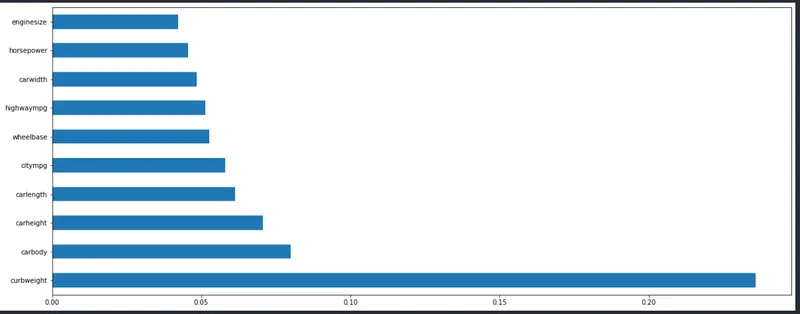
When I try to find feature importance for our dataset I get below diagram  and our Score get increase when we apply K-mean for important Feature's
silhouette_score 0.5108689348822545