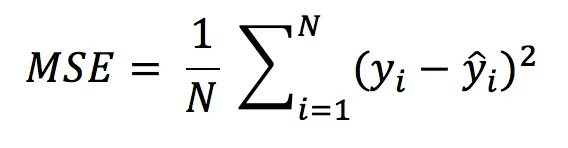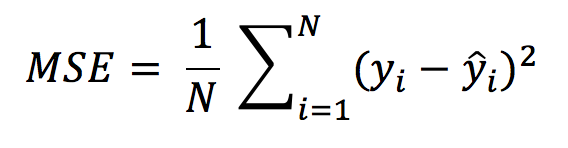alpha is the learning rate, i.e. how large a step the gradient takes.
Python code:
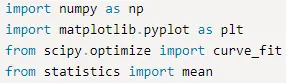
import numpy as np
import matplotlib.pyplot as plt
from scipy.optimize import curve_fit
from statistics import mean

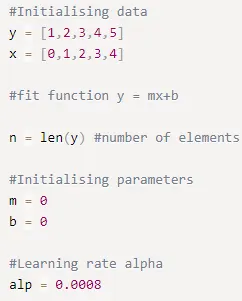
#Initialising data
y = [1,2,3,4,5]
x = [0,1,2,3,4]

#fit function y = mx+b

n = len(y) #number of elements

#Initialising parameters
m = 0
b = 0

#Learning rate alpha
alp = 0.0008

#Cost function
J = 9e9

tol = 1e-4 #Error tolerance

iter = 1 #Iterations

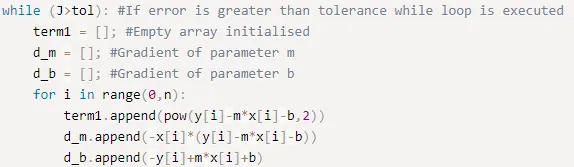
while (J>tol): #If error is greater than tolerance while loop is executed
	term1 = []; #Empty array initialised
	d_m = []; #Gradient of parameter m
	d_b = []; #Gradient of parameter b
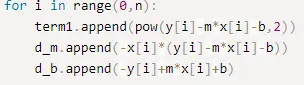
	for i in range(0,n):
		term1.append(pow(y[i]-m*x[i]-b,2))
		d_m.append(-x[i]*(y[i]-m*x[i]-b))
		d_b.append(-y[i]+m*x[i]+b)

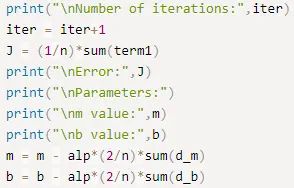
	print("nNumber of iterations:",iter)
	iter = iter+1
	J = (1/n)*sum(term1)
	print("nError:",J)
	print("nParameters:")
	print("nm value:",m)
	print("nb value:",b)
	m = m - alp*(2/n)*sum(d_m)
	b = b - alp*(2/n)*sum(d_b)
Code Explanation:
Necessary libraries are imported to execute the program:
Initial data and parameters are initialized:
Main body:
If the condition J>tol is true, then the while loop will be executed.
Inside the while loop, there is a for loop which fetches each value present in x and y and calculates the error and change in the loss function with respect to the parameters m and b
After exiting the for loop, the sum of the terms are calculated and this process keeps repeating till the error is lesser than the given tolerance value
Result:
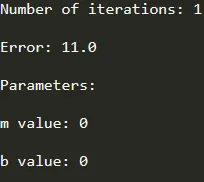
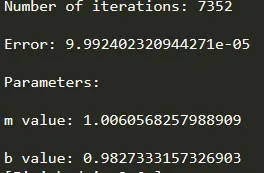
For a learning rate of 0.0008, it takes 7352 iterations for the error to be lesser than the tolerance and the m and b values are found to be 1.006 and 0.982 which are mathematically correct.
QUESTION 2.
L1 regularization penalizes the sum of absolute values of the weights, whereas L2 regularization penalizes the sum of squares of the weights.
The L1 regularization solution is sparse. The L2 regularization solution is non-sparse.
L2 regularization doesn’t perform feature selection, since weights are only reduced to values near 0 instead of 0. L1 regularization has built-in feature selection.
L1 regularization is robust to outliers, L2 regularization is not.
QUESTION 3.
Loss functions used in Regression:
Mean Square Error(MSE)/Root Mean Square Error(RMSE)
While R Square is a relative measure of how well the model fits dependent variables, Mean Square Error is an absolute measure of the goodness for the fit.
Mean Absolute Error (MAE)
Mean Squared Error (MSE)
Mean Bias Error (MBE)
Mean Squared Logarithmic Error (MSLE)
QUESTION 4.
The learning rate, denoted by the symbol α, is a hyper-parameter used to govern the pace at which an algorithm updates or learns the values of a parameter estimate. In other words,the learning rate regulates the weights of our neural network concerning the loss gradient>. It indicates how often the neural network refreshes the notions it has learned.
Learning rate is an important factor that determines how fast the function parameter approaches a nominal value. Gradient descent is a method to determine the values of the function parameters for which the function returns the minimum error.
It allows the training algorithm to keep track of the model’s performance and automatically alter the learning rate to achieve optimum results.
The learning rate increases or decreases in this method depending on the cost function’s gradient value. The learning rate will be reduced when the gradient value is higher, and larger when the gradient value is lower.
QUESTION 5.
Linear regression can be evaluated by determining how good the fit is, i.e. what is the error between the predicted value and the data set.
If the proposed equation is an nth degree polynomial
Differentiating the SSE with each coefficient and equating it to zero will return us the value of the coefficient for which the error is minimum.
Solving the multiple systems of equations we can get the value of the coefficients.
This is the least square error method.
R-square:
R square=SSRSSTR square=SSRSST, where
SST=SSE+SSRSST=SSE+SSR
SSR stands for the sum of the square of the regression and is equal to the square of the difference between the value of the fitting function at the given point and the mean of the data set.
SSR = N∑i=1(f(x(i))−M)2∑i=1N(f(x(i))-M)2, where M is the arithmetic mean of the given data set.
QUESTION 6.
When the dependent variable depends on only one independent variable then it is known as the linear coefficient of determination, but when it depends on multiple Independent variables then it is multiple coefficient of determination.
The Adjusted coefficient of determination is the method in which the parameters which do not contribute towards the predicted value are ignored. These parameters are called insignificant independent variables.
Adding new variables to the system will affect the R-squared value and the adjusted R-squared disregards the infinitesimally small increments and only considers the parameters which contribute to the output in a significant way.
R2 adj=1−(1−R2)(n−1)n−k−1R2 adj=1-(1-R2)(n-1)n-k-1, where
n = number of data points
k = number of independent variables
Case 1: If added variables are insignificant, that means k will increase with little or no effect on R2R2, hence R2 adjR2 adj will decrease.
Case 2: If added variables are significant, that means k will increase with a significant increase in R2R2, hence R2 adjR2 adj will also increase.