Supervised Learning - Prediction Week 3 Challenge
Q1. Ans:
To perform gradient descent in python using mean square error as loss function on the following data set:
- y = [1,2,3,4,5]
x = [0,1,2,3,4]
Theory:
Loss function:
J = (1n)∑(y(i)−(mx(i)+b))2(1n)∑(y(i)-(mx(i)+b))2, where
x(i) are the input
m and b are the weights
mx(i)+b is the predicted output and y(i) is the actual value
Differentiating the loss function J with respect to m and b, we get
dJ/dm = (2n)∑−x(i)(y(i)−(mx(i)+b))(2n)∑-x(i)(y(i)-(mx(i)+b))
dJ/db = (2n)∑−(y(i)−(mx(i)+b))(2n)∑-(y(i)-(mx(i)+b))
m and b values are then optimized
m = m - alpha*dJ/dm
b = b - alpha*dJ/db
alpha is the learning rate, i.e. how large a step the gradient takes.
Q2. Ans:
L1 Mean absolute error: finds the mean of the absolute difference between the predicted and actual value. It is good for data set with little or no outliers. However, it needs more complicated tools such as linear programming to calculate the gradients of the parameters.
L2 Mean squared error: Finds the mean of the square of the difference between the predicted and actual value. It is good for data set with outliers, however returns an error in different units. Due to its mathematical properties, it is easier to calculate the gradients of the parameters. The squaring means that larger mistakes result in more error than smaller mistakes, meaning that the model is punished for making larger mistakes.
Finding the root of the mean squared error, i.e. using root mean square error bring the error term to match with the data set in terms of units.
Q3. Ans:
Root mean square error
Mean square error
Mean absolute error
Q4. Ans:
Let F be a function that determines the error between the data set and the predicted values. The predicted values depend on two parameters m, and c. Gradient descent is a method to determine the values of the parameters for which F returns the least value.
Learning rate is an important factor that determines how fast the function parameter approaches a nominal value. Gradient descent is a method to determine the values of the function parameters for which the function returns the minimum error.
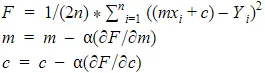
Giving a high learning rate will cause the function to overshoot beyond its lowest value and will never reach its lowest value or will oscillate before arriving at one.
Giving a low learning rate will cause the function to approach the lowest value very slowly leading to a high number of iterations.
Q5. Ans:
Linear regression can be evaluated by determining how good the fit is, i.e. what is the error between the predicted value and the data set.
R-squared :
Assume function f(x) to satisfy the data points (x1,y1), (x2,y2).. and so on.
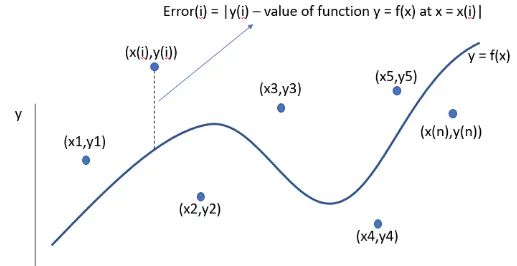
Sum of squared error SSE = N∑i=1(y(i)−f(x(i)))2∑i=1N(y(i)-f(x(i)))2
If the proposed equation is an nth degree polynomial
f(x)=A1+A2⋅x+A3⋅x2+..+A n⋅xn−1f(x)=A1+A2⋅x+A3⋅x2+..+A n⋅xn-1
Differentiating the SSE with each coefficient and equating it to zero will return us the value of the coefficient for which the error is minimum.
Solving the multiple systems of equations we can get the value of the coefficients.
This is the least square error method.
R-square:
R square=SSRSSTR square=SSRSST, where
SST=SSE+SSRSST=SSE+SSR
SSR stands for the sum of the square of the regression and is equal to the square of the difference between the value of the fitting function at the given point and the mean of the data set.
SSR = N∑i=1(f(x(i))−M)2∑i=1N(f(x(i))-M)2, where M is the arithmetic mean of the given data set.
Q6. Ans:
When the dependent variable depends on only one independent variable then it is known as the linear coefficient of determination, but when it depends on multiple Independent variables then it is multiple coefficient of determination.
The Adjusted coefficient of determination is the method in which the parameters which do not contribute towards the predicted value are ignored. These parameters are called insignificant independent variables.
Adding new variables to the system will affect the R-squared value and the adjusted R-squared disregards the infinitesimally small increments and only considers the parameters which contribute to the output in a significant way.
R2 adj=1−(1−R2)(n−1)n−k−1R2 adj=1-(1-R2)(n-1)n-k-1, where
n = number of data points
k = number of independent variables
Case 1: If added variables are insignificant, that means k will increase with little or no effect on R2R2, hence R2 adjR2 adj will decrease.
Case 2: If added variables are significant, that means k will increase with a significant increase in R2R2, hence R2 adjR2 adj will also increase.