Supervised Learning - Classification Week 8 Challenge
1- Kindly find the attached file.
2-Pros and Cons of KNN.
KNN: K-Nearest Neighbour:
Knn is suitable for the saying "Tell me about your friends, I'll tell about you". Its classifies the data by finding the distance between (K)number of its neighbour data points.
steps involved:
1->Set a value of K- which is number of data points the algorithm should consider for classification.
2->find the distance between new data points to the other.
3->Repeat step 2 for K data points.
4->Consider the majority of classification of distance from data points.
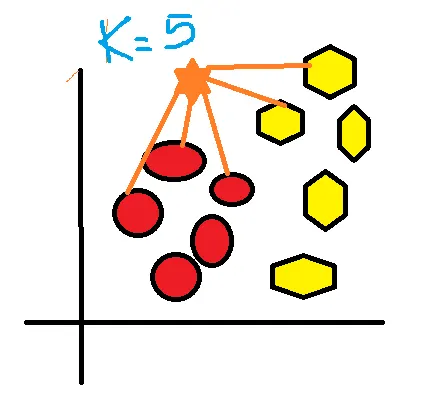
From above diagram, we have 2 classifications (red,yellow) and orange is new data point which we are going to classify using knn by considering k=5. After finding the distance between orange and its 5 near datapoints, the maximum of classification near to orange data point is red. So the new orange would be consider as red class.
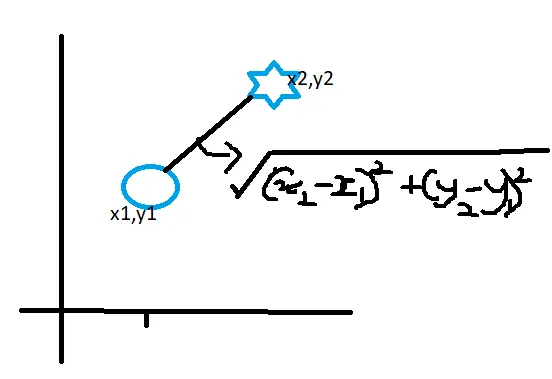
Distance between datapoints can be calculated using
1->Euclidean Distance
2->Manhattan Distance
Euclidean distance: its is called based on the pythagoras theorum
.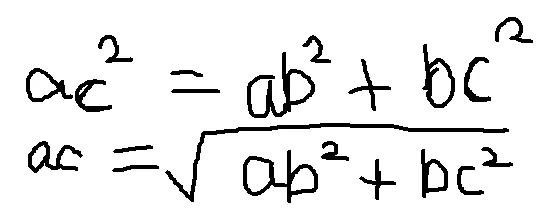
Manhattan Distance:
In Manhattan distance, hypotesis is calculated by adding the magnitude of its adjacent sides.
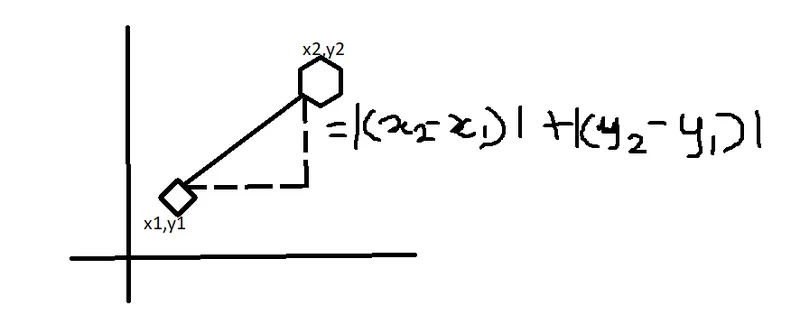
We might need to use both distance calculation in a model and find the best suits our model. It can be done by using any hyperparameter techniques.
Advanatges and Disadvantages of KNN:
advantages:
>Knn is also known as lazy learner algorithm (Instance based learning). It just shows the data on the training period and learns at the time of making predictions. This makes the algorithm to works faster.
>Easy to implement
>It's a instance based learning, a memory based approach. it easily adapts to training data.
>can be used for both classification and regression.
Disadvantages:
>it doesn't work well on large dataset, since the time for calculating the distance between data points can be higher in large datasets. It can affect the model performance.
>Feature engineering is must.
>Might need to remove the outliers
>finding the optimal number of K to be used in the model
>Doesn't perform well on imbalanced dataset, need to use hyparameter and scaling to get better accuracy.