Supervised Learning - Classification Week 7 Challenge
SVM: Support Vector Machines
>is used in classification and regression problems
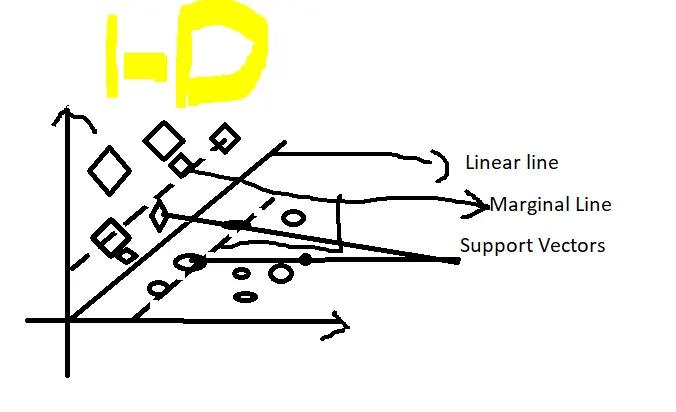
>is to predict a linearly seperable line for classification and need to find the marginal seperable line respect to that linear line with maximum distance (Marginal distance).
>the data points which are immediate next to those Marginal lines are called Support Vectors.
>In 2D data, the line would be linear seperable and in 3D data it would be known as Hyperplane.
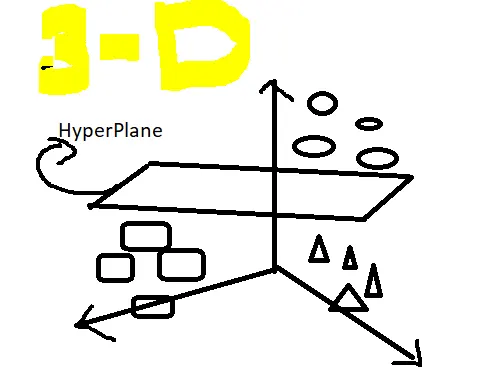
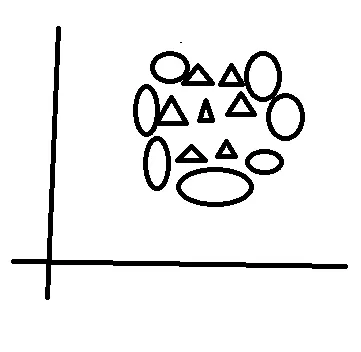
>If there is a linearly seperable data in a dataset, we need to Support Vector Kernel for converting the Low dimension data into High dimension data for classification.
2)-Kindly find the attached file for implementing svm to Fault steel plates.
Maths Behind SVM:
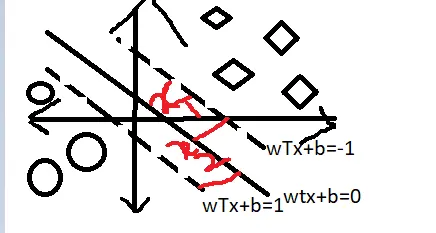 If we want to find the distance between x1,x2 we can write the equation as wTx1+b=-1,wTx2+b=1 then we get wT(x2-x1)=2
In order to remove wT will divide it by magnitude of w on both sides results:
(wT(x2-x1))/||w||=2/||w||
2/||w|| is a optimal function , and y can also be stated as
yi=-1 > wTx+b<=-1, yi=1 > wTx+b>=1 we can write it as yi * wTx+b >=1 so if the value is not >=1 then we can say its a misclassification.
There will not be always a linearly seperable data, we need to do hyper-parameter technique for changing w,b as
w,b=min(||w||/2) + (Count of errors C * (Sum of error values))
error> are the error distance from marginal plane to datapoint
SVM Kernels:
SVM Kernels will tranform the low dimension data into high dimension through mathematical formulas for classification.
if we consider a 1-D data like below,
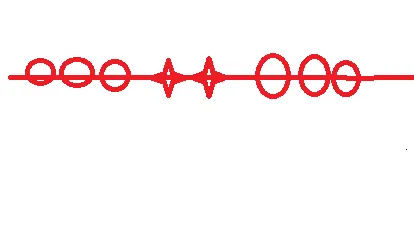 by using f(x)=x2 and plotting it as
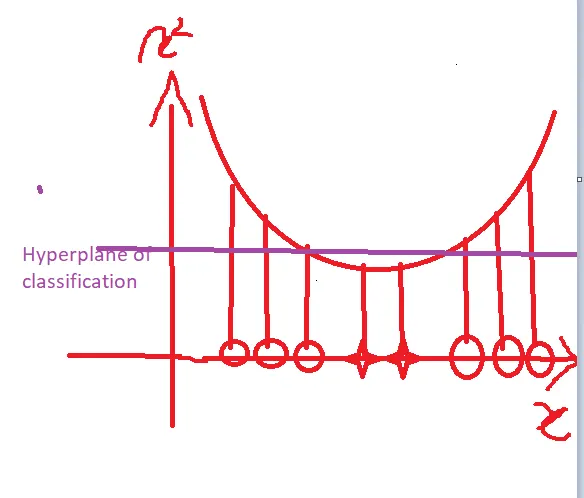
1-D was converted into 2-D, now we can able to classify the data
Similary if we have a data then applying a polynomial kernel function
f(x1,x2)=(x1T.x2+1)d 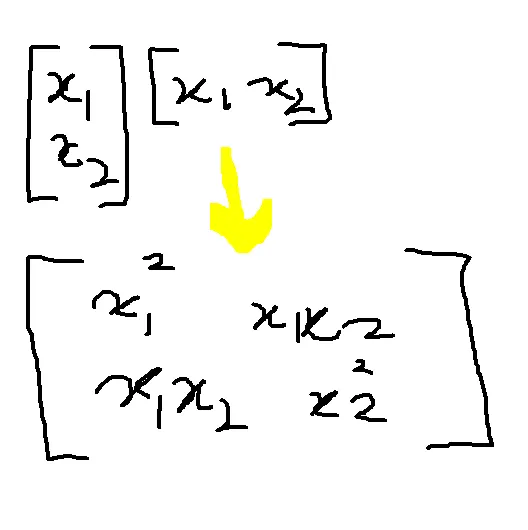
considering unique from above along with x1,x2 we got x1,x2,x12(square),x22(square),x1x2 and plotting these would help us to classify data using hyperplane.
1-Pros and Cons of SVM:
Pros:
We can use well, if we are not aware of data.
Provides a more generalized model of data and reduces the over-fitting issues.
Kernel function is key for better classification, by choosing the right kernel we can resolve a complex problems.
Works well in unstructed and semi-structured data (eg:images, videos)
Suits well for the High dimensional data
Comparing to ANN, it provides better results.
Cons:
Choosing a apt Kernel is not that easy.
Long training time for long dataset.
Difficult to interpret the final model, weights and individual impact.
Hyper parameters in SVM:
C, Gamma are the hyper-parameters in SVM.
Gamma:
>this parameter is to handle the non-linear seperable data
>Controls the distance of influence of single training point.
>Will be using hyperplane for converting the low dimension to high dimension data, one of the RBF kernel technique requires gamma as a parameter to control the peak when data points are raised.
>Lower Gamma values - high bias and low variance leads to under-fitting
>High Gamma values - Low bias and High Variance leads to over-fitting
C:
>cost of misclassification
>Lower C values - high bias and low variance leads to under-fitting
>High C values - Low bias and High Variance leads to over-fitting
Chossing a right Gamma and C can be done with the help of Grid-Search.