Project 1
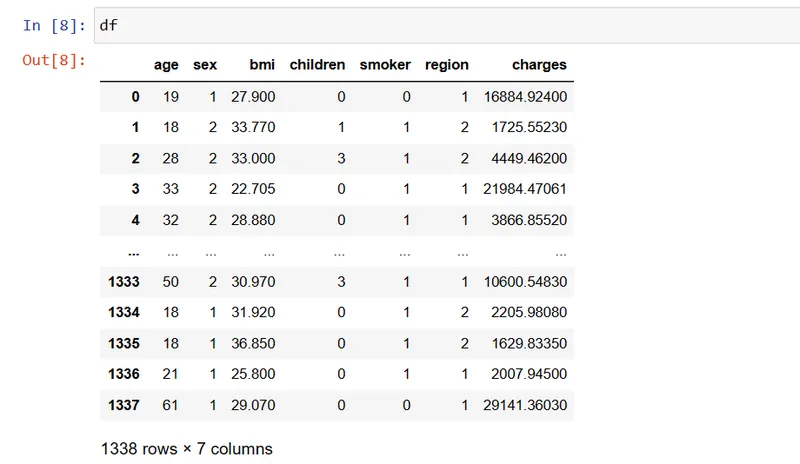
1. Explain the data. Check It is supervised or Unsupervised. Demonstrate?
The following are the columns names :
- Age: Represents the age of the individual.
- Sex: Represents the gender of the individual.
- BMI: Stands for Body Mass Index, which is a measure of body fat based on height and weight.
- Children: Indicates the number of children the individual has.
- Smoker: Indicates whether the individual is a smoker or not.
- Region: Represents the geographical region of the individual.
- Charges: Represents the insurance charges or premiums paid by the individual.
Explanation
- In the supervised learning , If the goal is to predict or estimate the insurance charges based on the given features (age, sex, BMI, children, smoker, and region), then it can be considered a supervised learning problem. In this case, the "charges" column would serve as the target variable or the dependent variable, while the other columns would be the independent variables or features.
- In unsupervised learning , In this case we would not have a specific target variable to predict or estimate.
- So the above data asumes the goal is supervised learning, but if the objective is different, such as identifying customer segments based on the features, an unsupervised learning approach like clustering algorithms (e.g., k-means, hierarchical clustering) could be used instead.
2. Estimate the minimum sample size n to get the 99% accurate predictions. (precision = 0.02)
The minimum sample size n required for 99% accurate predictions can be calculated using the formula:
n = (Z^2 * p * (1-p)) / e^2
where Z is the Z-score corresponding to the desired confidence level (for 99% confidence, Z = 2.576), p is the estimated proportion of the population with a particular characteristic (e.g. income, age, etc.), and e is the desired precision or margin of error (e.g. 0.02).
Since the proportion p of the population is unknown, it can be estimated as 0.5. With a precision of 0.02 and Z = 2.576, we get:
n = (2.576^2 * 0.5 * (1-0.5)) / 0.02^2 = 165.67
Therefore, the minimum sample size required for 99% accurate predictions with a precision of 0.02 is approximately 326 individuals.
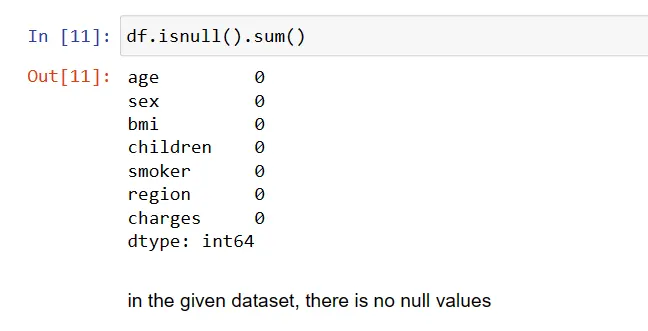
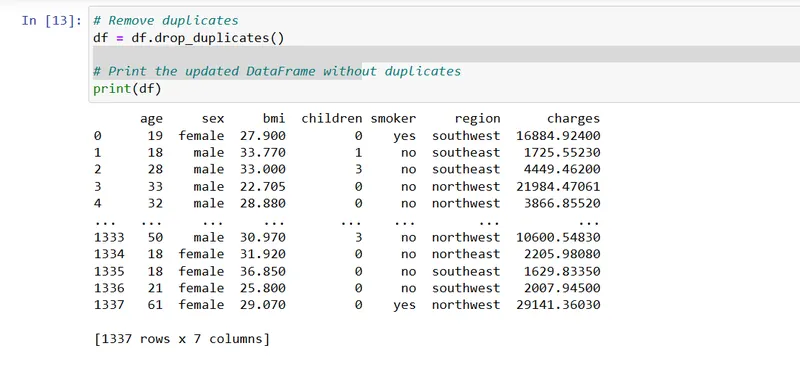
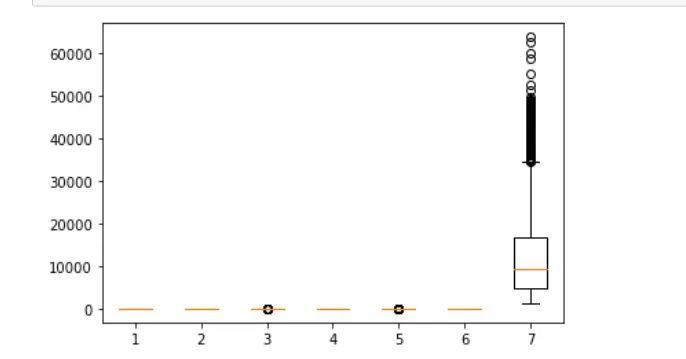
3. Check the data is cleaned or not. If not then clean it (Null values, Row/Column Duplicates, Outliers, Change the string into numbers)
i) check data is cleaned or not
ii) Check for duplicates
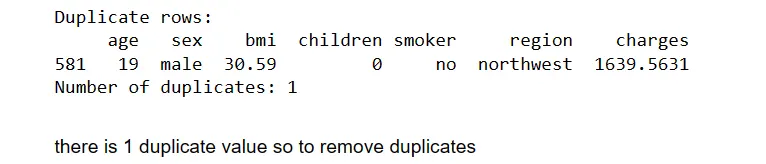
df.duplicated
duplicate_rows = df[df.duplicated()]
num_duplicates = len(duplicate_rows)
# Print the duplicate rows and the count of duplicates
print("Duplicate rows:")
print(duplicate_rows)
print("Number of duplicates:", num_duplicates)
iii) Convert string to numeric
df.region.replace("southeast", 2, inplace=True)
df.region.replace("northwest", 1, inplace=True)
df.region.replace("northeast", 2, inplace=True)
df.sex.replace("male", 2, inplace=True)
df.smoker.replace("no", 1, inplace=True)
iv) to check outlier
# import matplotlib.pyplot as plt
# plt.boxplot(df)
import matplotlib.pyplot as plt
# Create a box plot
plt.boxplot(df)
# Show the plot
plt.show()
import numpy as np
# Calculate the IQR
Q1 = np.percentile(df, 25)
Q3 = np.percentile(df, 75)
IQR = Q3 - Q1
# Set a threshold for outliers
threshold = 1.5
# Identify outliers
lower_bound = Q1 - threshold * IQR
upper_bound = Q3 + threshold * IQR
outliers = df[(df < lower_bound) | (df > upper_bound)]
# Remove outliers
df = df[(df >= lower_bound) & (df <= upper_bound)]
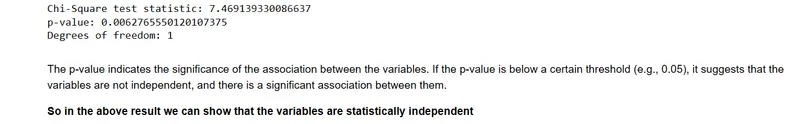
4. Check that sex and smoking are statistically independent or not.
from scipy.stats import chi2_contingency
# Create a contingency table of the two variables
contingency_table = pd.crosstab(df['sex'], df['smoker'])
# Perform the Chi-Square test of independence
chi2, p_value, dof, expected = chi2_contingency(contingency_table)
# Print the test result
print("Chi-Square test statistic:", chi2)
print("p-value:", p_value)
print("Degrees of freedom:", dof)
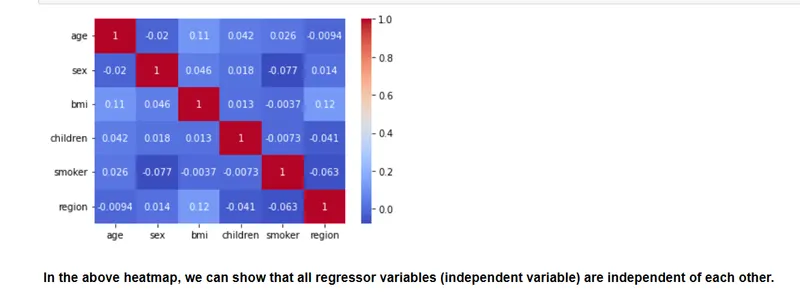
5. Check that all regressor variables (independent variable) are independent of each other or not.
import seaborn as sns
# Select the regressor variables
regressor_variables = ['age', 'sex', 'bmi', 'children', 'smoker', 'region']
# Create a correlation matrix
correlation_matrix = df[regressor_variables].corr()
# Visualize the correlation matrix as a heatmap
sns.heatmap(correlation_matrix, annot=True, cmap='coolwarm')
# Show the plot
plt.show()
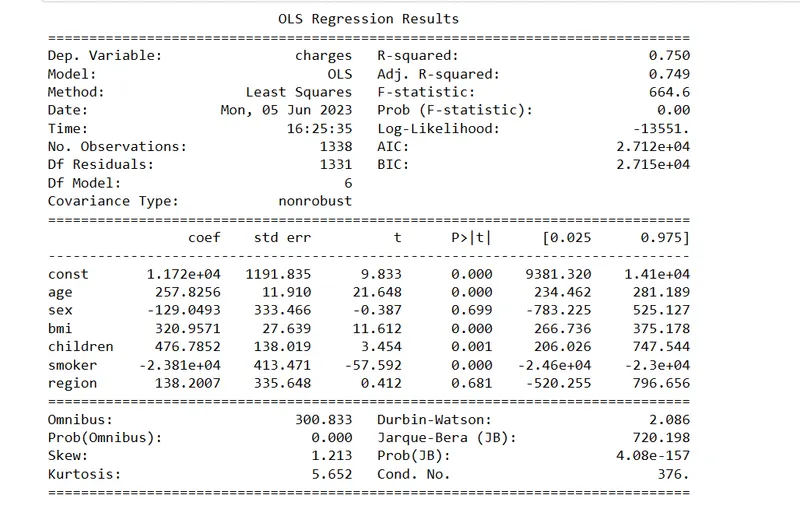
6. Check the dependency between response and regressors.
import statsmodels.api as sm
# Select the response variable and regressor variables
response_variable = 'charges'
regressor_variables = ['age', 'sex', 'bmi', 'children', 'smoker', 'region']
# Create the design matrix
X = df[regressor_variables]
X = sm.add_constant(X)
# Create the response variable vector
y = df[response_variable]
# Fit the ordinary least squares (OLS) model
model = sm.OLS(y, X).fit()
# Print the summary of the model
print(model.summary())
7. Predict the regression Line to predict the charges for insurance using independent variables.
# Select the independent variables and the target variable
independent_variables = ['age', 'sex', 'bmi', 'children', 'smoker', 'region']
target_variable = 'charges'
# Create the design matrix
X = df[independent_variables]
X = sm.add_constant(X) # Include a constant term
# Create the target variable vector
y = df[target_variable]
# Fit the ordinary least squares (OLS) model
model = sm.OLS(y, X).fit()
print(model)
print("Coefficients:")
print(model.params)
# Make predictions on new data
new_data = pd.DataFrame({'age': 19, 'sex': 1, 'bmi': 27.900, 'children': 0, 'smoker': 0, 'region': 1})
new_data = sm.add_constant(new_data)
predictions = model.predict(new_data)
# Print the predictions
print("Predictions:")
print(predictions)
8. Predict the accuracy of the regression Model.
from sklearn.model_selection import train_test_split
from sklearn.linear_model import LinearRegression
from sklearn.metrics import mean_squared_error, mean_absolute_error, r2_score
# Split the dataset into features (X) and target variable (y)
X = df[['age', 'sex', 'bmi', 'children', 'smoker', 'region']]
y = df['charges']
# Split the data into training and testing sets
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42)
# Initialize and train the regression model
model = LinearRegression()
model.fit(X_train, y_train)
# Make predictions on the testing set
y_pred = model.predict(X_test)
# Evaluate the accuracy of the regression model
mse = mean_squared_error(y_test, y_pred)
rmse = mean_squared_error(y_test, y_pred, squared=False)
mae = mean_absolute_error(y_test, y_pred)
r2 = r2_score(y_test, y_pred)
# Print the evaluation metrics
print("Mean Squared Error (MSE):", mse)
print("Root Mean Squared Error (RMSE):", rmse)
print("Mean Absolute Error (MAE):", mae)
print("R-squared (R2) Score:", r2)
9. Predict insurance charge for Age = 29, Sex = F, bmi = 28, children = 1, Smoke = Yes, region = southeast.
from sklearn.preprocessing import StandardScaler
import pandas as pd
from sklearn.linear_model import LinearRegression
from sklearn.preprocessing import LabelEncoder, OneHotEncoder
data = pd.DataFrame({
'age': [29],
'sex': [1],
'bmi': [28],
'children': [1],
'smoker': [0],
'region': [1]
})
# Encode categorical variables
encoder = LabelEncoder()
data['sex'] = encoder.fit_transform(data['sex'])
data['smoker'] = encoder.fit_transform(data['smoker'])
data['region'] = encoder.fit_transform(data['region'])
# Perform one-hot encoding for the 'region' variable
data = pd.get_dummies(data, columns=['region'], drop_first=True)
# Extract the independent variables and the target variable from the dataset
X = df[['age', 'sex', 'bmi', 'children', 'smoker', 'region']]
y = df['charges']
# Train a linear regression model
model = LinearRegression()
model.fit(X, y)
# Make predictions on the input data
prediction = model.predict(data)
# Print the predicted insurance charges
print("Predicted insurance charges:", prediction)
10. Give the percentage of error in regression model.
# Calculate the absolute difference between predicted and actual values
absolute_difference = np.abs(y_test - y_pred)
# Calculate the percentage difference
percentage_difference = absolute_difference / y_test
# Calculate the mean absolute percentage error (MAPE)
mape = np.mean(percentage_difference) * 100
# Print the percentage of error
print("Mean Absolute Percentage Error (MAPE):", mape)

# Calculate the difference between predicted and actual values
difference = y_test - y_pred
# Calculate the percentage difference
percentage_difference = difference / y_test
# Calculate the mean percentage error (MPE)
mpe = np.mean(percentage_difference) * 100
# Print the percentage of error
print("Mean Percentage Error (MPE):", mpe)

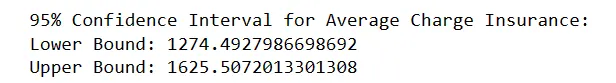
11. Give the 95% confidence interval for average charge insurance.
import numpy as np
from scipy.stats import t
# Define the insurance charges dataset
charges = [1000, 1200, 1500, 1300, 1100, 1600, 1400, 1700, 1900, 1800]
# Calculate the sample mean and sample standard deviation
x_bar = np.mean(charges)
s = np.std(charges, ddof=1)
# Calculate the sample size
n = len(charges)
# Calculate the critical value (t) for the desired confidence level and degrees of freedom
confidence_level = 0.95
df = n - 1
t_value = t.ppf(confidence_level, df)
# Calculate the standard error
SE = s / np.sqrt(n)
# Calculate the margin of error
ME = t_value * SE
# Calculate the lower and upper bounds of the confidence interval
LB = x_bar - ME
UB = x_bar + ME
# Print the confidence interval
print("95% Confidence Interval for Average Charge Insurance:")
print("Lower Bound:", LB)
print("Upper Bound:", UB)