Basics of Probability and Statistics Week 1 Challenge
Why there is a difference in the formula of variance for population and sample ?
- In Statistics the term sampling refers to selection of a part of aggregate statistical data for the purpose of obtaining relevant information about the whole. The aggregate or whole of statistical information on a particular charcter of all the members covered by the investigation is called ‘population’ or ‘universe’. (Das, N.G., 2010). The selected part of the population which is used to obtain the characteristics of the population or universe is termed as ‘sample’. The population is taken to be made of individual units or members, and some of the units are included in the sample. Total number of units of the population is called population size, and that of the sample is called sample size.
- Variance is a numerical value that shows how widely the individual figures in a set of data distribute themselves about the mean. That is how far each number is from the mean, and thus from each other. A variance of zero value means all the data are identical. More the variance, more are the values spread out about mean, hence from each other. Less the variance, less are the values spread out about mean, hence from each other, and variance can’t be negative.
The formula for calculation of variance for population data set is as follows:
`σ^2 =( sum_(i=1) ^n (X_i-mu)^2)/n`
The formula for calculation of variance for sample data set is as follows:
`s^2 =( sum_(i=1) ^n (x_i-mu)^2)/(n-1)`
There is only one little difference in the calculation of variance and it is at the very end of it. For both population and sample variance, We calculate the mean, then the deviations from the mean, and then We square all the deviations. We sum all the squared deviations up. So far it was the same for both population and sample variance.
When We calculate population variance, We then divide the sum of squared deviations from the mean by the number of items in the population.
When We calculate sample variance, We divide it by the number of items in the sample less one.
As a result, the calculated sample variance will be slightly higher than if we would have used the population variance formula. The purpose of this little difference it to get a better and unbiased estimate of the population‘s variance (by dividing by the sample size lowered by one, we compensate for the fact that we are working only with a sample rather than with the whole population).
The logic of doing that is to compensate our lack of information about the population data. It is impossible to find out variance of heights in human beings, for our absolute lack of information about heights of all living human beings, not to talk of the future. Even if we take one moderate example, like population data on heights of all the living men in US it is physically possible, but the cost and time involved in this would defeat the purpose of its calculation. This is the reason sample data are taken for most of the statistical purposes, and this is accompanied by lack of information about majority of data. In order to compensate this, the value of variance are higher in case of sample data than variance from population data.
Difference between stratified and clustered sampling ?
Stratified Sampling involves dividing the population into subpopulations that may differ in important ways. It allows you draw more precise conclusions by ensuring that every subgroup is properly represented in the sample.
To use this sampling method, you divide the population into subgroups (called strata) based on the relevant characteristic (e.g. gender, age range, income bracket, job role).
Based on the overall proportions of the population, you calculate how many people should be sampled from each subgroup. Then you use random or systematic sampling to select a sample from each subgroup.
Eg: The company has 800 female employees and 200 male employees. You want to ensure that the sample reflects the gender balance of the company, so you sort the population into two strata based on gender. Then you use random sampling on each group, selecting 80 women and 20 men, which gives you a representative sample of 100 people.
Cluster Sampling also involves dividing the population into subgroups, but each subgroup should have similar characteristics to the whole sample. Instead of sampling individuals from each subgroup, you randomly select entire subgroups.
If it is practically possible, you might include every individual from each sampled cluster. If the clusters themselves are large, you can also sample individuals from within each cluster using one of the techniques above.
This method is good for dealing with large and dispersed populations, but there is more risk of error in the sample, as there could be substantial differences between clusters. It’s difficult to guarantee that the sampled clusters are really representative of the whole population.
Eg: The company has offices in 10 cities across the country (all with roughly the same number of employees in similar roles). You don’t have the capacity to travel to every office to collect your data, so you use random sampling to select 3 offices – these are your clusters.
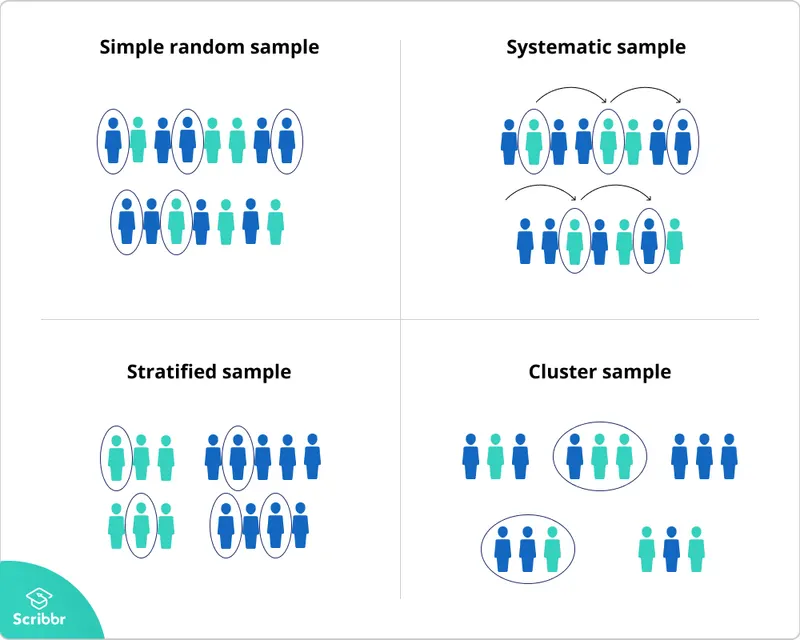
©Scribbr
How many different samples can be created out of population of size n ?
Let us consider the population of size 4.
`X = {a,b,c,d}`
All the possible samples are as follows:
`S = {{a},{b},{c},{d},{a,b},{a,c},{a,d},{b,c},{b,d},{c,d},{a,b,c},{a,b,d},{b,c,d},{a,c,d},{a,b,c,d}}`
The total numer of samples = 15 = `2^4-1`
Thus, the total number of samples that can be generated from a population of size N = `2^N-1`
What is the probability of drawing 2 jacks from a pack of card ?
The pack contains 52 cards of it 4 are jacks.
Probability of drawing 1st card jack is 4C1 from 52 cards.
Probability of drawing 2nd card jack is 3C1 from 51 cards. (1 jack is already drawn thus 3 jacks are remaining out of 51 cards).
Both the events are independent. Thus the multiplication rule is used.
Thus, the probability of drawing 2 jacks from the deck of 52 cards is calculated as follows:
`(.^4C_1)/52*(.^3C_1)/51 = 1/221`
The probability of drawing 2 jacks from a pack of cards is 1/221.
What is the probability that both the numbers on dice are same while rolling 2 dice?
Total number of outcomes = 6*6 = 36.
Number of outcomes with same number on both dices = 6.
Thus the probability of drawing both the numbers on 2 dices is same = 6/36 = 1/6.
Why standard deviation when variance can measure the dispersion in data?
The variance is the average of the squared differences from the mean. To figure out the variance, first calculate the difference between each point and the mean; then, square and average the results.
For example, if a group of numbers ranges from 1 to 10, it will have a mean of 5.5. If you square the differences between each number and the mean, and then find their sum, the result is 82.5. To figure out the variance, divide the sum, 82.5, by N-1, which is the sample size (in this case 10) minus 1. The result is a variance of 82.5/9 = 9.17. Standard deviation is the square root of the variance so that the standard deviation would be about 3.03.
Because of this squaring, the variance is no longer in the same unit of measurement as the original data. Taking the root of the variance means the standard deviation is restored to the original unit of measure and therefore much easier to interpret.