Project 2 - EDA on Vehicle Insurance Customer Data
'''A company has customer data that contains 8 columns of customer details and another table having name customer_policy data contains the policy details of the customer.
The company intends to offer some discount in premium for certain customers. To do that they ask their Data scientist team to get some information. Hence, following tasks DS team decided to perform:
1. Add the column names to both datasets:
i. Column Name for customer details table:
customer_id,
Gender,
age,
driving licence present,
region code,
previously insured,
vehicle age
and vehicle damage, in respective order.
ii. Column Name for customer_policy table:
customer_id,
annual premium (in Rs),
sales channel code,
vintage and response. '''
'A company has customer data that contains 8 columns of customer details and another table having name customer_policy data contains the policy details of the customer. nnThe company intends to offer some discount in premium for certain customers. To do that they ask their Data scientist team to get some information. Hence, following tasks DS team decided to perform:nn1. Add the column names to both datasets:nni. Column Name for customer details table:nn customer_id, nn Gender,nn age, nn driving licence present,nn region code, nn previously insured, nn vehicle age nn and vehicle damage, in respective order. nnii. Column Name for customer_policy table:nn customer_id, nn annual premium (in Rs), nn sales channel code, nn vintage and response. '
import pandas as pd
customer_details = pd.read_csv(".customer_details.csv", header = None)
customer_details
| 0 | 1 | 2 | 3 | 4 | 5 | 6 | 7 | |
|---|---|---|---|---|---|---|---|---|
| 0 | 0.0 | 1 | 2.0 | 3.0 | 4.0 | 5.0 | 6 | 7 |
| 1 | 1.0 | Male | 44.0 | 1.0 | 28.0 | 0.0 | > 2 Years | Yes |
| 2 | 2.0 | Male | 76.0 | 1.0 | 3.0 | 0.0 | 1-2 Year | No |
| 3 | 3.0 | Male | 47.0 | 1.0 | 28.0 | 0.0 | > 2 Years | Yes |
| 4 | 4.0 | Male | 21.0 | 1.0 | 11.0 | 1.0 | < 1 Year | No |
| ... | ... | ... | ... | ... | ... | ... | ... | ... |
| 381105 | 381105.0 | Male | 74.0 | 1.0 | 26.0 | 1.0 | 1-2 Year | No |
| 381106 | 381106.0 | Male | 30.0 | 1.0 | 37.0 | 1.0 | < 1 Year | No |
| 381107 | 381107.0 | Male | 21.0 | 1.0 | 30.0 | 1.0 | < 1 Year | No |
| 381108 | 381108.0 | Female | 68.0 | 1.0 | 14.0 | 0.0 | > 2 Years | Yes |
| 381109 | 381109.0 | Male | 46.0 | 1.0 | 29.0 | 0.0 | 1-2 Year | No |
381110 rows × 8 columns
customer_policy = pd.read_csv(".customer_policy_details.csv", header = None)
customer_policy
| 0 | 1 | 2 | 3 | 4 | |
|---|---|---|---|---|---|
| 0 | 0.0 | 1.0 | 2.0 | 3.0 | 4.0 |
| 1 | 1.0 | 40454.0 | 26.0 | 217.0 | 1.0 |
| 2 | 2.0 | 33536.0 | 26.0 | 183.0 | 0.0 |
| 3 | 3.0 | 38294.0 | 26.0 | 27.0 | 1.0 |
| 4 | 4.0 | 28619.0 | 152.0 | 203.0 | 0.0 |
| ... | ... | ... | ... | ... | ... |
| 381105 | 381105.0 | 30170.0 | 26.0 | 88.0 | 0.0 |
| 381106 | 381106.0 | 40016.0 | 152.0 | 131.0 | 0.0 |
| 381107 | 381107.0 | 35118.0 | 160.0 | 161.0 | 0.0 |
| 381108 | 381108.0 | 44617.0 | 124.0 | 74.0 | 0.0 |
| 381109 | 381109.0 | 41777.0 | 26.0 | 237.0 | 0.0 |
381110 rows × 5 columns
# Add the column names to both datasets:
# i. Column Name for customer details table:
# customer_id, Gender,age,driving licence present,region code, previously insured, vehicle age and vehicle damage, in respective order.
customer_details.columns = ["Customer_id","Gender","Age","Driving Licence Present","Region Code","Previously Insured","Vehicle Age","Vehicle Damage"]
customer_details
| Customer_id | Gender | Age | Driving Licence Present | Region Code | Previously Insured | Vehicle Age | Vehicle Damage | |
|---|---|---|---|---|---|---|---|---|
| 0 | 0.0 | 1 | 2.0 | 3.0 | 4.0 | 5.0 | 6 | 7 |
| 1 | 1.0 | Male | 44.0 | 1.0 | 28.0 | 0.0 | > 2 Years | Yes |
| 2 | 2.0 | Male | 76.0 | 1.0 | 3.0 | 0.0 | 1-2 Year | No |
| 3 | 3.0 | Male | 47.0 | 1.0 | 28.0 | 0.0 | > 2 Years | Yes |
| 4 | 4.0 | Male | 21.0 | 1.0 | 11.0 | 1.0 | < 1 Year | No |
| ... | ... | ... | ... | ... | ... | ... | ... | ... |
| 381105 | 381105.0 | Male | 74.0 | 1.0 | 26.0 | 1.0 | 1-2 Year | No |
| 381106 | 381106.0 | Male | 30.0 | 1.0 | 37.0 | 1.0 | < 1 Year | No |
| 381107 | 381107.0 | Male | 21.0 | 1.0 | 30.0 | 1.0 | < 1 Year | No |
| 381108 | 381108.0 | Female | 68.0 | 1.0 | 14.0 | 0.0 | > 2 Years | Yes |
| 381109 | 381109.0 | Male | 46.0 | 1.0 | 29.0 | 0.0 | 1-2 Year | No |
# ii. Column Name for customer_policy table:
# customer_id, annual premium (in Rs), sales channel code, vintage and response.
customer_policy.columns = ["Customer_id","Annual Premium (in Rs)","Sales Channel Code","Vintage","Response"]
customer_policy
| Customer_id | Annual Premium (in Rs) | Sales Channel Code | Vintage | Response | |
|---|---|---|---|---|---|
| 0 | 0.0 | 1.0 | 2.0 | 3.0 | 4.0 |
| 1 | 1.0 | 40454.0 | 26.0 | 217.0 | 1.0 |
| 2 | 2.0 | 33536.0 | 26.0 | 183.0 | 0.0 |
| 3 | 3.0 | 38294.0 | 26.0 | 27.0 | 1.0 |
| 4 | 4.0 | 28619.0 | 152.0 | 203.0 | 0.0 |
| ... | ... | ... | ... | ... | ... |
| 381105 | 381105.0 | 30170.0 | 26.0 | 88.0 | 0.0 |
| 381106 | 381106.0 | 40016.0 | 152.0 | 131.0 | 0.0 |
| 381107 | 381107.0 | 35118.0 | 160.0 | 161.0 | 0.0 |
| 381108 | 381108.0 | 44617.0 | 124.0 | 74.0 | 0.0 |
| 381109 | 381109.0 | 41777.0 | 26.0 | 237.0 | 0.0 |
# 2. Checking and Cleaning Data Quality:
# i. Null values
# Generate a summary of count of all the null values column wise
# Drop Null values for customer_id because central tendencies for id’s is not feasible.
# Replace all null values for numeric columns by mean.
# Replace all null values for Categorical value by mode.
# customer details
customer_details.isna().sum()
# Drop Null values for customer_id because central tendencies for id’s is not feasible.
customer_details.dropna(subset=['Customer_id'], axis=0, inplace = True)
customer_details.reset_index(drop = True, inplace = True)
customer_details
| Customer_id | Gender | Age | Driving Licence Present | Region Code | Previously Insured | Vehicle Age | Vehicle Damage | |
|---|---|---|---|---|---|---|---|---|
| 0 | 0.0 | 1 | 2.0 | 3.0 | 4.0 | 5.0 | 6 | 7 |
| 1 | 1.0 | Male | 44.0 | 1.0 | 28.0 | 0.0 | > 2 Years | Yes |
| 2 | 2.0 | Male | 76.0 | 1.0 | 3.0 | 0.0 | 1-2 Year | No |
| 3 | 3.0 | Male | 47.0 | 1.0 | 28.0 | 0.0 | > 2 Years | Yes |
| 4 | 4.0 | Male | 21.0 | 1.0 | 11.0 | 1.0 | < 1 Year | No |
| ... | ... | ... | ... | ... | ... | ... | ... | ... |
| 380719 | 381105.0 | Male | 74.0 | 1.0 | 26.0 | 1.0 | 1-2 Year | No |
| 380720 | 381106.0 | Male | 30.0 | 1.0 | 37.0 | 1.0 | < 1 Year | No |
| 380721 | 381107.0 | Male | 21.0 | 1.0 | 30.0 | 1.0 | < 1 Year | No |
| 380722 | 381108.0 | Female | 68.0 | 1.0 | 14.0 | 0.0 | > 2 Years | Yes |
| 380723 | 381109.0 | Male | 46.0 | 1.0 | 29.0 | 0.0 | 1-2 Year | No |
customer_details.isna().sum()
Customer_id 0
Gender                     368
Age                        366
Driving Licence Present    392
Region Code                391
Previously Insured         381
Vehicle Age                381
Vehicle Damage             406
dtype: int64
customer_policy.isna().sum()
# Drop Null values for customer_id because central tendencies for id’s is not feasible.
customer_policy.dropna(subset=['Customer_id'], axis=0, inplace = True)
customer_policy.reset_index(drop = True, inplace = True)
customer_policy
| Customer_id | Annual Premium (in Rs) | Sales Channel Code | Vintage | Response | |
|---|---|---|---|---|---|
| 0 | 0.0 | 1.0 | 2.0 | 3.0 | 4.0 |
| 1 | 1.0 | 40454.0 | 26.0 | 217.0 | 1.0 |
| 2 | 2.0 | 33536.0 | 26.0 | 183.0 | 0.0 |
| 3 | 3.0 | 38294.0 | 26.0 | 27.0 | 1.0 |
| 4 | 4.0 | 28619.0 | 152.0 | 203.0 | 0.0 |
| ... | ... | ... | ... | ... | ... |
| 380718 | 381105.0 | 30170.0 | 26.0 | 88.0 | 0.0 |
| 380719 | 381106.0 | 40016.0 | 152.0 | 131.0 | 0.0 |
| 380720 | 381107.0 | 35118.0 | 160.0 | 161.0 | 0.0 |
| 380721 | 381108.0 | 44617.0 | 124.0 | 74.0 | 0.0 |
| 380722 | 381109.0 | 41777.0 | 26.0 | 237.0 | 0.0 |
380723 rows × 5 columns
In [68]:
# Replace all null values for numeric columns by mean.
customer_details['Age'].fillna(customer_details['Age'].mean(), inplace=True)
customer_details['Region Code'].fillna(customer_details['Region Code'].mean(), inplace=True)
customer_policy['Annual Premium (in Rs)'].fillna(customer_policy['Annual Premium (in Rs)'].mean(), inplace=True)
customer_policy['Vintage'].fillna(customer_policy['Vintage'].mean(), inplace=True)
# Replace all null values for Categorical value by mode.
customer_details['Driving Licence Present'].fillna(customer_details['Driving Licence Present'].mode()[0], inplace=True)
customer_details['Previously Insured'].fillna(customer_details['Previously Insured'].mode()[0], inplace=True)
customer_policy['Response'].fillna(customer_policy['Response'].mode()[0], inplace=True)
# customer_policy
customer_policy
| Customer_id | Annual Premium (in Rs) | Sales Channel Code | Vintage | Response | |
|---|---|---|---|---|---|
| 0 | 0.0 | 1.0 | 2.0 | 3.0 | 4.0 |
| 1 | 1.0 | 40454.0 | 26.0 | 217.0 | 1.0 |
| 2 | 2.0 | 33536.0 | 26.0 | 183.0 | 0.0 |
| 3 | 3.0 | 38294.0 | 26.0 | 27.0 | 1.0 |
| 4 | 4.0 | 28619.0 | 152.0 | 203.0 | 0.0 |
| ... | ... | ... | ... | ... | ... |
| 380718 | 381105.0 | 30170.0 | 26.0 | 88.0 | 0.0 |
| 380719 | 381106.0 | 40016.0 | 152.0 | 131.0 | 0.0 |
| 380720 | 381107.0 | 35118.0 | 160.0 | 161.0 | 0.0 |
| 380721 | 381108.0 | 44617.0 | 124.0 | 74.0 | 0.0 |
| 380722 | 381109.0 | 41777.0 | 26.0 | 237.0 | 0.0 |
customer_policy.isna().sum()
Customer_id                 0
Annual Premium (in Rs)      0
Sales Channel Code        400
Vintage                     0
Response                    0
dtype: int64
# ii. Outliers
# Generate a summary of count of all the outliers column wise
# Replace all outlier values for numeric columns by mean.
# (Hint1: for outlier treatment use IQR method as follows:
# For example: for a column X calculate Q1 = 25th percentile and Q3 = 75th percentile then IQR = Q3 – Q1 )
# then to check outlier, anything lower than a Q1 – 1.5IQR or greater than Q3 + 1.5 IQR would be an outlier
# Hint2: For getting percentile value, explore pd.describe() function)
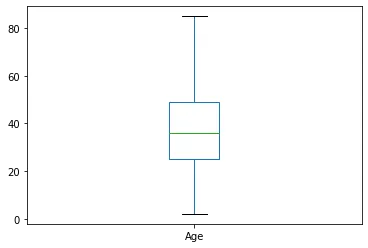
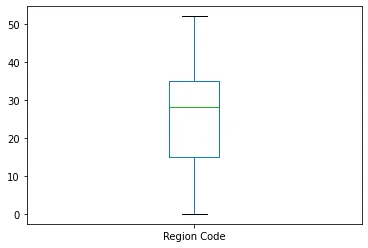
customer_details.describe()[['Age','Region Code']]
| Age | Region Code | |
|---|---|---|
| count | 380724.000000 | 380724.000000 |
| mean | 38.822691 | 26.389377 |
| std | 15.504920 | 13.223703 |
| min | 2.000000 | 0.000000 |
| 25% | 25.000000 | 15.000000 |
| 50% | 36.000000 | 28.000000 |
| 75% | 49.000000 | 35.000000 |
| max | 85.000000 | 52.000000 |
# vizualize using box plot
import matplotlib.pyplot as plt
def boxPlot(df, col):
df.boxplot(column=[col])
plt.grid(False)
plt.show()
boxPlot(customer_details, 'Age')
boxPlot(customer_details, 'Region Code')
def find_outliers_IQR(df):
q1 = df.quantile(0.25)
q3 = df.quantile(0.75)
IQR = q3 - q1
outliers = df[((df<(q1-1.5*IQR)) | (df>(q3+1.5*IQR)))]
return outliers
outliers = find_outliers_IQR(customer_details["Age"])
print("Number of outliers:",str(len(outliers)))
print("Maximum of outliers:",str(outliers.max()))
print("Minimum of outliers:",str(outliers.min()))
outliers
Number of outliers: 0
Maximum of outliers: nan
Minimum of outliers: nan
Series([], Name: Age, dtype: float64)
outliers = find_outliers_IQR(customer_details["Region Code"])
print("Number of outliers:",str(len(outliers)))
print("Maximum of outliers:",str(outliers.max()))
print("Minimum of outliers:",str(outliers.min()))
outliers
Number of outliers: 0
Maximum of outliers: nan
Minimum of outliers: nan
Series([], Name: Region Code, dtype: float64)
# customer_policy
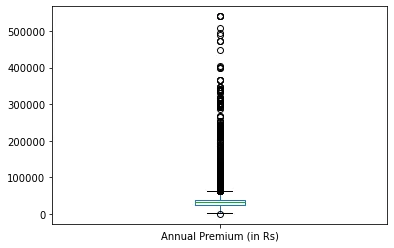
boxPlot(customer_policy, 'Annual Premium (in Rs)')
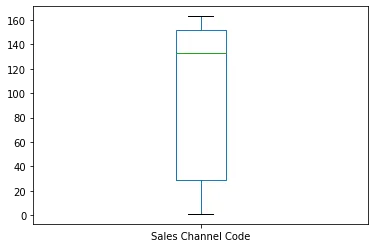
boxPlot(customer_policy, 'Sales Channel Code')
boxPlot(customer_policy, 'Vintage')
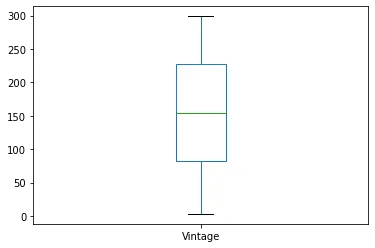
outliers = find_outliers_IQR(customer_policy["Annual Premium (in Rs)"])
print("Number of outliers:",str(len(outliers)))
print("Maximum of outliers:",str(outliers.max()))
print("Minimum of outliers:",str(outliers.min()))
outliers
Number of outliers: 10333
Maximum of outliers: 540165.0
Minimum of outliers: 1.0
0              1.0
26         61964.0
38         76251.0
68         66338.0
140        62164.0
            ...
380573     61909.0
380612    101664.0
380649     62889.0
380661     71915.0
380693     69845.0
Name: Annual Premium (in Rs), Length: 10333, dtype: float64
outliers = find_outliers_IQR(customer_policy["Sales Channel Code"])
print("Number of outliers:",str(len(outliers)))
print("Maximum of outliers:",str(outliers.max()))
print("Minimum of outliers:",str(outliers.min()))
outliers
Number of outliers: 0
Maximum of outliers: nan
Minimum of outliers: nan
Series([], Name: Sales Channel Code, dtype: float64)
outliers = find_outliers_IQR(customer_policy["Vintage"])
print("Number of outliers:",str(len(outliers)))
print("Maximum of outliers:",str(outliers.max()))
print("Minimum of outliers:",str(outliers.min()))
outliers
Number of outliers: 0
Maximum of outliers: nan
Minimum of outliers: nan
Series([], Name: Vintage, dtype: float64)
# Replace all outlier values for numeric columns by mean.
import numpy as np
def replace_outliers_IQR(df):
q1=df.quantile(0.25)
q3=df.quantile(0.75)
IQR=q3-q1
upper = df[~(df>(q3+1.5*IQR))].max()
lower = df[~(df<(q1-1.5*IQR))].min()
df = np.where(df > upper,df.mean(),np.where(df < lower,df.mean(),df))
return df
customer_policy['Annual Premium (in Rs)'] = replace_outliers_IQR(customer_policy['Annual Premium (in Rs)'])
customer_policy.describe()['Annual Premium (in Rs)']
count    380723.000000
mean      29299.494083
std       14532.794418
min        2630.000000
25%       24416.000000
50%       30949.000000
75%       38335.000000
max       61854.000000
Name: Annual Premium (in Rs), dtype: float64
customer_policy
| Customer_id | Annual Premium (in Rs) | Sales Channel Code | Vintage | Response | |
|---|---|---|---|---|---|
| 0 | 0.0 | 30563.919425 | 2.0 | 3.0 | 4.0 |
| 1 | 1.0 | 40454.000000 | 26.0 | 217.0 | 1.0 |
| 2 | 2.0 | 33536.000000 | 26.0 | 183.0 | 0.0 |
| 3 | 3.0 | 38294.000000 | 26.0 | 27.0 | 1.0 |
| 4 | 4.0 | 28619.000000 | 152.0 | 203.0 | 0.0 |
| ... | ... | ... | ... | ... | ... |
| 380718 | 381105.0 | 30170.000000 | 26.0 | 88.0 | 0.0 |
| 380719 | 381106.0 | 40016.000000 | 152.0 | 131.0 | 0.0 |
| 380720 | 381107.0 | 35118.000000 | 160.0 | 161.0 | 0.0 |
| 380721 | 381108.0 | 44617.000000 | 124.0 | 74.0 | 0.0 |
| 380722 | 381109.0 | 41777.000000 | 26.0 | 237.0 | 0.0 |
# iii. White spaces
# Remove white spaces
customer_details.apply(lambda x : x.str.strip() if x.dtype == 'object' else x)
| Customer_id | Gender | Age | Driving Licence Present | Region Code | Previously Insured | Vehicle Age | Vehicle Damage | |
|---|---|---|---|---|---|---|---|---|
| 0 | 0.0 | 1 | 2.0 | 3.0 | 4.0 | 5.0 | 6 | 7 |
| 1 | 1.0 | Male | 44.0 | 1.0 | 28.0 | 0.0 | > 2 Years | Yes |
| 2 | 2.0 | Male | 76.0 | 1.0 | 3.0 | 0.0 | 1-2 Year | No |
| 3 | 3.0 | Male | 47.0 | 1.0 | 28.0 | 0.0 | > 2 Years | Yes |
| 4 | 4.0 | Male | 21.0 | 1.0 | 11.0 | 1.0 | < 1 Year | No |
| ... | ... | ... | ... | ... | ... | ... | ... | ... |
| 380719 | 381105.0 | Male | 74.0 | 1.0 | 26.0 | 1.0 | 1-2 Year | No |
| 380720 | 381106.0 | Male | 30.0 | 1.0 | 37.0 | 1.0 | < 1 Year | No |
| 380721 | 381107.0 | Male | 21.0 | 1.0 | 30.0 | 1.0 | < 1 Year | No |
| 380722 | 381108.0 | Female | 68.0 | 1.0 | 14.0 | 0.0 | > 2 Years | Yes |
| 380723 | 381109.0 | Male | 46.0 | 1.0 | 29.0 | 0.0 | 1-2 Year | No |
customer_policy.apply(lambda x : x.str.strip() if x.dtype == 'object' else x)
| Customer_id | Annual Premium (in Rs) | Sales Channel Code | Vintage | Response | |
|---|---|---|---|---|---|
| 0 | 0.0 | 30563.919425 | 2.0 | 3.0 | 4.0 |
| 1 | 1.0 | 40454.000000 | 26.0 | 217.0 | 1.0 |
| 2 | 2.0 | 33536.000000 | 26.0 | 183.0 | 0.0 |
| 3 | 3.0 | 38294.000000 | 26.0 | 27.0 | 1.0 |
| 4 | 4.0 | 28619.000000 | 152.0 | 203.0 | 0.0 |
| ... | ... | ... | ... | ... | ... |
| 380718 | 381105.0 | 30170.000000 | 26.0 | 88.0 | 0.0 |
| 380719 | 381106.0 | 40016.000000 | 152.0 | 131.0 | 0.0 |
| 380720 | 381107.0 | 35118.000000 | 160.0 | 161.0 | 0.0 |
| 380721 | 381108.0 | 44617.000000 | 124.0 | 74.0 | 0.0 |
| 380722 | 381109.0 | 41777.000000 | 26.0 | 237.0 | 0.0 |
# case correction(lower or upper, any one)
customer_details.apply(lambda x : x.str.upper() if x.dtype == 'object' else x)
| Customer_id | Gender | Age | Driving Licence Present | Region Code | Previously Insured | Vehicle Age | Vehicle Damage | |
|---|---|---|---|---|---|---|---|---|
| 0 | 0.0 | 1 | 2.0 | 3.0 | 4.0 | 5.0 | 6 | 7 |
| 1 | 1.0 | MALE | 44.0 | 1.0 | 28.0 | 0.0 | > 2 YEARS | YES |
| 2 | 2.0 | MALE | 76.0 | 1.0 | 3.0 | 0.0 | 1-2 YEAR | NO |
| 3 | 3.0 | MALE | 47.0 | 1.0 | 28.0 | 0.0 | > 2 YEARS | YES |
| 4 | 4.0 | MALE | 21.0 | 1.0 | 11.0 | 1.0 | < 1 YEAR | NO |
| ... | ... | ... | ... | ... | ... | ... | ... | ... |
| 380719 | 381105.0 | MALE | 74.0 | 1.0 | 26.0 | 1.0 | 1-2 YEAR | NO |
| 380720 | 381106.0 | MALE | 30.0 | 1.0 | 37.0 | 1.0 | < 1 YEAR | NO |
| 380721 | 381107.0 | MALE | 21.0 | 1.0 | 30.0 | 1.0 | < 1 YEAR | NO |
| 380722 | 381108.0 | FEMALE | 68.0 | 1.0 | 14.0 | 0.0 | > 2 YEARS | YES |
| 380723 | 381109.0 | MALE | 46.0 | 1.0 | 29.0 | 0.0 | 1-2 YEAR | NO |
# Convert nominal data (categorical) into dummies
# for future modeling use if required
dummy_variable = pd.get_dummies(customer_details['Vehicle Damage'])
dummy_variable.rename(columns={'No':'Vehicle Damage - No','Yes':'Vehicle Damage - Yes'}, inplace = True)
dummy_variable.head(5)
| 7 | Vehicle Damage - No | Vehicle Damage - Yes | |
|---|---|---|---|
| 0 | 1 | 0 | 0 |
| 1 | 0 | 0 | 1 |
| 2 | 0 | 1 | 0 |
| 3 | 0 | 0 | 1 |
| 4 | 0 | 1 | 0 |
customer_details = pd.concat([customer_details, dummy_variable], axis = 1)
customer_details.head(5)
| Customer_id | Gender | Age | Driving Licence Present | Region Code | Previously Insured | Vehicle Age | Vehicle Damage | 7 | Vehicle Damage - No | Vehicle Damage - Yes | |
|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | 0.0 | 1 | 2.0 | 3.0 | 4.0 | 5.0 | 6 | 7 | 1 | 0 | 0 |
| 1 | 1.0 | Male | 44.0 | 1.0 | 28.0 | 0.0 | > 2 Years | Yes | 0 | 0 | 1 |
| 2 | 2.0 | Male | 76.0 | 1.0 | 3.0 | 0.0 | 1-2 Year | No | 0 | 1 | 0 |
| 3 | 3.0 | Male | 47.0 | 1.0 | 28.0 | 0.0 | > 2 Years | Yes | 0 | 0 | 1 |
| 4 | 4.0 | Male | 21.0 | 1.0 | 11.0 | 1.0 | < 1 Year | No | 0 | 1 | 0 |
customer_details.drop("Vehicle Damage", axis = 1, inplace =True)
customer_details.head(5)
| Customer_id | Gender | Age | Driving Licence Present | Region Code | Previously Insured | Vehicle Age | 7 | Vehicle Damage - No | Vehicle Damage - Yes | |
|---|---|---|---|---|---|---|---|---|---|---|
| 0 | 0.0 | 1 | 2.0 | 3.0 | 4.0 | 5.0 | 6 | 1 | 0 | 0 |
| 1 | 1.0 | Male | 44.0 | 1.0 | 28.0 | 0.0 | > 2 Years | 0 | 0 | 1 |
| 2 | 2.0 | Male | 76.0 | 1.0 | 3.0 | 0.0 | 1-2 Year | 0 | 1 | 0 |
| 3 | 3.0 | Male | 47.0 | 1.0 | 28.0 | 0.0 | > 2 Years | 0 | 0 | 1 |
| 4 | 4.0 | Male | 21.0 | 1.0 | 11.0 | 1.0 | < 1 Year | 0 | 1 | 0 |
# Drop Duplicates (duplicated rows)
customer_details.drop_duplicates(inplace = True)
customer_details
| Customer_id | Gender | Age | Driving Licence Present | Region Code | Previously Insured | Vehicle Age | 7 | Vehicle Damage - No | Vehicle Damage - Yes | |
|---|---|---|---|---|---|---|---|---|---|---|
| 0 | 0.0 | 1 | 2.0 | 3.0 | 4.0 | 5.0 | 6 | 1 | 0 | 0 |
| 1 | 1.0 | Male | 44.0 | 1.0 | 28.0 | 0.0 | > 2 Years | 0 | 0 | 1 |
| 2 | 2.0 | Male | 76.0 | 1.0 | 3.0 | 0.0 | 1-2 Year | 0 | 1 | 0 |
| 3 | 3.0 | Male | 47.0 | 1.0 | 28.0 | 0.0 | > 2 Years | 0 | 0 | 1 |
| 4 | 4.0 | Male | 21.0 | 1.0 | 11.0 | 1.0 | < 1 Year | 0 | 1 | 0 |
| ... | ... | ... | ... | ... | ... | ... | ... | ... | ... | ... |
| 380719 | 381105.0 | Male | 74.0 | 1.0 | 26.0 | 1.0 | 1-2 Year | 0 | 1 | 0 |
| 380720 | 381106.0 | Male | 30.0 | 1.0 | 37.0 | 1.0 | < 1 Year | 0 | 1 | 0 |
| 380721 | 381107.0 | Male | 21.0 | 1.0 | 30.0 | 1.0 | < 1 Year | 0 | 1 | 0 |
| 380722 | 381108.0 | Female | 68.0 | 1.0 | 14.0 | 0.0 | > 2 Years | 0 | 0 | 1 |
| 380723 | 381109.0 | Male | 46.0 | 1.0 | 29.0 | 0.0 | 1-2 Year | 0 | 1 | 0 |
customer_policy.drop_duplicates(inplace = True)
customer_policy
| Customer_id | Annual Premium (in Rs) | Sales Channel Code | Vintage | Response | |
|---|---|---|---|---|---|
| 0 | 0.0 | 30563.919425 | 2.0 | 3.0 | 4.0 |
| 1 | 1.0 | 40454.000000 | 26.0 | 217.0 | 1.0 |
| 2 | 2.0 | 33536.000000 | 26.0 | 183.0 | 0.0 |
| 3 | 3.0 | 38294.000000 | 26.0 | 27.0 | 1.0 |
| 4 | 4.0 | 28619.000000 | 152.0 | 203.0 | 0.0 |
| ... | ... | ... | ... | ... | ... |
| 380718 | 381105.0 | 30170.000000 | 26.0 | 88.0 | 0.0 |
| 380719 | 381106.0 | 40016.000000 | 152.0 | 131.0 | 0.0 |
| 380720 | 381107.0 | 35118.000000 | 160.0 | 161.0 | 0.0 |
| 380721 | 381108.0 | 44617.000000 | 124.0 | 74.0 | 0.0 |
| 380722 | 381109.0 | 41777.000000 | 26.0 | 237.0 | 0.0 |
# Create a Master table for future use. Join the customer table and customer_policy table to get a master table using customer_id in both tables.
# (Hint: use pd.merge() function)
master_table = pd.merge(customer_details, customer_policy, on = 'Customer_id')
master_table.head(10)
| Customer_id | Gender | Age | Driving Licence Present | Region Code | Previously Insured | Vehicle Age | 7 | Vehicle Damage - No | Vehicle Damage - Yes | Annual Premium (in Rs) | Sales Channel Code | Vintage | Response | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| 0 | 0.0 | 1 | 2.0 | 3.0 | 4.0 | 5.0 | 6 | 1 | 0 | 0 | 30563.919425 | 2.0 | 3.0 | 4.0 |
| 1 | 1.0 | Male | 44.0 | 1.0 | 28.0 | 0.0 | > 2 Years | 0 | 0 | 1 | 40454.000000 | 26.0 | 217.0 | 1.0 |
| 2 | 2.0 | Male | 76.0 | 1.0 | 3.0 | 0.0 | 1-2 Year | 0 | 1 | 0 | 33536.000000 | 26.0 | 183.0 | 0.0 |
| 3 | 3.0 | Male | 47.0 | 1.0 | 28.0 | 0.0 | > 2 Years | 0 | 0 | 1 | 38294.000000 | 26.0 | 27.0 | 1.0 |
| 4 | 4.0 | Male | 21.0 | 1.0 | 11.0 | 1.0 | < 1 Year | 0 | 1 | 0 | 28619.000000 | 152.0 | 203.0 | 0.0 |
| 5 | 5.0 | Female | 29.0 | 1.0 | 41.0 | 1.0 | < 1 Year | 0 | 1 | 0 | 27496.000000 | 152.0 | 39.0 | 0.0 |
| 6 | 6.0 | Female | 24.0 | 1.0 | 33.0 | 0.0 | < 1 Year | 0 | 0 | 1 | 2630.000000 | 160.0 | 176.0 | 0.0 |
| 7 | 7.0 | Male | 23.0 | 1.0 | 11.0 | 0.0 | < 1 Year | 0 | 0 | 1 | 23367.000000 | 152.0 | 249.0 | 0.0 |
| 8 | 8.0 | Female | 56.0 | 1.0 | 28.0 | 0.0 | 1-2 Year | 0 | 0 | 1 | 32031.000000 | 26.0 | 72.0 | 1.0 |
| 9 | 9.0 | Female | 24.0 | 1.0 | 3.0 | 1.0 | < 1 Year | 0 | 1 | 0 | 27619.000000 | 152.0 | 28.0 | 0.0 |
# 4. Company needs some important information from the master table to make decisions for future growth.
# They needs following information:
#i. Gender wise average annual premium
#ii. Age wise average annual premium
#iii. Is your data balanced between the genders?
#(Hint: Data is balanced if number of counts in each group is approximately same)
#iv. Vehicle age wise average annual premium.
#i. Gender wise average annual premium
master_table.groupby('Gender')['Annual Premium (in Rs)'].mean()
Gender
1         30563.919425
Female    29273.472077
Male      29323.020270
Name: Annual Premium (in Rs), dtype: float64
#ii. Age wise average annual premium
master_table.groupby('Age')['Annual Premium (in Rs)'].mean()
Age
2.0     30563.919425
20.0    26342.072366
21.0    29751.790433
22.0    29946.847046
23.0    29838.343223
            ...
81.0    29287.906398
82.0    36480.583428
83.0    28995.814519
84.0    35440.818182
85.0    26637.447220
Name: Annual Premium (in Rs), Length: 68, dtype: float64
#iii. Is your data balanced between the genders?
#(Hint: Data is balanced if number of counts in each group is approximately same)
master_table.groupby('Gender').count()
| Customer_id | Age | Driving Licence Present | Region Code | Previously Insured | Vehicle Age | 7 | Vehicle Damage - No | Vehicle Damage - Yes | Annual Premium (in Rs) | Sales Channel Code | Vintage | Response | |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Gender | |||||||||||||
| 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 | 1 |
| Female | 174485 | 174485 | 174485 | 174485 | 174485 | 174309 | 174485 | 174485 | 174485 | 174485 | 174284 | 174485 | 174485 |
| Male | 205484 | 205484 | 205484 | 205484 | 205484 | 205279 | 205484 | 205484 | 205484 | 205484 | 205288 | 205484 | 205484 |
#iv. Vehicle age wise average annual premium.
master_table.groupby('Vehicle Age')['Annual Premium (in Rs)'].mean()
Vehicle Age
1-2 Year     29099.064203
6            30563.919425
< 1 Year     29188.148950
> 2 Years    32943.535848
Name: Annual Premium (in Rs), dtype: float64
# 5. Is there any relation between Person Age and annual premium?
# Hint: use correlation function (Correlation describes the relationship between two variables).
# Correlation coefficient < -0.5 - Strong negative relationship
# Correlation coefficient > 0.5 - Strong positive relationship
# -0.5 < Correlation coefficient < 0.5 - There is no relationship.
master_table[['Age','Annual Premium (in Rs)']].corr()
| Age | Annual Premium (in Rs) | |
|---|---|---|
| Age | 1.000000 | 0.050657 |
| Annual Premium (in Rs) | 0.050657 | 1.000000 |